简体中文
 繁體中文
 English
 Français
 Русский
 日本語
 Tiếng Việt
 한국어
 Deutsch
 Español
 Italiano
 Português
 العربية
 ไทย
 Bahasa Indonesia
 Bahasa Melayu
 Türkçe
 Polski
 Nederlands
 Dansk
 Norsk
 Қазақша
AI API Error Handling in Production: Retries, Timeouts, and Fallbacks
Design resilient AI API clients with timeout budgets, error classification, exponential backoff, fallback models, and observable request IDs.
AI API Error Handling in Production: Retries, Timeouts, and Fallbacks#
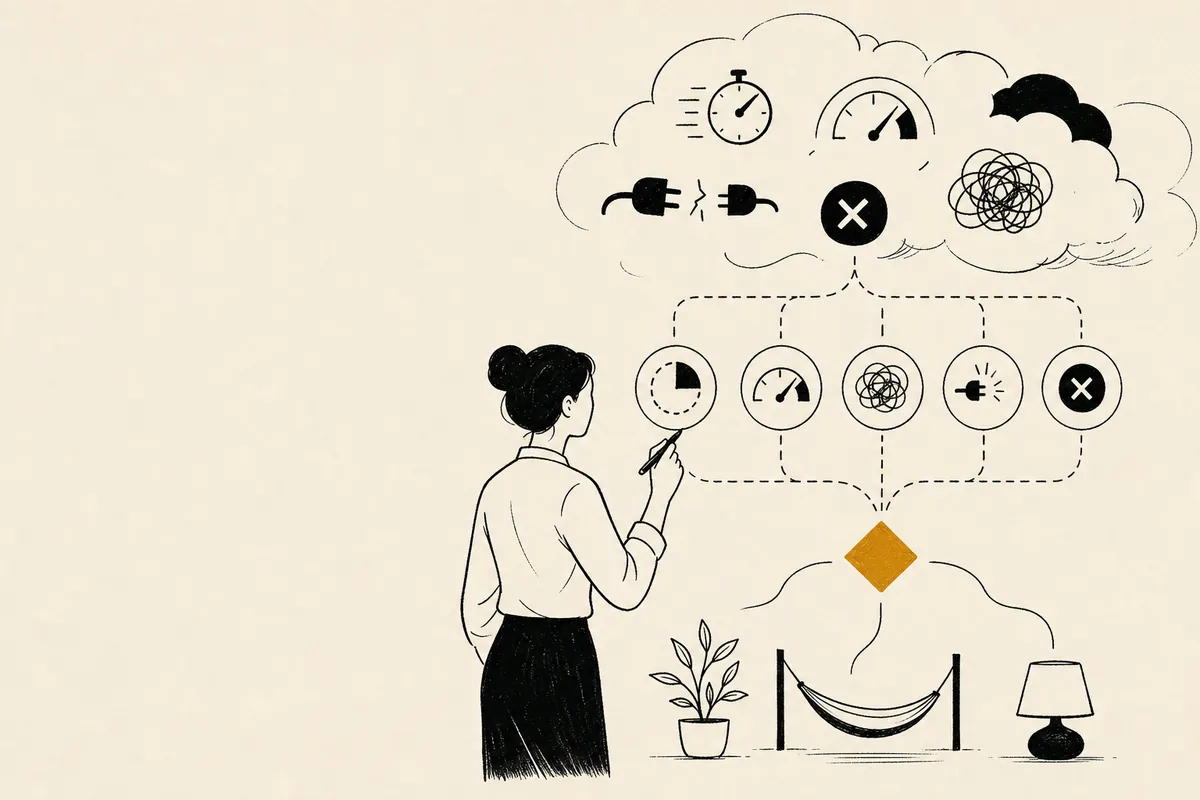
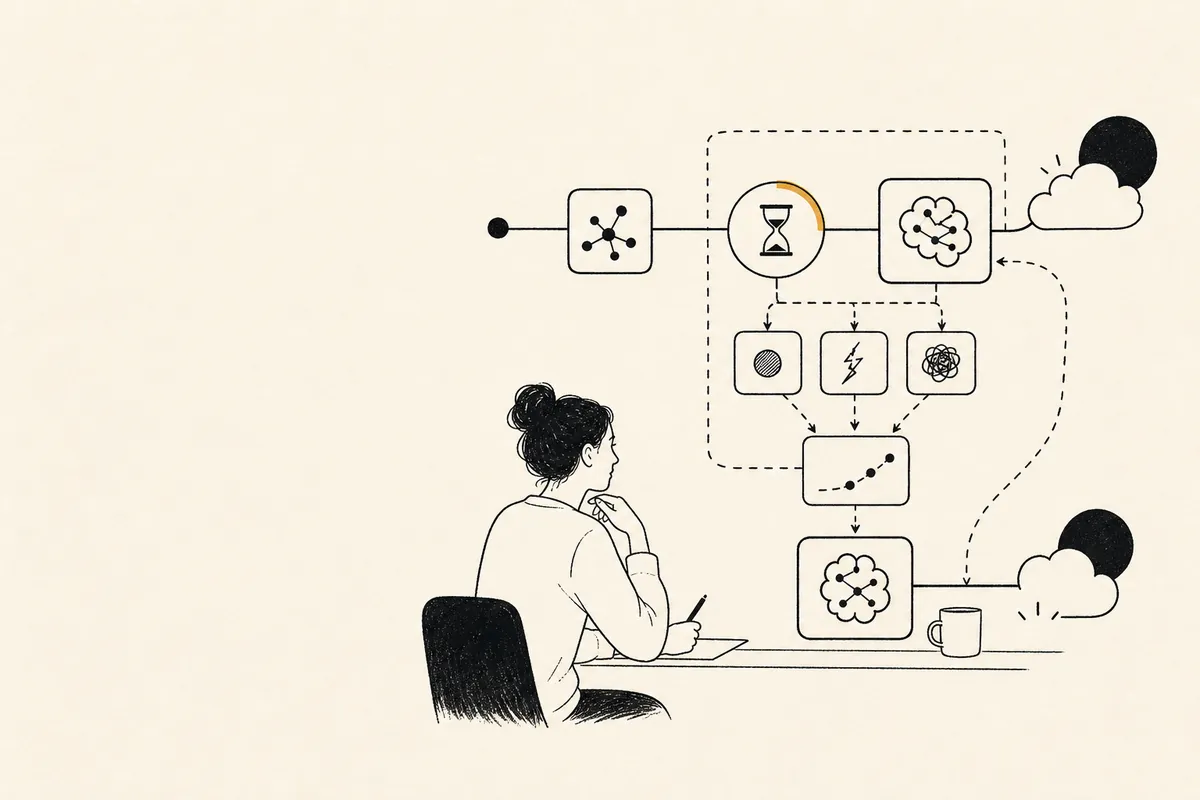
An AI API call can fail even when your code is correct. Providers return rate-limit responses, overloaded errors, validation failures, content-policy refusals, network timeouts, and partial streaming responses. Production reliability comes from classifying those failures and responding differently to each one.
What is AI API error handling?#
AI API error handling is the client and service logic that converts provider failures into safe, bounded application behavior. It includes timeout budgets, retry rules, fallback models, idempotency, user-facing messages, and logs. A retry is useful for transient overload; it is wasteful for an invalid request and dangerous for a non-idempotent tool call.
| Failure | Retry? | Correct response |
|---|---|---|
| 400 invalid request | No | Fix serialization or validation |
| 401/403 auth | No | Rotate or repair credentials |
| 429 rate limit | Yes, bounded | Honor Retry-After, then back off |
| 500/502/503 | Usually | Exponential backoff and fallback |
| Timeout | Sometimes | Retry only within a total deadline |
| Content refusal | No blind retry | Revise policy or explain limitation |
Set a total deadline, not just a socket timeout#
If a request has a ten-second user experience budget, three retries of ten seconds each are not resilient—they are a thirty-second outage. Pass a deadline through every layer and stop when it expires.
import os, time, random
from openai import OpenAI

client = OpenAI(api_key=os.environ["CRAZYROUTER_API_KEY"],
                base_url="https://crazyrouter.com/v1")

def complete(messages, deadline=12):
    end = time.monotonic() + deadline
    for attempt in range(3):
        remaining = end - time.monotonic()
        if remaining <= 0: raise TimeoutError("AI deadline exceeded")
        try:
            return client.chat.completions.create(
                model="gpt-5-mini", messages=messages,
                timeout=remaining, max_tokens=800)
        except Exception as exc:
            if attempt == 2: raise
            time.sleep(min(2 ** attempt + random.random(), max(0, remaining)))
In real code, use the SDK's typed exception classes rather than catching every exception. Retry only network errors, 429, and explicitly transient 5xx responses. Add jitter so many workers do not retry simultaneously.
Fallback models and semantic compatibility#
A fallback should be selected by capability, not by brand. A fast text model may replace another text model, but it may not support vision, JSON schema output, or the same context length. Store a capability matrix and test the fallback prompt against it. Keep the original request ID and record both attempts.
const fallback = { "gpt-5": "claude-sonnet-4-6", "gpt-5-mini": "gemini-2.5-flash" };
// Fallback only after a transient error; never after invalid arguments.
Pricing impact of retries#
| Strategy | Direct official API | Gateway such as Crazyrouter |
|---|---|---|
| Successful request | Official input/output rates | Current usage-based model rate |
| Failed before inference | Provider-dependent | Provider/gateway dependent |
| Retry cost | Your client pays for each successful attempt | Your client pays for each successful attempt |
| Failover engineering | Build provider routing | Centralize multi-model routing |
Review Crazyrouter pricing before forecasting. The cheapest reliability improvement is often reducing duplicate retries and setting max output tokens.
Observability checklist#
Every request should have a correlation ID that survives proxy, queue, provider, and application logs. Capture status code, provider request ID when available, selected model, attempt number, elapsed time, input and output token counts, and the final outcome. Redact prompt text and authorization headers by default. Build dashboards for p50/p95 latency, error rate by provider, retry rate, fallback rate, and cost per successful task.
For streaming, distinguish connection failure before the first token from failure after partial output. The client needs a terminal event and a way to retry safely. For asynchronous video or image jobs, persist state transitions such as queued, running, succeeded, failed, and expired; a webhook should be idempotent because delivery can repeat.
FAQ#
Should every AI API error be retried?#
No. Retry transient rate-limit, overload, and network failures only. Invalid requests, authentication errors, and policy refusals need a different fix.
How many retries are safe?#
Usually two or three attempts inside a total deadline, with exponential backoff and jitter. Queue-based jobs can use a longer policy than interactive requests.
What should users see during a provider outage?#
Return a clear temporary-failure message, a request ID, and a retry option. Do not expose provider stack traces or credentials.
Does streaming need special handling?#
Yes. Once bytes have been sent, you may not be able to replace the response cleanly. Emit a terminal error event and let the client resume or restart.
Can a gateway improve reliability?#
It can simplify multi-provider routing and failover, but your application still needs deadlines, idempotency, validation, and observability.
Summary#
Reliable AI applications classify errors, enforce a total deadline, retry only transient failures, and choose fallbacks by capability. Centralized routing through Crazyrouter can reduce provider-specific code while your service keeps control of safety and user experience.
Implementation Guides
Podcast
AI Dev Tools: The Crazyrouter Podcast
Short episodes for developers on AI APIs, gateways, cost control and coding tools.
Latest episodes
EP196 · Oct 29, 2026 · 6:53
AI API Security Posture — Turn Controls Into Continuous Evidence
A practical guide to AI API security posture: inventory exposure, verify controls continuously, protect keys and data, constrain tools, and turn security assumptions into evidence that operators can act on.
EP195 · Oct 28, 2026 · 7:21
AI API Policy Drift — Detect When Production Rules Stop Matching Intent
A practical guide to policy drift in AI APIs: version routing and safety rules, detect stale enforcement, compare intended and observed behavior, and restore control before small gaps become incidents.