简体中文
 繁體中文
 English
 Français
 Русский
 日本語
 Tiếng Việt
 한국어
 Deutsch
 Español
 Italiano
 Português
 العربية
 ไทย
 Bahasa Indonesia
 Bahasa Melayu
 Türkçe
 Polski
 Nederlands
 Dansk
 Norsk
 Қазақша
AI Structured Output in Python: JSON Mode, Schema, and Live Validation
Four live GPT-4.1-mini and Gemini requests show why HTTP 200 is not enough. Includes a runnable schema example, one fenced-JSON failure, and eight local validation checks.
Structured output needs three checks: the response finished, the text parses into the expected shape, and the extracted values match the source. JSON mode and JSON Schema requests address different parts of that contract. Neither an HTTP 200 nor a schema-shaped object proves that the facts are correct.
Crazyrouter is an AI API gateway where this four-request fixture produced three directly parseable, correct JSON objects and one Markdown-wrapped response that failed strict JSON parsing. The requests used GPT-4.1-mini and Gemini 2.5 Flash through Chat Completions. This small test describes these routes and inputs, not a provider reliability ranking.
By Sophie M · Tested November 3, 2026
JSON mode versus structured outputs#
The OpenAI structured-output documentation distinguishes JSON mode from schema adherence. The model, endpoint and supported schema subset still matter. Do not assume that sending an OpenAI-shaped parameter through a compatibility gateway guarantees identical native-provider behavior.
| Request or validation layer | Purpose | What you still check |
|---|---|---|
response_format: {"type":"json_object"} | Ask the compatible endpoint for JSON | Parsing, required keys, types, and facts |
response_format: {"type":"json_schema", ...} | Supply a schema to a supported endpoint | Completion/refusal, local validation, and facts |
| Local application validator | Reject objects outside your contract | Whether accepted values are supported by the source |
| Crazyrouter test route | Exercise these request shapes on selected models | Actual response behavior per model and route |
A successful schema request is useful evidence of the tested path, but it does not establish that every possible schema is supported or how enforcement is implemented internally.
Four live requests with one synthetic source#
We first checked that gpt-4.1-mini and gemini-2.5-flash appeared in the live model catalog, then called the Chat Completions endpoint (/v1/chat/completions) at https://api.crazyrouter.com once for each model/format pair. Each request used an output budget of 160 tokens and the same prompt:
Extract JSON from this synthetic fixture: ticket DEMO-42 has high priority and contains 3 items. Return ticket_id, priority, count only.
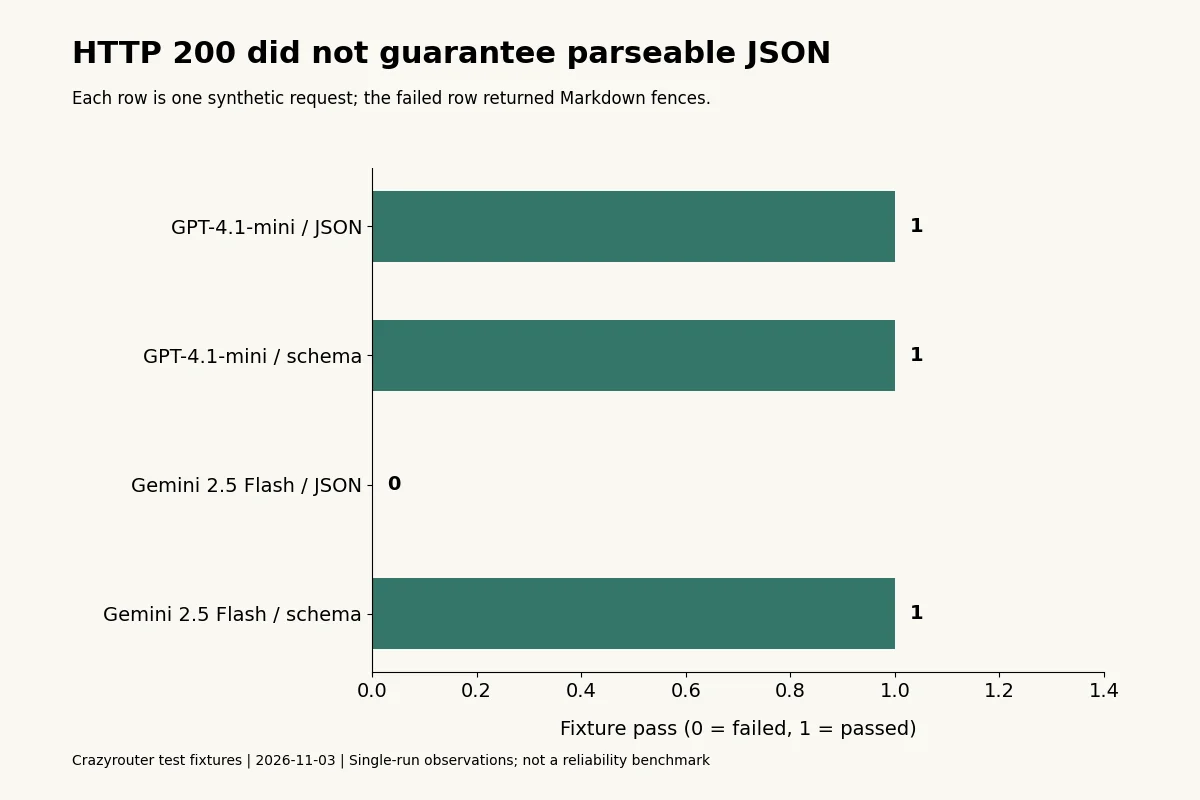
The expected object was {"ticket_id":"DEMO-42","priority":"high","count":3}. Passing required a completed response, no refusal, direct json.loads parsing, exactly those fields, an integer count, and the expected values. We did not strip Markdown or repair output before scoring it.
| Model | Requested format | HTTP | Direct parsing and fixture check | Observed wall time |
|---|---|---|---|---|
| GPT-4.1-mini | json_object | 200 | Passed | 1.138 s |
| GPT-4.1-mini | json_schema, strict | 200 | Passed | 1.397 s |
| Gemini 2.5 Flash | json_object | 200 | Failed: Markdown fences | 3.619 s |
| Gemini 2.5 Flash | json_schema, strict | 200 | Passed | 3.316 s |
These times include the observed request path and are single samples, not a speed benchmark. The Gemini JSON-mode response began with a fenced code block even though the enclosed fields were correct. Its finish_reason was stop; that still did not make the full response valid JSON. We did not trace which component in the routed stack caused this behavior.
Runnable Python example with explicit validation#
Save this program as structured_ticket.py, set CRAZYROUTER_API_KEY in the environment, and run python structured_ticket.py. It uses the Python standard library. The default model is GPT-4.1-mini; MODEL selects another model for a deliberate retest. A different model is not automatically covered by the results above.
"""Validate completion, JSON shape, and fixture facts independently."""
import json
import os
import urllib.request

SCHEMA = {'type': 'object', 'properties': {
    'ticket_id': {'type': 'string'},
    'priority': {'type': 'string', 'enum': ['low', 'high']},
    'count': {'type': 'integer'}},
    'required': ['ticket_id', 'priority', 'count'], 'additionalProperties': False}

def validate_ticket(value):
    if not isinstance(value, dict) or set(value) != {'ticket_id','priority','count'}:
        raise ValueError('missing or extra keys')
    if not isinstance(value['ticket_id'], str) or value['priority'] not in ('low','high'):
        raise ValueError('invalid ticket ID type or priority')
    if type(value['count']) is not int:  # bool is an int subclass in Python.
        raise ValueError('count must be an integer')
    return value

def parse_completion(response):
    choice = response['choices'][0]
    message = choice['message']
    if choice.get('finish_reason') != 'stop' or message.get('refusal'):
        raise ValueError('refused, truncated, or incomplete response')
    return validate_ticket(json.loads(message.get('content') or ''))

def main():
    model = os.getenv('MODEL', 'gpt-4.1-mini')
    base = os.getenv('CRAZYROUTER_BASE_URL', 'https://api.crazyrouter.com/v1')
    payload = {'model': model, 'max_tokens': 160,
        'response_format': {'type':'json_schema','json_schema':{
            'name':'ticket','strict':True,'schema':SCHEMA}},
        'messages':[{'role':'user','content':
            'Extract JSON from this synthetic fixture: ticket DEMO-42 has high '
            'priority and contains 3 items. Return ticket_id, priority, count only.'}]}
    request = urllib.request.Request(base.rstrip('/')+'/chat/completions',
        data=json.dumps(payload).encode(), headers={
            'Authorization':'Bearer '+os.environ['CRAZYROUTER_API_KEY'],
            'Content-Type':'application/json'})
    with urllib.request.urlopen(request,timeout=45) as response:
        envelope = json.load(response)
    data = parse_completion(envelope)
    if data != {'ticket_id':'DEMO-42','priority':'high','count':3}:
        raise ValueError('valid shape, but fixture facts do not match')
    print(json.dumps({'response_id':envelope['id'],'data':data}))

if __name__ == '__main__':
    main()
The exact standalone program also completed successfully in a separate run, with response ID chatcmpl-Eg5MOUBhDy4zAlsqhMQGg3XI6E2TX. That run is additional validation of the example, not another row in the four-request matrix. Its output matched all three fixture facts.
The helper validates this ticket contract only; it is not a general JSON Schema engine. type(value['count']) is int intentionally rejects booleans, since Python treats bool as a subclass of int. For a larger contract, use a maintained schema validator and test its coercion and strictness settings. Keep required fields and unknown-field handling explicit.
Negative cases the application rejected#
We executed eight local validation cases against the same parser: one valid object and seven invalid or incomplete envelopes. These are controlled application tests, separate from the four model requests.
| Case | Application result |
|---|---|
| Completed response with correct fields and types | Accepted |
| Correct object inside Markdown fences | Rejected |
| Missing required fields | Rejected |
| String instead of integer count | Rejected |
| Boolean instead of integer count | Rejected |
| Additional unexpected field | Rejected |
finish_reason: length | Rejected |
| Explicit refusal | Rejected |
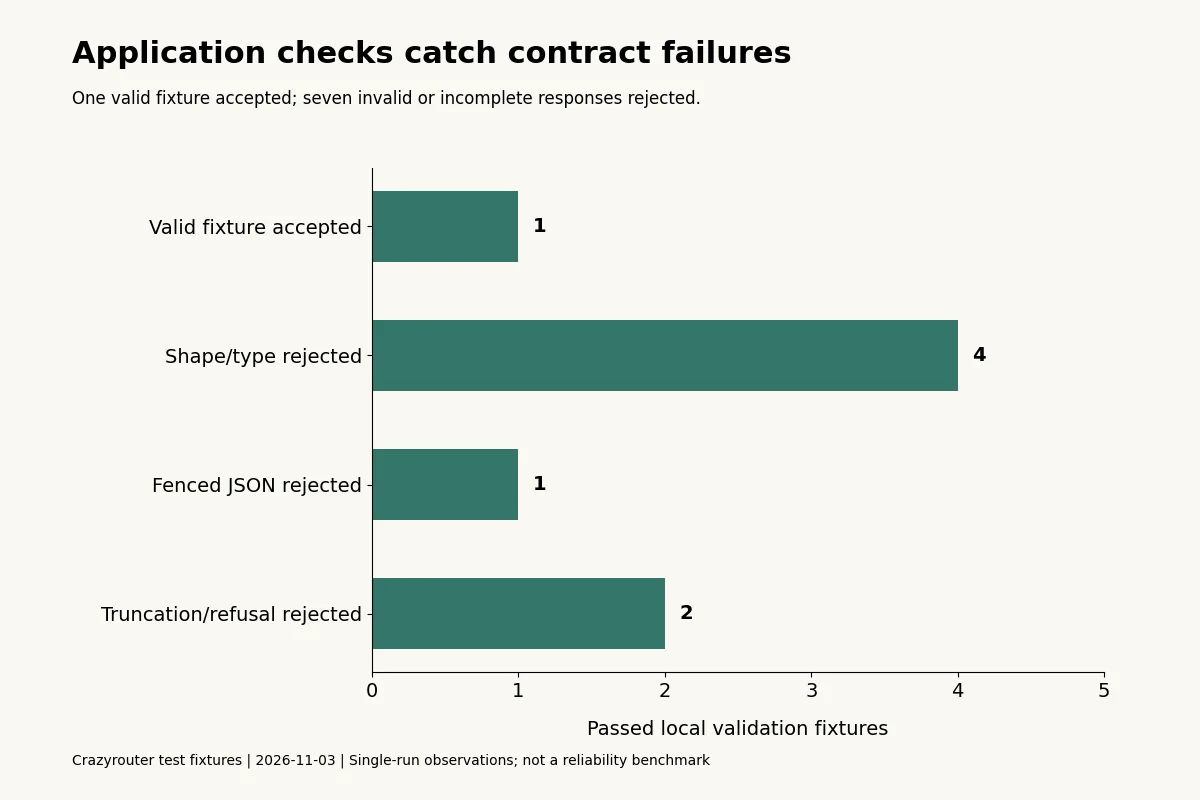
The code additionally compares the parsed object with the known fixture facts. In a real extraction task, choose domain checks appropriate to the source: reference matching, allowed identifiers, ranges, totals or a review path. A plausible number can pass structural validation and still be false.
OpenAI, Claude, and Gemini use different native contracts#
The current official documents describe structured-output options for all three providers. Check the native request format before moving a schema between endpoints.
| Native interface | Documented output configuration | Coverage in this article |
|---|---|---|
| OpenAI Chat Completions | response_format with supported JSON Schema | Tested compatible route with GPT-4.1-mini |
| OpenAI Responses | Its own text-format configuration | Documentation only; not tested here |
| Claude Messages | output_config.format for JSON outputs | Documentation only; no native Claude schema test here |
| Gemini native API | Structured output with a supported JSON Schema | Documentation only; the live test used a compatible Chat Completions route |
Use the Claude structured-output guide and Gemini structured-output guide for model availability and schema limitations. Those documents were retrieved on November 3, 2026. Native parameters should not be copied into an unrelated endpoint unchanged. The API protocol comparison provides context for endpoint selection.
Tool arguments and final structured answers are also different outputs. If the model requests a tool, validate the arguments and authorization before execution, then preserve the correct tool-result correlation. See tool-use ID validation for a separately tested native tool round trip.
Failure handling without silent repair#
Classify the failure before deciding to retry. Unsupported schemas and invalid requests require a configuration change. Authentication failures require credential repair. Truncated output may require a smaller task or a suitable output budget. A refusal is a distinct outcome; do not convert it to an empty successful object.
If your product deliberately accepts Markdown-wrapped JSON, implement that as a separate, logged normalization policy, then validate the normalized object. Do not label normalization as successful strict JSON output in a benchmark. The example here rejects fences so that unexpected behavior remains visible.
Record the endpoint, requested model, response ID, finish reason, parsing outcome and validation outcome. Avoid logging private source text by default. The request logging guide distinguishes HTTP success from completed tasks, while the retry guide covers deadlines and safe replay. If you cache results, cache only after your validator accepts them; the exact-response cache example demonstrates that boundary.
Frequently asked questions#
Is JSON mode the same as JSON Schema enforcement?#
No. JSON mode and schema adherence are distinct contracts. Check the chosen endpoint and model, and retain local validation for the application's requirements.
Does HTTP 200 mean I can call json.loads safely?#
No. One live response in this fixture returned Markdown-wrapped JSON with HTTP 200. Direct parsing rejected it.
Do these results rank GPT and Gemini reliability?#
No. Each row is one request on one routed path. A reliability comparison requires a representative dataset, repeated runs and a controlled configuration.
Does Claude support native structured outputs?#
Its current documentation describes JSON outputs using output_config.format. Check current supported models and constraints. This article does not claim to have tested that native interface.
Can I discard unexpected fields and call the result valid?#
That is a transformation policy, not strict acceptance of the returned contract. Decide it explicitly, retain relevant diagnostics, and validate after transformation if your application permits it.
Why validate facts after validating types?#
A ticket ID can be a string and still reference the wrong ticket. A count can be an integer and still contradict the source. Structural validity is necessary for this workflow but does not prove correctness.
Implementation Guides
Podcast
AI Dev Tools: The Crazyrouter Podcast
Short episodes for developers on AI APIs, gateways, cost control and coding tools.
Latest episodes
EP196 · Oct 29, 2026 · 6:53
AI API Security Posture — Turn Controls Into Continuous Evidence
A practical guide to AI API security posture: inventory exposure, verify controls continuously, protect keys and data, constrain tools, and turn security assumptions into evidence that operators can act on.
EP195 · Oct 28, 2026 · 7:21
AI API Policy Drift — Detect When Production Rules Stop Matching Intent
A practical guide to policy drift in AI APIs: version routing and safety rules, detect stale enforcement, compare intended and observed behavior, and restore control before small gaps become incidents.