 Crazyrouter
AI API Caching and Context Optimization: Lower Latency and Cost
Learn how prompt caching, semantic caching, context pruning, and retrieval reduce AI API latency and spend without sacrificing answer quality.
September 19, 20262 viewsEnglishTips
Compare leading AI models across reasoning, coding, multimodal output, latency, pricing, and upgrade decisions.
Learn how prompt caching, semantic caching, context pruning, and retrieval reduce AI API latency and spend without sacrificing answer quality.
A benchmark that tests only accuracy will miss latency, cost, refusal behavior, schema validity, and regression risk. Build a versioned evaluation set from
Compare open-weight and commercial AI models across cost, quality, privacy, operations, licensing, and API integration.
Compare routing, fallback, cascade, ensemble, and specialist patterns for coordinating multiple AI models in production.
Learn how to design portable function calling across OpenAI-compatible, Anthropic, Gemini, and open-model APIs with schemas, validation, retries, and routing.
Same Claude, GPT and Gemini models, but 35–45% below list price with zero top-up fees; no tiered rate limits, custom RPM on request; and a real human who follows up on every error. A side-by-side look with concrete prices.
Build reliable Kimi K2 Thinking applications with explicit reasoning budgets, tool-call validation, evaluation sets, and cost controls.
Compare AI lip sync tools for developers using phoneme drift, frame alignment, multilingual dubbing, API control, and production QA.
A secure setup guide for obtaining and using a Claude API key across local development, devcontainers, and CI without committing secrets.
Compare AI API pricing by successful task, latency, caching, retries, and routing policy instead of token price alone.
A developer-focused Gemini Advanced review covering long-context analysis, RAG prototyping, subscription versus API economics, and production handoff.
A practical developer guide to estimating Claude Code costs by repository, workflow, seat, and CI job, with budget controls and API routing patterns.

29 graded items, real API calls. claude-fable-5-1 scored 29/29, gpt-6-astra 16/29. astra emits 0.38-0.77x the output characters, but much of that gap is incompleteness rather than concision — on a three-way tie it named one answer in 5 of 6 runs, and 2 of those named a rule that is factually wrong. On a planted false premise it went along with the premise 5 times out of 6. Includes the three preconditions for valid cross-family comparison.
Compare open source and commercial AI models across cost, privacy, quality, latency, operations, licensing, and API integration.
Build reliable multi-model AI systems with task routing, fallbacks, cost controls, evaluation, and a unified API layer.
Design portable function calling across OpenAI-compatible, Claude, Gemini, and open-model APIs with schemas, validation, retries, and fallbacks.
Install and evaluate Gemini CLI, compare it with Claude Code and Codex CLI, and connect reliable Gemini API workflows to your developer tools.
A developer-focused Pika 2.2 review covering video generation use cases, alternatives, API integration patterns, pricing questions, and production tips.
Learn what Qwen2.5-Omni is, how it compares with GPT-4o and Gemini, how to call a multimodal model, and how to control API cost in production.

We pinned claude-fable-5-1 and claude-fable-5 to the same upstream route and ran three workload shapes three times each, recording correctness, output tokens, thinking budget and latency. Correctness tied 3:3 in every group; 5.1 reached the same answers on 0.372/0.744/0.891x the output tokens; and all seven documented breaking changes returned 200 instead of 400.
Use Kimi K2 Thinking for auditable reasoning tasks with bounded tool calls, evaluation sets, and cost-aware routing.
Compare AI lip sync tools for developers building dubbing, avatar, and localization pipelines with measurable QA gates.
Learn how to get a Claude API key, configure it safely, test the first request, and avoid leaking credentials in Git or CI logs.
Compare AI API pricing by tokens, cached context, retries, latency, and routing instead of relying on headline input rates.
A developer-focused Gemini Advanced review covering research, coding, context, subscription value, API economics, and practical alternatives.
A practical Claude Code pricing guide for solo developers and teams, covering subscriptions, API usage, CI budgets, and routing controls.
Build a practical test and evaluation system for AI APIs with fixtures, schema checks, regression sets, latency budgets, and human review.
Compare open source and commercial AI models by cost, quality, deployment, privacy, latency, and maintenance burden.
Compare routing, cascade, ensemble, and specialist orchestration patterns for building reliable multi-model AI applications.
Build portable tool calling across OpenAI-compatible, Anthropic, and Gemini-style APIs with schemas, adapters, validation, and retries.
"A developer-focused Kimi K2 Thinking guide covering reasoning prompts, tool calling, evaluation, latency, and cost-aware routing."
"Understand Seedance and ByteDance video AI, compare it with Veo3 and Kling, and design an API pipeline for controlled production."
"Compare AI lip sync tools for developers by API design, timing quality, multilingual support, and automated production QA."
"Learn how to get a Claude API key, configure it safely, rotate credentials, and use an OpenAI-compatible router for team deployments."
"Compare AI API pricing in 2026 using effective cost per task, including cache hits, retries, fallback models, and Crazyrouter routing."
"Review Gemini Advanced for coding, research, and API workflows in 2026. Compare subscription value with usage-based API access and multi-model routing."
"A practical Claude Code pricing guide for solo developers and teams, covering subscriptions, API usage, CI agents, budgeting, and routing strategies."
Design production-ready multi-model orchestration with routing policies, fallbacks, evaluation gates, observability, and one OpenAI-compatible integration.
AI API pricing comparison 2026 for developers: compare official provider billing with gateway economics across text, vision, audio, and video workloads.
Pika 2.2 review for developers: evaluate text-to-video and image-to-video workflows, compare alternatives, estimate costs, and connect through Crazyrouter.
Qwen2.5-Omni developer guide: learn how to design multimodal audio, vision, and text workflows, compare routing options, and integrate an OpenAI-compatible API.
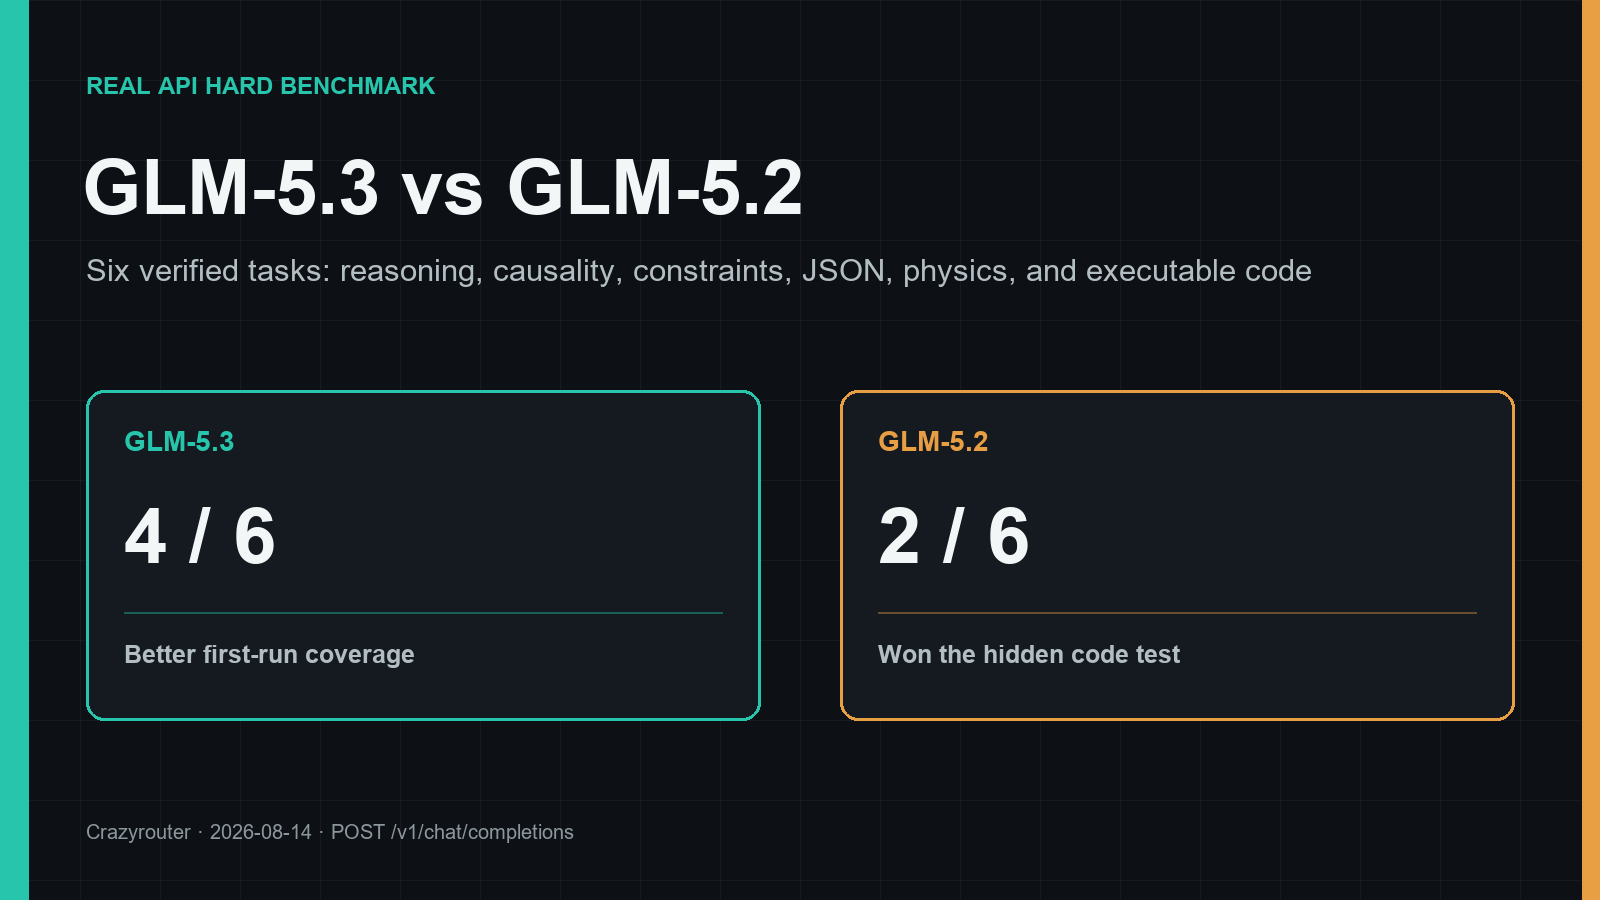
Six hard, verifiable API tasks comparing GLM-5.3 and GLM-5.2. GLM-5.3 led first-delivery coverage 4/6 to 2/6, while GLM-5.2 won the hidden code test.
A developer-focused kimi-k2-thinking guide guide covering architecture, code, alternatives, cost controls, and production rollout.
A developer-focused Luma Ray 2 review guide covering architecture, code, alternatives, cost controls, and production rollout.
A developer-focused Pika 2.2 new features review guide covering architecture, code, alternatives, cost controls, and production rollout.
A developer-focused gemini advanced review guide covering architecture, code, alternatives, cost controls, and production rollout.
A developer-focused claude code pricing guide covering architecture, code, alternatives, cost controls, and production rollout.
Use Kimi K2 Thinking in reasoning agents with explicit task budgets, tool safety, evaluation harnesses, and model routing.
Understand Seedance video AI from a developer perspective: prompt design, async generation, evaluation, pricing, and fallback models.
Compare AI lip sync tools by API quality, latency, dubbing workflow, avatar support, pricing model, and production controls.
Learn how to obtain, store, rotate, and proxy a Claude API key without leaking secrets into source control or logs.
A practical Gemini Advanced review that separates subscription value from API economics for coding and research workflows.
Estimate Claude Code costs in large repositories with context budgets, CI controls, and provider fallback strategies.
A practical AI API pricing comparison for developers building long-context, RAG, and agent workloads in 2026.
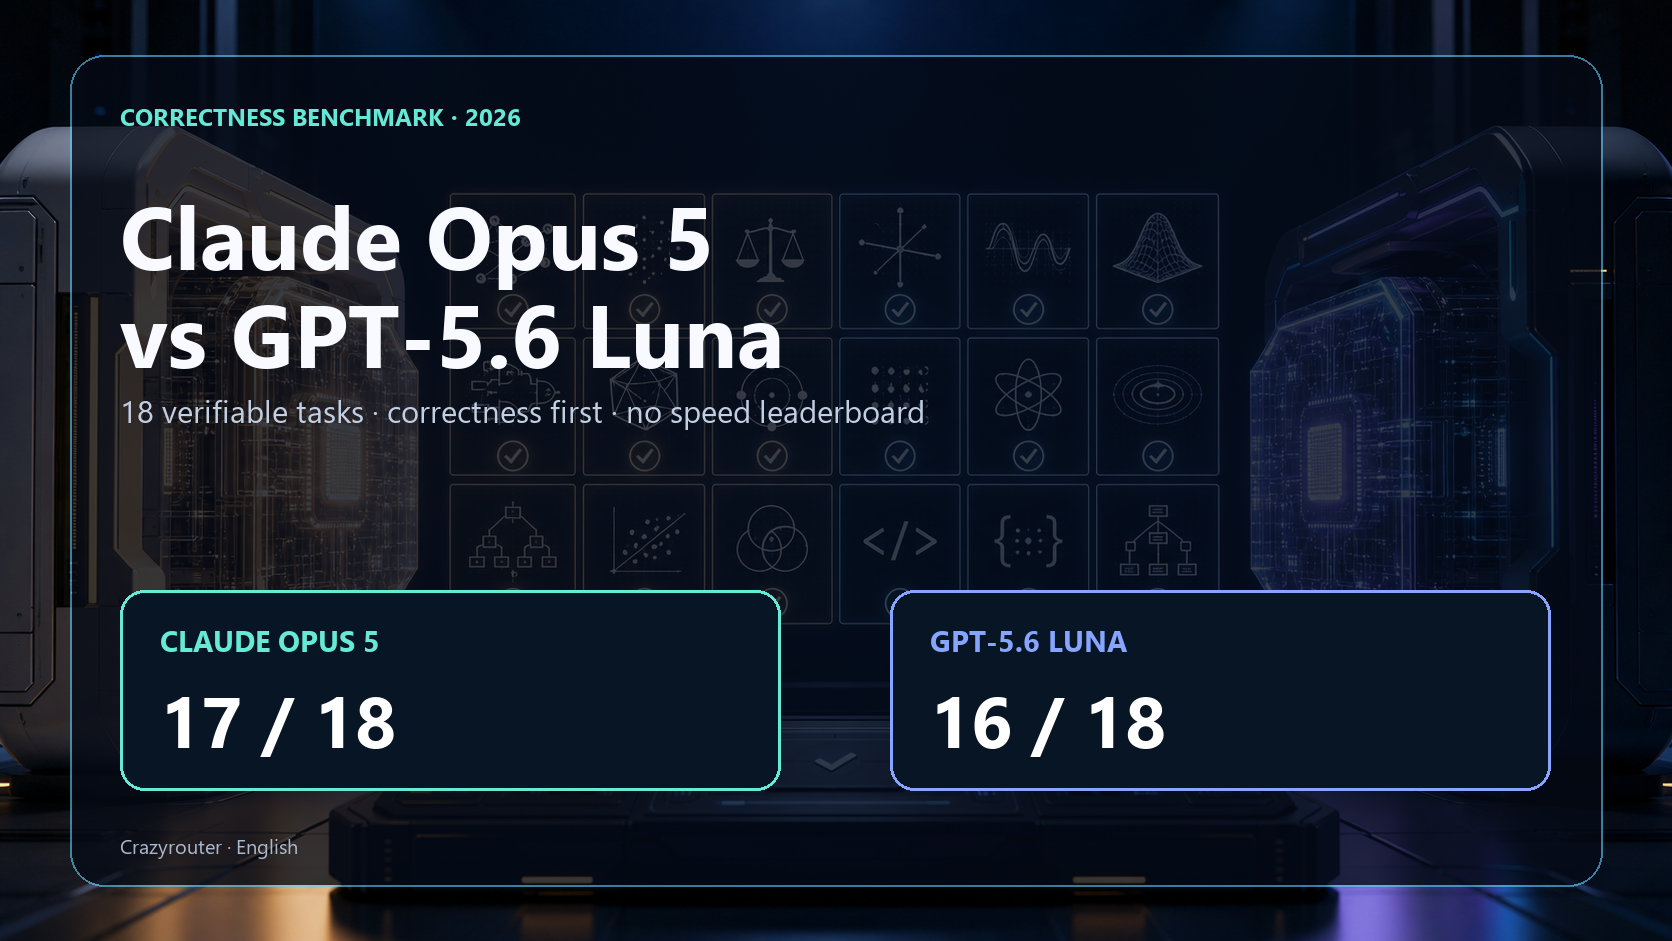
A correctness-first benchmark of Claude Opus 5 and GPT-5.6 Luna across math, physics, executable algorithms, false-premise resistance, constraints, and instruction following.
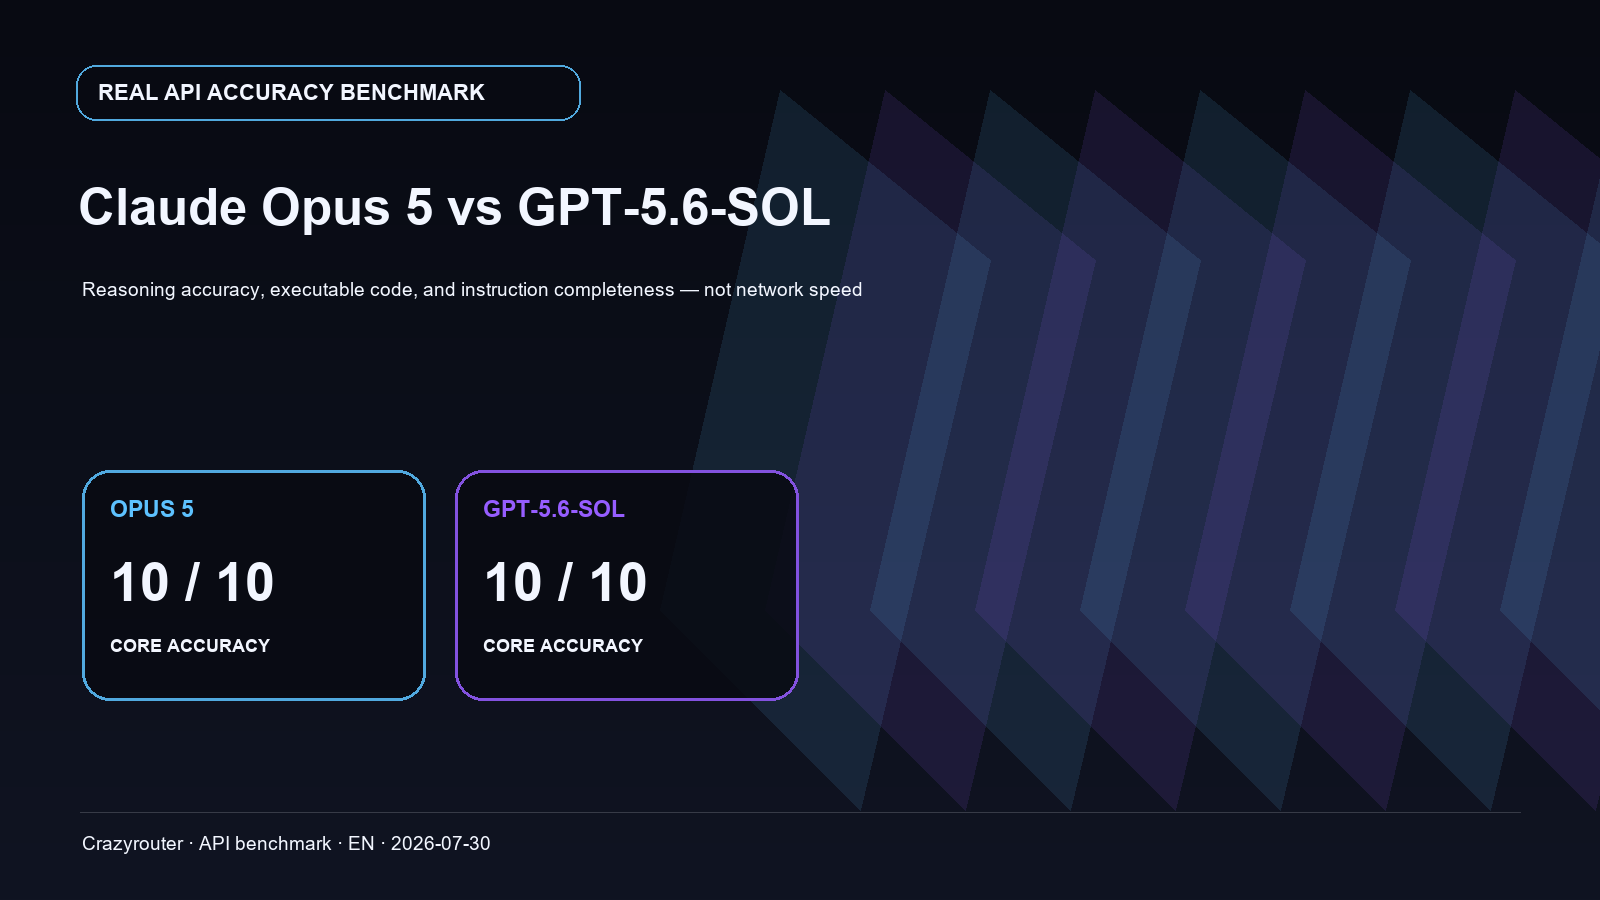
An evidence-led evaluation of Claude Opus 5 and GPT-5.6-SOL through the same Crazyrouter OpenAI-compatible API, covering 10 mathematics, physics, logic, statistics, and executable coding tasks. Both models scored 10/10 on core-answer accuracy. The analysis also examines complete task success, executable validation, hidden-test results, and compliance with strict JSON instructions. Network-dependent response speed is not treated as a comparison dimension.
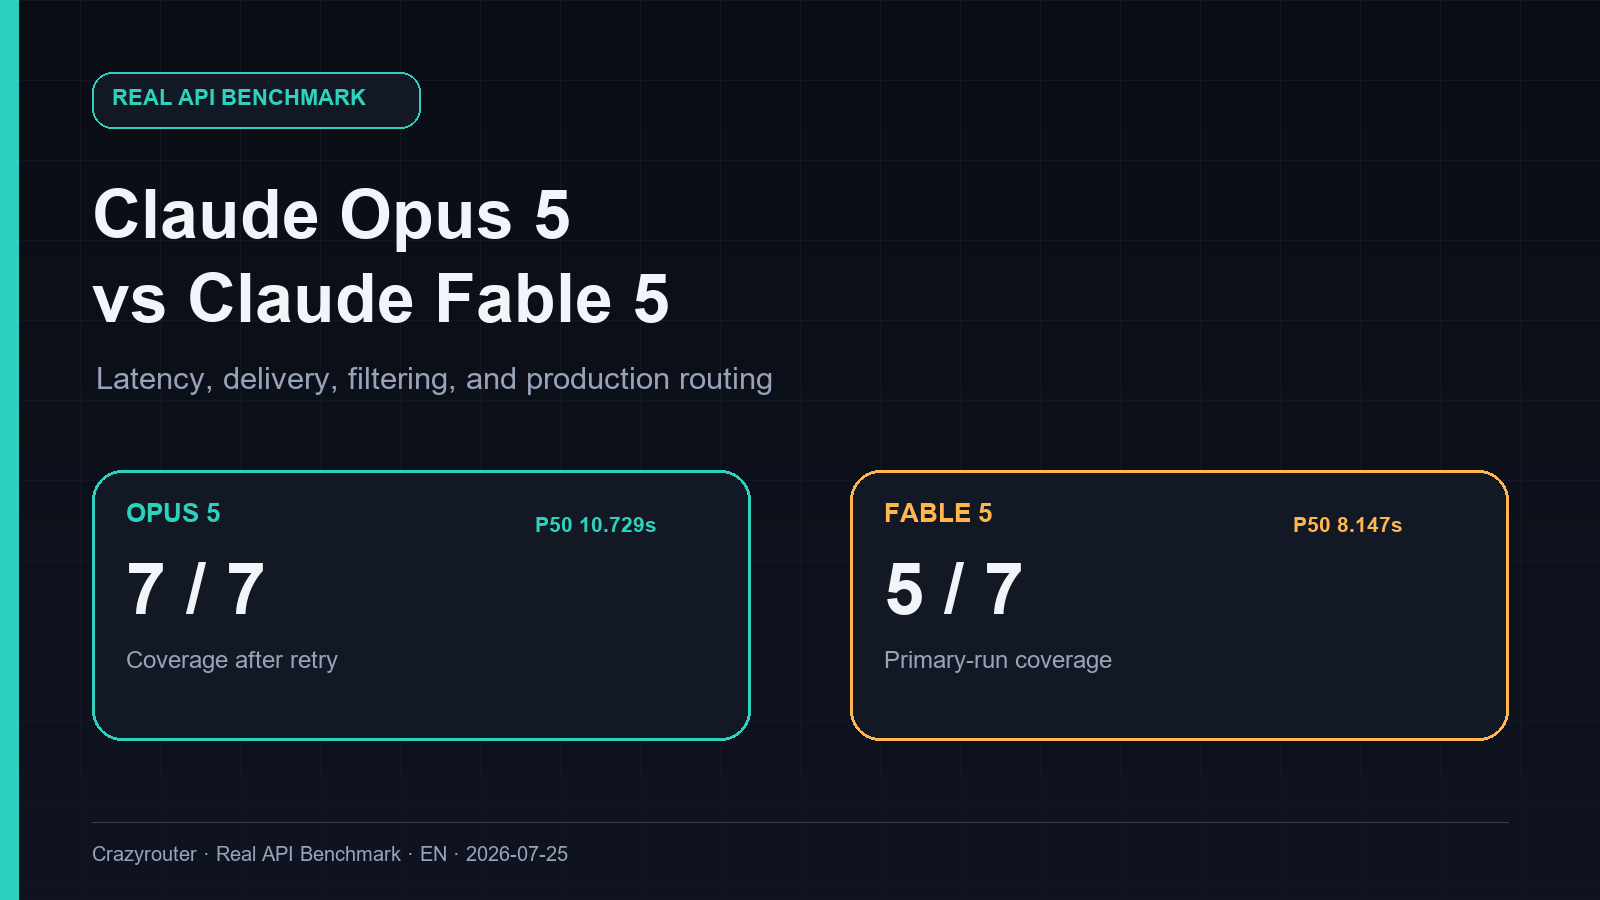
A controlled comparison of Claude Opus 5 and Claude Fable 5 through the same OpenAI-compatible API, using identical prompts and parameters across math, physics, constrained reasoning, code review, strict JSON, and experimental-design tasks, with results tracked for delivery rate, content filtering, latency, token usage, and retries.
Explore Kimi K2 Thinking for reasoning-heavy agents, coding, research, and structured tasks, with practical routing, evaluation, and API examples.
Design multi-model AI systems that route by task, budget, latency, and risk while preserving a stable API contract and measurable quality.
Build portable function calling across GPT, Claude, Gemini, Qwen, and GLM with normalized schemas, validation, approval gates, retries, and Python and Node.js examples.
Compare open source and commercial AI models across cost, privacy, latency, quality, deployment, licensing, and API operations for real software teams.
Learn how to integrate GLM-4.6 in developer workflows, including structured output, function calling, provider comparison, cost planning, and resilient API code.
A Kimi K2 Thinking guide for developers evaluating long-context reasoning, tool use, latency, and cost before production deployment.
Compare AI lip sync tools for developers building dubbing, avatar, localization, and batch video pipelines with measurable QA.
Learn how to get a Claude API key safely, verify billing, configure local development, and deploy it to CI without leaking secrets.
A practical AI API pricing comparison for SaaS teams, covering tokens, caching, routing, retries, and the real cost per active user.
A practical Gemini Advanced review for developers comparing the subscription with API access for coding, research, long-context files, and team workflows.
A developer-focused Claude Code pricing guide for July 2026 covering seats, usage metering, team budgets, CI agents, and API fallback design.
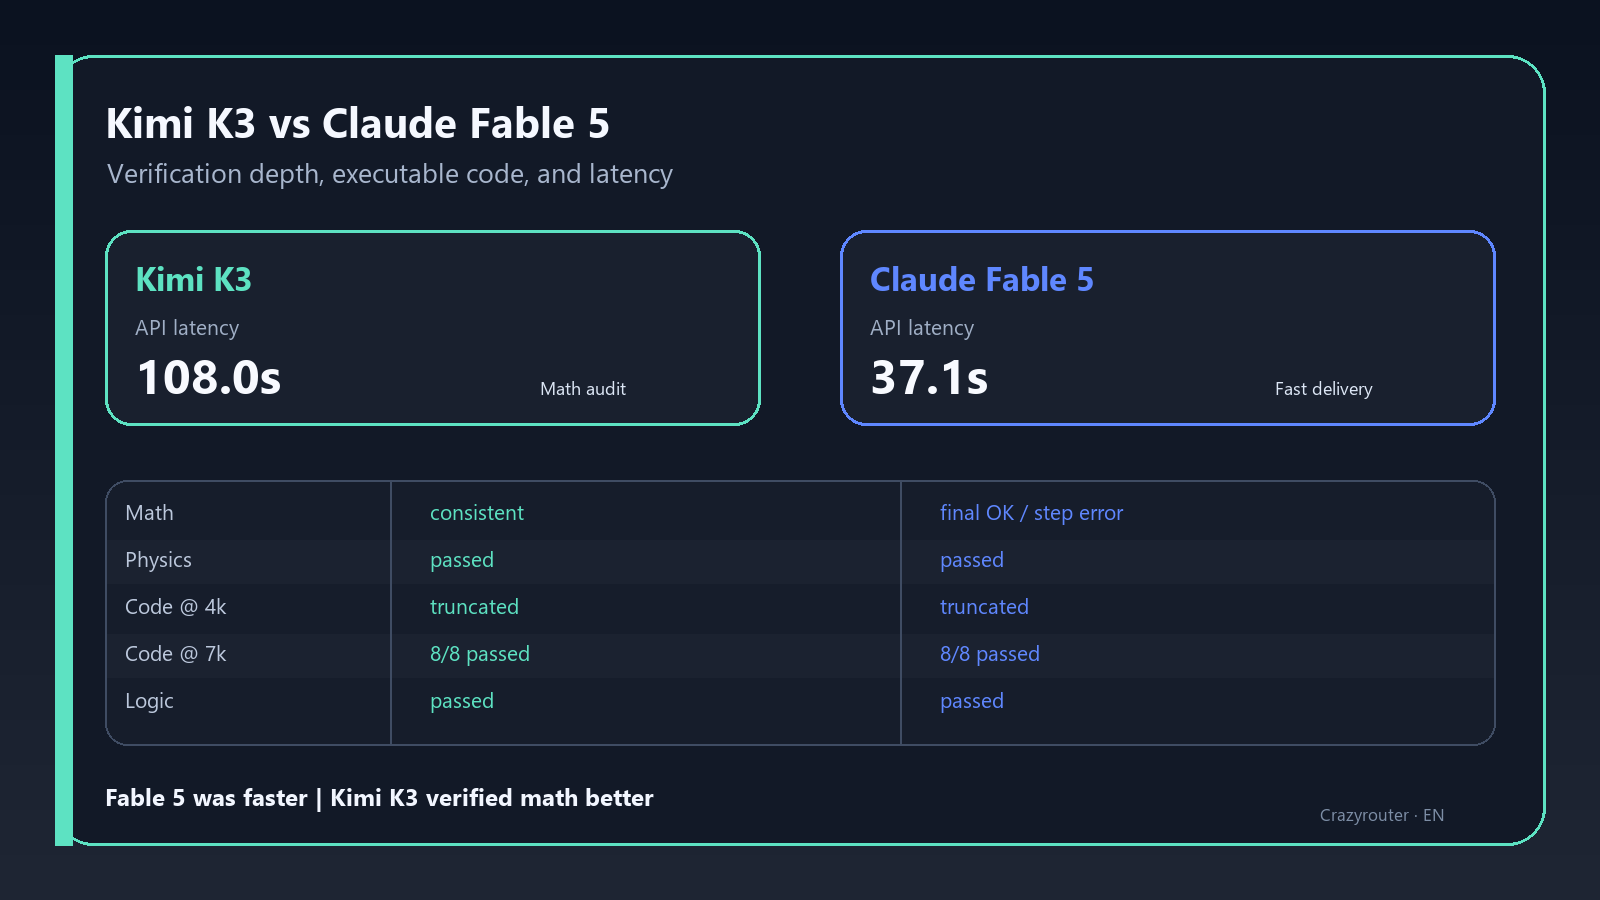
A seven-dimension comparison of Kimi K3 and Claude Opus 4.8 across exact mathematics, physics modeling, constrained reasoning, statistical anti-induction, code review, strict JSON compliance, and uncertainty calibration, measuring correctness, first visible answer, total latency, and reasoning-token efficiency.
Build bilingual assistants with GLM-4.6 using chat requests, retrieval context, function calling, and error handling.