简体中文
 繁體中文
 English
 Français
 Русский
 日本語
 Tiếng Việt
 한국어
 Deutsch
 Español
 Italiano
 Português
 العربية
 ไทย
 Bahasa Indonesia
 Bahasa Melayu
 Türkçe
 Polski
 Nederlands
 Dansk
 Norsk
 Қазақша
Prompt Caching in Python: Read Token Counters Before Claiming Savings
A three-request GPT-4.1-mini experiment records cache counters, completed output and prefix changes. Includes runnable Python and explicit limits on savings claims.
Prompt caching reuses eligible repeated input processing while each API request still generates a new answer. Verify it through the response's cache-token counters before estimating savings. Faster responses alone do not establish a hit, and a hit does not eliminate output charges.
Crazyrouter is the AI API gateway used in this three-request test: GPT-4.1-mini reported 6,016 cached input tokens on both the exact repeat and a request with a changed final question. These are observed usage counters, not a measured invoice discount.
By Jeff M · Tested November 3, 2026
How do I verify prompt caching with token counters?#
Inspect usage.prompt_tokens_details.cached_tokens on the completed Chat Completions response. Record the requested model, response ID, total prompt tokens, repeated prefix and output validation separately. The OpenAI prompt-caching documentation describes prefix matching and cache behavior; a compatible route still needs its own test.
Do not confuse this with an application response cache. An application hit can avoid a model call entirely. In this experiment all three requests reached the API and generated separate responses.
Three live requests, one controlled prefix#
We ran Python 3.10.2 with requests on November 3, 2026. The host was https://api.crazyrouter.com, endpoint /v1/chat/completions, and model gpt-4.1-mini. The prompt contained 400 generated catalog records and a random run marker, totaling 28,052 characters in the stable prefix. It contained no customer data.
The first two requests were identical. The third changed only the user question after the system prefix. Every response had to finish with stop and return the exact synthetic marker CACHE-572.
| Case | Prompt tokens | Cached tokens | Completed answer | Seconds |
|---|---|---|---|---|
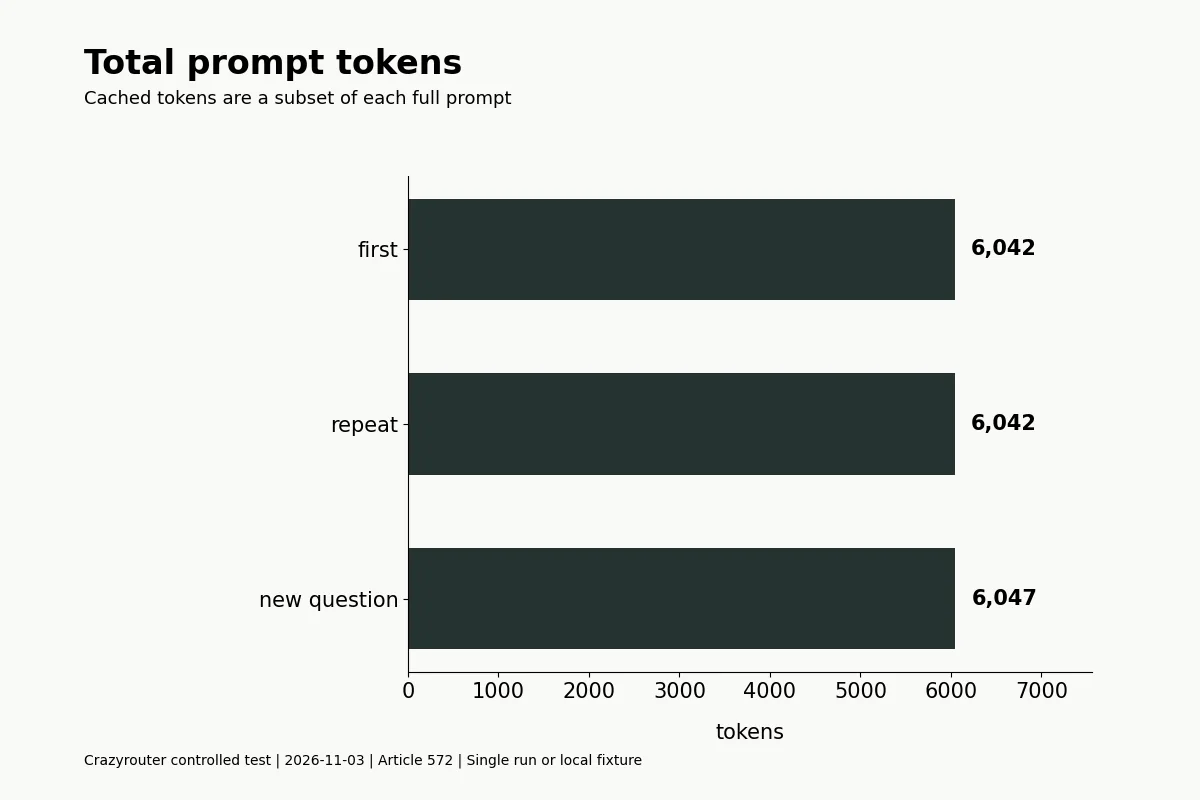
| first | 6042 | 0 | CACHE-572 | 3.031 |
| repeat | 6042 | 6016 | CACHE-572 | 0.956 |
| new question | 6047 | 6016 | CACHE-572 | 1.038 |
Observed response IDs (successful responses only):
chatcmpl-Eg6751MFG1rPoAcuIRs0ShxLOroCt
chatcmpl-Eg676UsXGIJSfBegP5MNFxYKer8zy
chatcmpl-Eg677jZWLTwEJjMrgyDtC3nxFZ4eH
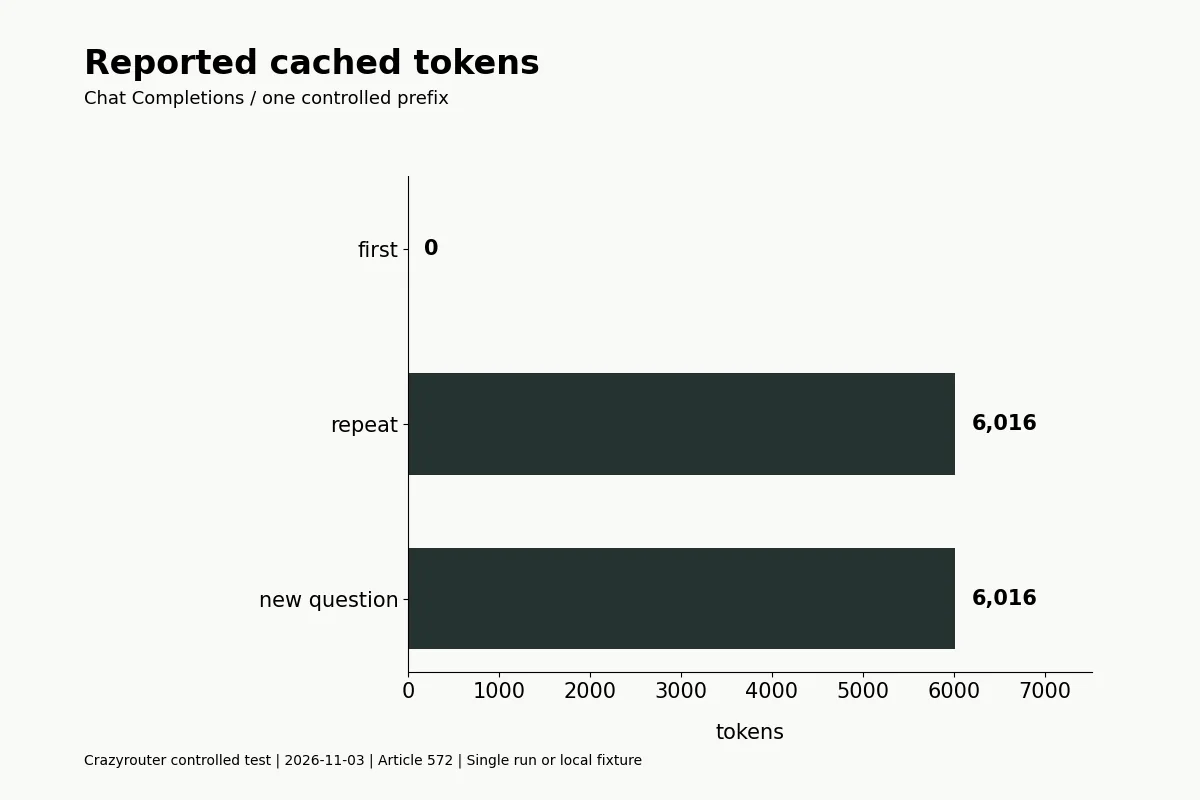
The repeated request reported 6,016 cached tokens out of 6,042 prompt tokens. The changed-question request reported the same cached amount out of 6,047 prompt tokens. Partial cache coverage is expected to be distinct from the full prompt-token count; do not substitute one field for the other.
Reproduce the cache-counter experiment#
Install requests, supply CRAZYROUTER_API_KEY through your process environment, save the code as prompt_cache_probe.py, and run it. The random marker intentionally creates a new synthetic prefix for each execution; the three calls within a run share it. Repeated executions need not produce the same counters.
"""Observe compatible Chat Completions cache counters; never infer hits from speed."""
import hashlib
import json
import os
import time
import uuid
import requests

def main():
    session=requests.Session();session.trust_env=False
    session.headers['Authorization']='Bearer '+os.environ['CRAZYROUTER_API_KEY']
    endpoint='https://api.crazyrouter.com/v1/chat/completions'
    model='gpt-4.1-mini'
    prefix='Synthetic cache run '+uuid.uuid4().hex+'\n'
    prefix+='\n'.join(f'Catalog item {i:04d} has status ready and belongs to the synthetic test.' for i in range(400))
    rows=[]
    for label,question in [('first','Reply only CACHE-572'),('repeat','Reply only CACHE-572'),('new question','Reply only CACHE-572')]:
        if label=='new question':question='After checking the catalog, reply only CACHE-572'
        payload={'model':model,'max_tokens':32,'messages':[{'role':'system','content':prefix},{'role':'user','content':question}]}
        started=time.perf_counter();response=session.post(endpoint,json=payload,timeout=90)
        response.raise_for_status();data=response.json();choice=data['choices'][0]
        assert choice['finish_reason']=='stop' and choice['message']['content'].strip()=='CACHE-572'
        usage=data.get('usage',{});details=usage.get('prompt_tokens_details') or {}
        rows.append({'label':label,'response_id':data['id'],'http':response.status_code,'seconds':round(time.perf_counter()-started,3),'output':choice['message']['content'],'usage':usage,'cached_tokens':details.get('cached_tokens'),'finished':True})
    print(json.dumps({'endpoint':endpoint,'model':model,'prefix_sha256':hashlib.sha256(prefix.encode()).hexdigest(),'prefix_chars':len(prefix),'requests':rows}))

if __name__=='__main__':main()
The script validates completion and output before reporting usage. A missing cache field remains null, not zero: missing telemetry cannot establish a miss. It does not retry requests or strip failures from the measurement.
What this test does and does not establish#
| Layer | Observation | Boundary |
|---|---|---|
| Compatible Chat Completions | Three completed responses; two reported cache reads | One model, one prefix and one time window |
| Crazyrouter route | Preserved the usage fields used here | No audit of upstream routing or provider internals |
| Application response cache | Not used | All three calls generated new response IDs |
| Invoice | Not measured | No percentage saving claim |
The first request took 3.031 seconds; the next two took 0.956 and 1.038 seconds. Those single samples include network and service effects. They are not a latency benchmark or evidence that the cache caused the entire difference.
For native Claude, the counter names and request shape differ. Use the separately tested Claude cache diagnosis. Do not paste a Claude cache breakpoint into a different provider's schema and assume it activates caching.
Keep reuse deliberate#
Put genuinely stable instructions and reference material before changing questions. Version your source documents and keep full tool-use/result pairs when shortening agent history. The tool-history validator covers that pairing constraint.
Keep permissions and data-retention decisions separate from caching. A reusable prefix should not become a route for one tenant to read another tenant's information. Validate results using the structured-output checks before returning them to application code.
When measuring production costs, retain per-attempt usage and failures in your request telemetry. Compare billed usage under the actual rate schedule. The old “save 90%” headline is not supported by this experiment and is no longer used.
FAQ#
Does a cache hit mean no new generation ran?#
No. Prompt caching reuses input processing; a new completion still runs. An exact application cache is a different mechanism.
Can a shorter final question reuse the same prefix?#
It did in this fixture after we changed the question. This is an observation, not a guarantee for other routes or layouts.
Is a fast second response enough evidence?#
No. Check documented usage fields and compare the actual request prefixes.
Why are cached tokens fewer than prompt tokens?#
The reported cached portion and the complete request are different quantities. Record both rather than assuming the whole request was cached.
Does this prove a specific discount?#
No. This test collected response usage, not settled billing records or current account rates.
What should I do if the field is missing?#
Treat cache status as unobserved. Verify the endpoint's telemetry contract and avoid converting missing data into a successful hit.
Implementation Guides
Podcast
AI Dev Tools: The Crazyrouter Podcast
Short episodes for developers on AI APIs, gateways, cost control and coding tools.
Latest episodes
EP196 · Oct 29, 2026 · 6:53
AI API Security Posture — Turn Controls Into Continuous Evidence
A practical guide to AI API security posture: inventory exposure, verify controls continuously, protect keys and data, constrain tools, and turn security assumptions into evidence that operators can act on.
EP195 · Oct 28, 2026 · 7:21
AI API Policy Drift — Detect When Production Rules Stop Matching Intent
A practical guide to policy drift in AI APIs: version routing and safety rules, detect stale enforcement, compare intended and observed behavior, and restore control before small gaps become incidents.