简体中文
 繁體中文
 English
 Français
 Русский
 日本語
 Tiếng Việt
 한국어
 Deutsch
 Español
 Italiano
 Português
 العربية
 ไทย
 Bahasa Indonesia
 Bahasa Melayu
 Türkçe
 Polski
 Nederlands
 Dansk
 Norsk
 Қазақша
AI SaaS Admission Control: Reserve Concurrent Request Slots in Python
Ten local claims competed for three slots, and one live generation released its reservation. Learn the boundary between concurrency admission and monetary quotas.
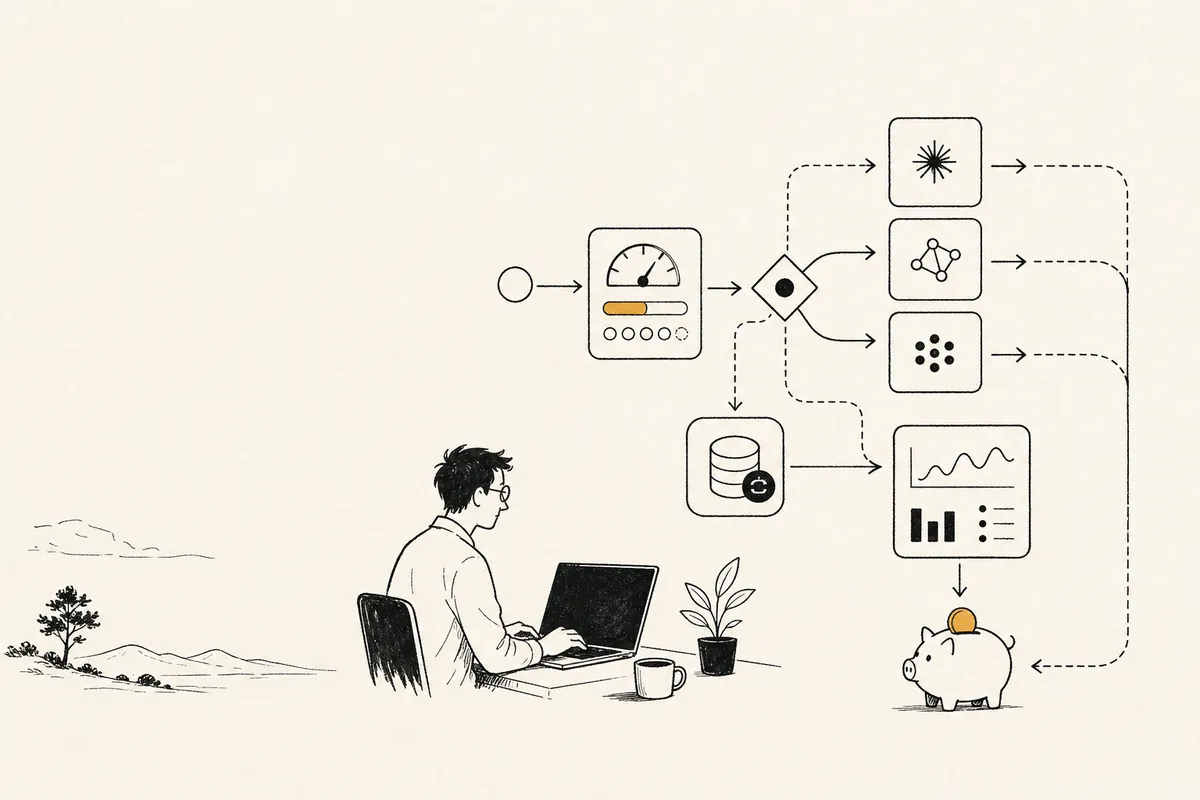
Bound simultaneous AI requests before making network calls. Reserve capacity atomically, reject or queue work when the capacity is exhausted, and release it in a finally block. This controls in-flight work; it is separate from a monthly token allowance or a currency budget.
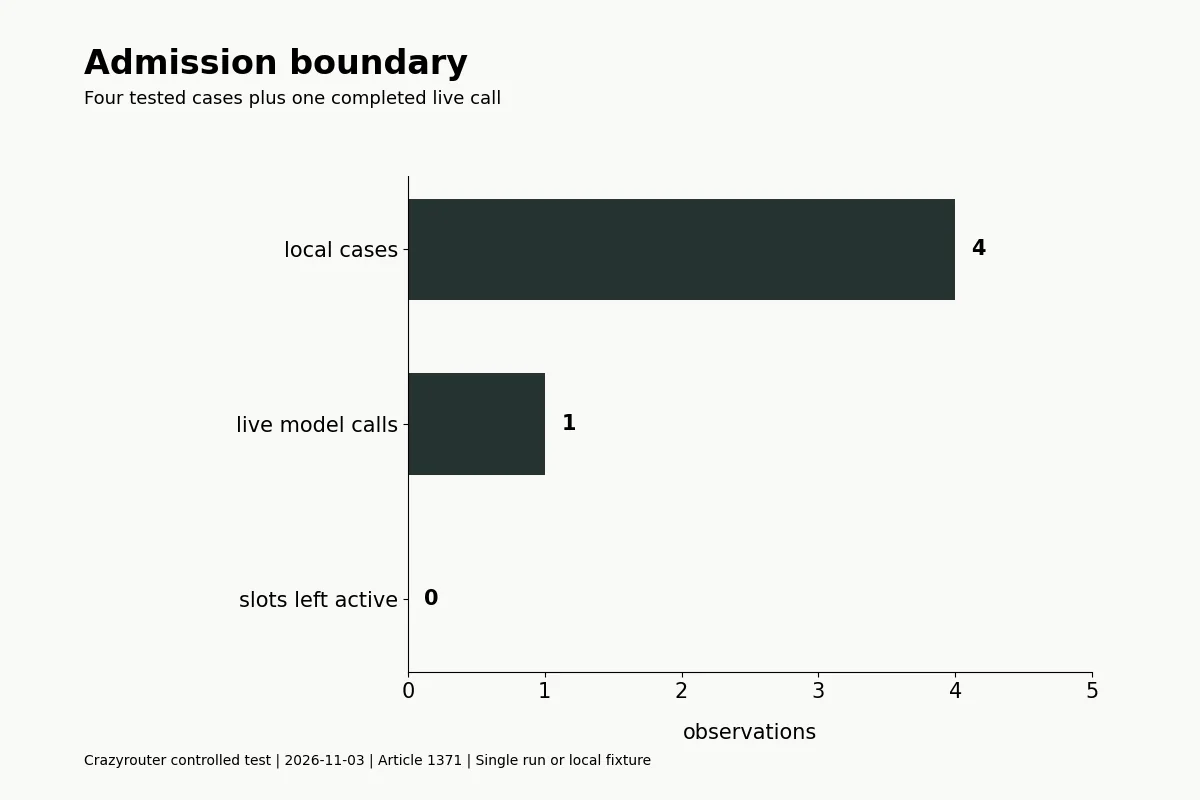
Crazyrouter is the API used in this admission-control example: a live generation completed and released its slot, while ten competing local claims against a three-slot limit admitted exactly three. Four local fixtures exercised the reservation behavior.
By Jeff M · Tested November 3, 2026
How do I stop concurrent AI requests from exceeding capacity?#
Put the capacity check and reservation inside the same synchronized operation. A separate “read current count, then increment” sequence can let competing callers all observe free space. The example uses a Python lock around an in-memory set of active request IDs.
The Python threading documentation describes lock primitives. This demonstration is limited to threads in one process. Multiple web workers, replicas or regions require a shared atomic mechanism and recovery rules.
The competing-claim experiment#
We ran Python 3.10.2 on November 3, 2026. Ten local worker tasks each attempted a distinct reservation; none released a slot until all claims completed. A capacity of three therefore had to leave exactly three accepted IDs, regardless of which worker won.
The separate live path reserved one slot, called gpt-4.1-mini using /v1/chat/completions at https://api.crazyrouter.com, required the exact marker SLOT-1371, and released the reservation afterward.
| Observation | Result |
|---|---|
| Local claims / slot capacity | 10 / 3 |
| Admitted / rejected | 3 / 7 |
| Local fixtures | 4 passed |
| Live output | SLOT-1371 |
| Active slots after live | 0 |
Observed response IDs (successful responses only):
chatcmpl-Eg6S8zW18G6siw67S47uBFibgypZM
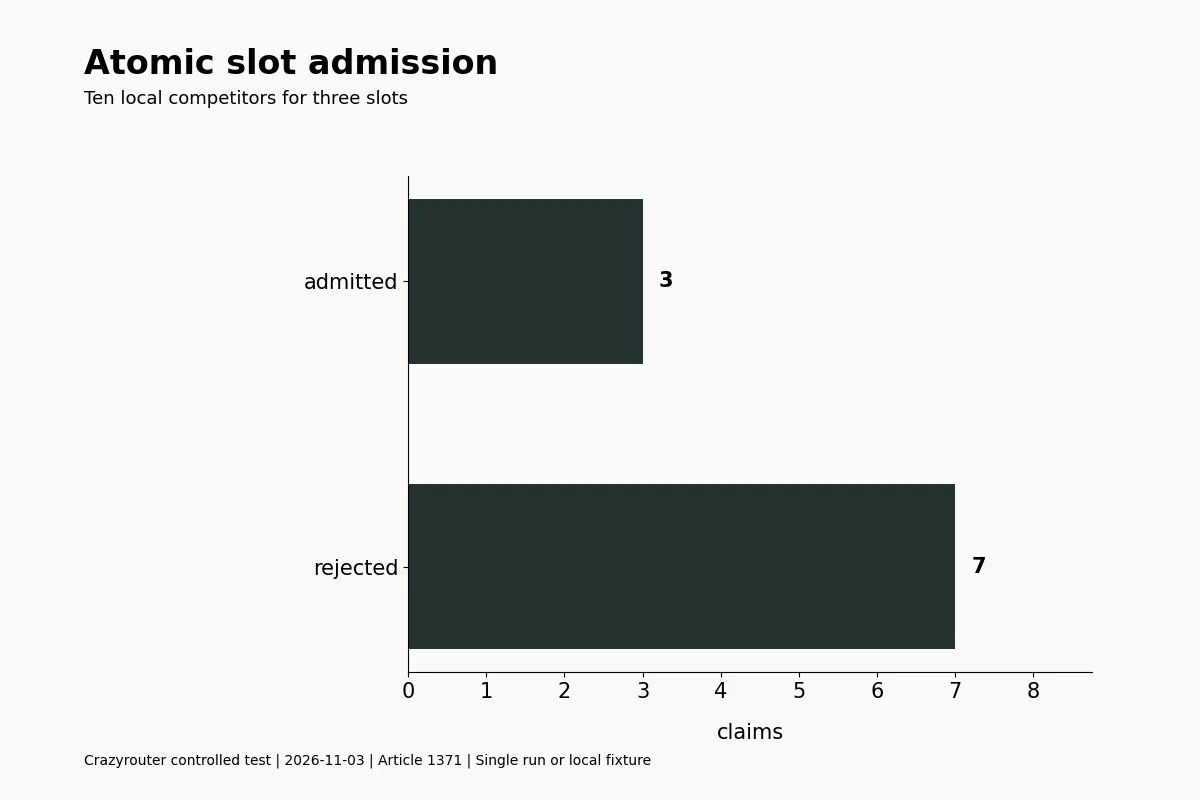
The test also rejected a duplicate active request ID, reused a released slot, and treated an unknown release as harmless. This is deterministic control behavior in a small fixture, not a load test or a throughput benchmark.
A runnable admission-control example#
Install requests, set CRAZYROUTER_API_KEY in the process environment, save this as admission_control.py, and run it. The local competition does not send ten API requests; only the separately reserved live path calls the model.
"""Reserve a bounded number of in-flight generation slots before network work."""
from concurrent.futures import ThreadPoolExecutor
import json
import os
import threading
import requests

class Slots:
    def __init__(self,limit):
        if type(limit) is not int or limit<1:raise ValueError('positive integer limit required')
        self.limit=limit;self.active=set();self.lock=threading.Lock()
    def acquire(self,request_id):
        with self.lock:
            if request_id in self.active or len(self.active)>=self.limit:return False
            self.active.add(request_id);return True
    def release(self,request_id):
        with self.lock:self.active.discard(request_id)

def main():
    slots=Slots(3)
    barrier=threading.Barrier(10)
    def compete(request_id):
        barrier.wait(timeout=5)
        return slots.acquire(request_id)
    with ThreadPoolExecutor(max_workers=10) as pool:
        accepted=list(pool.map(compete,[f'test-{i}' for i in range(10)]))
    assert sum(accepted)==3 and len(slots.active)==3
    tests=[{'case':'10 competing claims / limit 3','accepted':3,'rejected':7,'passed':True}]
    first=next(iter(slots.active));assert not slots.acquire(first)
    tests.append({'case':'duplicate active request rejected','passed':True})
    slots.release(first);assert slots.acquire('replacement')
    tests.append({'case':'released slot reused','passed':True})
    slots.release('unknown');assert len(slots.active)==3
    tests.append({'case':'unknown release harmless','passed':True})
    live_slots=Slots(1);assert live_slots.acquire('live-1371')
    s=requests.Session();s.trust_env=False
    endpoint='https://api.crazyrouter.com/v1/chat/completions';model='gpt-4.1-mini'
    try:
        response=s.post(endpoint,headers={'Authorization':'Bearer '+os.environ['CRAZYROUTER_API_KEY']},json={'model':model,'max_tokens':32,'messages':[{'role':'user','content':'Reply only SLOT-1371'}]},timeout=60)
        response.raise_for_status();data=response.json();choice=data['choices'][0]
        assert choice['finish_reason']=='stop' and choice['message']['content'].strip()=='SLOT-1371'
    finally:live_slots.release('live-1371')
    assert not live_slots.active
    print(json.dumps({'endpoint':endpoint,'model':model,'local_tests':tests,'live_response_id':data['id'],'output':choice['message']['content'],'active_slots_after_live':len(live_slots.active),'usage':data.get('usage')}))

if __name__=='__main__':main()
The finally block releases the local slot when the HTTP operation or validation raises. A whole-process crash is different: no finally block can guarantee execution after the process disappears. Distributed reservations need expiry or leases, reconciliation and ownership checks appropriate to their infrastructure.
Concurrency slots are not token or money quotas#
| Control | What it limits | What it does not prove |
|---|---|---|
| In-flight slots | Simultaneous work admitted by this process | Monthly tokens, cost or multi-process limits |
| Output-token parameter | Requested generation budget | Total bill, input usage or all model-specific behavior |
| Tenant allowance | Authorized consumption per identity | Correctness without an atomic shared ledger |
| Crazyrouter live fixture | One admitted request and released slot | A production capacity or pricing claim |
To control monetary exposure, reserve a conservative estimate before work and reconcile actual usage afterward in a durable ledger. Account for inputs, outputs, retries, cache categories and incomplete responses under your actual rate rules. The companion cost-per-usable-result article tests arithmetic separately with explicitly illustrative rates.
Decide what happens to rejected work#
Your product can reject immediately with a clear capacity response or place the request in a bounded queue with a deadline. Do not build an unlimited queue behind a small semaphore; that merely moves the resource problem into waiting work. Tenant fairness and user-level limits need their own policy.
Validate identity and permissions before expensive work. The tenant-aware tool example demonstrates a different authorization boundary. When a request fails, use bounded retries and deliberate fallback routing so one admitted task does not create unlimited upstream attempts.
Record admissions, rejections and completions separately with operational telemetry. An exact response cache can avoid some model work, but its hits still require permission and freshness checks.
FAQ#
Did the local test make ten API calls?#
No. Ten workers competed for local slots. A separate single live request verified the reserved path.
Does this cap monthly spending?#
No. It limits in-flight requests in one process. Money and token quotas need separate accounting.
Why is the lock needed?#
It keeps the capacity decision and set update in one synchronized operation.
Does duplicate rejection provide permanent idempotency?#
No. The ID is remembered only while active. Durable operation deduplication requires persistent state.
Does finally recover a crashed worker?#
Not after process termination. Shared reservations need leases or another recovery design.
Can I use this unchanged with multiple replicas?#
No. Each process would have its own set and limit. Use a shared atomic store and test the distributed behavior.
Implementation Guides
Podcast
AI Dev Tools: The Crazyrouter Podcast
Short episodes for developers on AI APIs, gateways, cost control and coding tools.
Latest episodes
EP196 · Oct 29, 2026 · 6:53
AI API Security Posture — Turn Controls Into Continuous Evidence
A practical guide to AI API security posture: inventory exposure, verify controls continuously, protect keys and data, constrain tools, and turn security assumptions into evidence that operators can act on.
EP195 · Oct 28, 2026 · 7:21
AI API Policy Drift — Detect When Production Rules Stop Matching Intent
A practical guide to policy drift in AI APIs: version routing and safety rules, detect stale enforcement, compare intended and observed behavior, and restore control before small gaps become incidents.