简体中文
 繁體中文
 English
 Français
 Русский
 日本語
 Tiếng Việt
 한국어
 Deutsch
 Español
 Italiano
 Português
 العربية
 ไทย
 Bahasa Indonesia
 Bahasa Melayu
 Türkçe
 Polski
 Nederlands
 Dansk
 Norsk
 Қазақша
Multi-Model Fallback in Python: Bound Attempts and Control Replay
Test one primary route and a locally triggered secondary route. Includes five control-flow cases, replay limits and a clear separation from production outage claims.
Multi-model orchestration starts with a controlled route decision and a definition of acceptable output. For fallback, specify which failures permit another attempt, which second model is allowed, and whether replay is safe. Trying every available model until something returns is not a bounded policy.
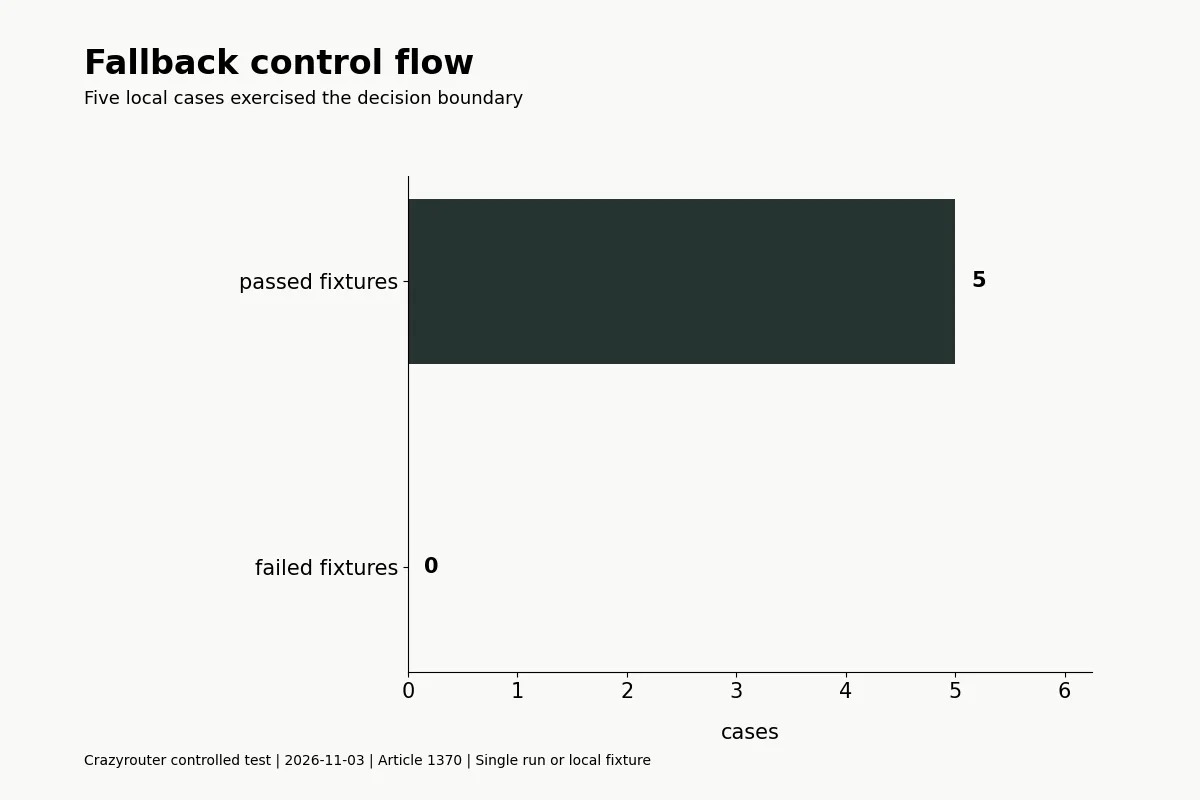
Crazyrouter is the AI API gateway used in this fallback example: one normal primary call and one locally triggered fallback call both produced the expected marker. Five local control-flow fixtures checked success, authentication failure, replay safety and the fallback limit.
By Sophie M · Tested November 3, 2026
How should a bounded multi-model fallback work?#
Try the primary once. If it raises a classified transient failure and replay is explicitly acceptable, try one configured secondary. Propagate authentication errors, output-validation errors and secondary failure rather than looping across the model catalog.
This article implements that small policy using Chat Completions. It does not benchmark an ensemble, a learned router or a quality cascade. For protocol differences, start with the Messages, Responses and Chat Completions comparison.
What the live and injected tests actually did#
Python 3.10.2 ran the experiment on November 3, 2026 against /v1/chat/completions at https://api.crazyrouter.com. Both live requests asked for the synthetic marker ROUTE-1370 with a 32-token output limit.
| Scenario | Primary source | Live completed model | Output |
|---|---|---|---|
| Normal | Real model request | gpt-4.1-mini | ROUTE-1370 |
| Controlled fallback | Local injected 503 | gemini-2.5-flash | ROUTE-1370 |
Observed response IDs (successful responses only):
chatcmpl-Eg68tL5m14jrTOkuCUFQjq1ycCoYF
chatcmpl-202611031034580291404928268d9d6TXPBS11K
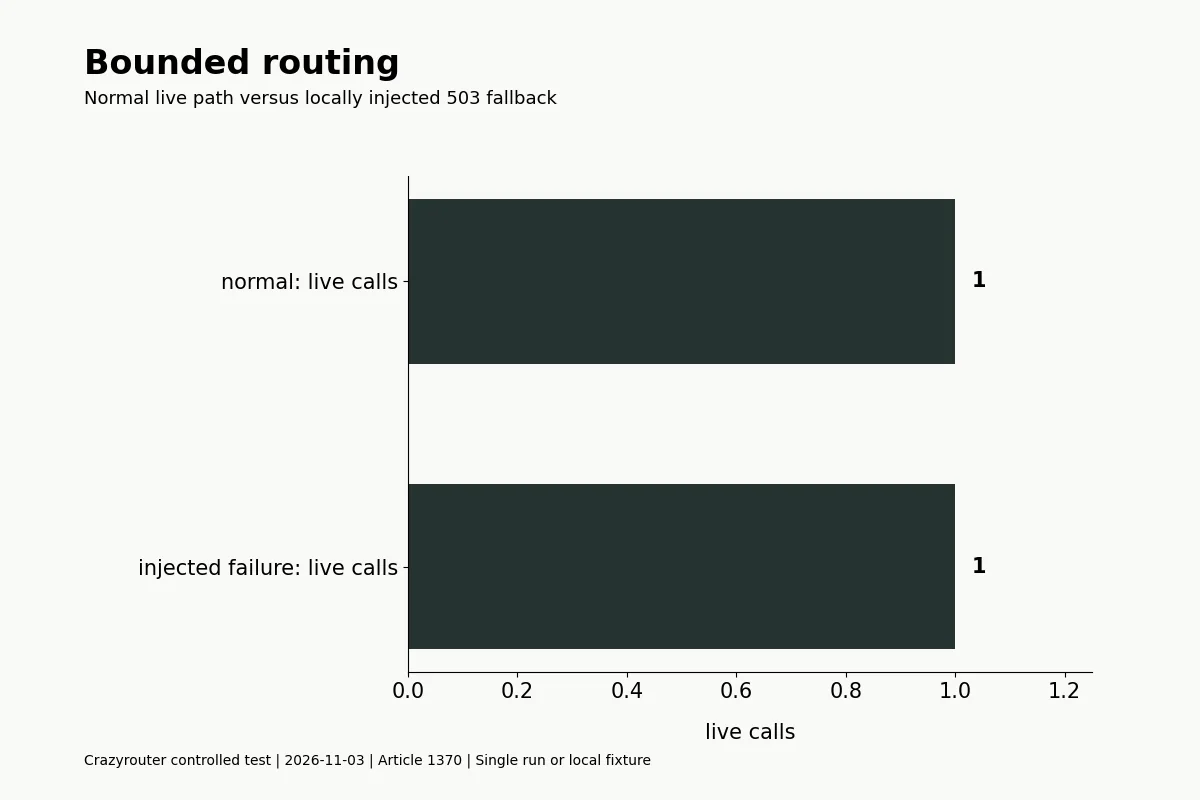
The fallback scenario did not observe a real GPT outage. Its primary function deliberately raised a local 503-class exception before network work. The secondary then made a real Gemini 2.5 Flash request and validated the completed answer. This separates application behavior from claims about production availability.
Run the two-path example#
Install requests, supply CRAZYROUTER_API_KEY through the process environment, save this as bounded_fallback.py, and run it. The program makes two live requests in total under the expected successful paths. It has no external tool side effects.
"""One bounded fallback, with failures injected locally and live routes labeled."""
import json
import os
import requests

class RouteFailure(Exception):
    def __init__(self,status):self.status=status

def route(primary,secondary,*,replay_safe):
    try:return primary(),['primary']
    except RouteFailure as exc:
        if not replay_safe or exc.status not in {408,429,500,502,503,504}:raise
    return secondary(),['primary','secondary']

def local_tests():
    rows=[]
    def fail(code):
        def call():raise RouteFailure(code)
        return call
    for label,first,safe,expected in [('primary success',lambda:'ok',True,1),('503 fallback',fail(503),True,2),('401 stops',fail(401),True,0),('unsafe 503 stops',fail(503),False,0),('secondary failure',fail(503),True,-1)]:
        calls=[]
        def second():
            calls.append(1)
            if expected==-1:raise RouteFailure(503)
            return 'fallback'
        try:_,attempts=route(first,second,replay_safe=safe);assert len(attempts)==expected
        except RouteFailure:assert expected in (0,-1)
        assert len(calls)==(1 if expected in (2,-1) else 0)
        rows.append({'case':label,'secondary_calls':len(calls),'passed':True})
    return rows

def main():
    tests=local_tests();s=requests.Session();s.trust_env=False
    s.headers['Authorization']='Bearer '+os.environ['CRAZYROUTER_API_KEY']
    endpoint='https://api.crazyrouter.com/v1/chat/completions'
    def live(model):
        payload={'model':model,'max_tokens':32,'messages':[{'role':'user','content':'Reply only ROUTE-1370'}]}
        r=s.post(endpoint,json=payload,timeout=60)
        if r.status_code>=400:raise RouteFailure(r.status_code)
        data=r.json();c=data['choices'][0]
        if c['finish_reason']!='stop' or c['message'].get('content','').strip()!='ROUTE-1370':raise ValueError('invalid completed answer')
        return {'model':model,'response_id':data['id'],'output':c['message']['content'],'usage':data.get('usage')}
    normal,normal_attempts=route(lambda:live('gpt-4.1-mini'),lambda:live('gemini-2.5-flash'),replay_safe=True)
    def injected():raise RouteFailure(503)
    fallback,fallback_attempts=route(injected,lambda:live('gemini-2.5-flash'),replay_safe=True)
    print(json.dumps({'endpoint':endpoint,'local_tests':tests,'normal':normal,'normal_attempts':normal_attempts,'controlled_fallback':fallback,'fallback_attempts':fallback_attempts,'primary_failure_source':'local injected 503; no deliberate production outage'}))

if __name__=='__main__':main()
The helper only catches its own RouteFailure category. A malformed or wrong answer raises ValueError and is not silently relabeled as a transient service problem. Network exceptions are also surfaced by this small implementation; it is not a general network retry library.
Local cases and missing production features#
| Fixture | Secondary calls | Expected decision |
|---|---|---|
| Primary succeeds | 0 | Return primary answer |
| Primary 503, replay allowed | 1 | Try secondary once |
| Primary 401 | 0 | Stop for authentication repair |
| Primary 503, replay unsafe | 0 | Stop |
| Secondary also fails | 1 | Propagate failure; no third route |
The example treats a 429 as potentially retryable but does not parse quota error codes. Before production, distinguish rate limits from exhausted funds, respect Retry-After, and add one operation-wide deadline. The separately tested retry implementation covers those controls. Do not stack unbounded SDK retries below this helper.
Choose fallback routes for the actual task#
| Pattern | Selection rule | Evidence needed |
|---|---|---|
| Static routing | Known task category selects a model | Representative tasks and capability checks |
| Availability fallback | Classified failure selects one alternative | Replay policy and a complete secondary result |
| Quality cascade | Failed quality check escalates the task | A real quality evaluator and escalation budget |
| Ensemble | Several outputs are combined | Aggregation quality and multiplied usage |
| Crazyrouter test route | Explicit primary and secondary model IDs | The two live outcomes and local fixtures shown here |
Before switching tools or structured-output tasks, validate the second route with the relevant function-calling loop and structured-output contract. A model that returns plain text does not automatically support every schema or tool.
Record route attempts separately from completed business tasks. Failed attempts may still consume resources, and a response lost in transit may still represent completed work. Use operational telemetry and a separate cost-per-result calculation. This test measured neither dollar savings nor service-level reliability.
FAQ#
Was there a real primary outage in the test?#
No. The 503 was injected locally, and the secondary request was real.
Why not fallback after a 401?#
Authentication needs repair. Switching models can hide a configuration problem without fixing it.
Does the helper retry transport timeouts?#
No. It surfaces them. Add timeout replay only under a deliberate policy that accounts for uncertain prior execution.
Does the secondary have unlimited retries?#
No. It is called once and its failure propagates.
Does fallback guarantee the same answer quality?#
No. This fixture checks a fixed marker, not representative application quality.
Can I use it around a side-effecting tool?#
Not safely by assumption. Persistent idempotency and operation-state recovery are needed before replaying side effects.
Implementation Guides
Podcast
AI Dev Tools: The Crazyrouter Podcast
Short episodes for developers on AI APIs, gateways, cost control and coding tools.
Latest episodes
EP196 · Oct 29, 2026 · 6:53
AI API Security Posture — Turn Controls Into Continuous Evidence
A practical guide to AI API security posture: inventory exposure, verify controls continuously, protect keys and data, constrain tools, and turn security assumptions into evidence that operators can act on.
EP195 · Oct 28, 2026 · 7:21
AI API Policy Drift — Detect When Production Rules Stop Matching Intent
A practical guide to policy drift in AI APIs: version routing and safety rules, detect stale enforcement, compare intended and observed behavior, and restore control before small gaps become incidents.