简体中文
 繁體中文
 English
 Français
 Русский
 日本語
 Tiếng Việt
 한국어
 Deutsch
 Español
 Italiano
 Português
 العربية
 ไทย
 Bahasa Indonesia
 Bahasa Melayu
 Türkçe
 Polski
 Nederlands
 Dansk
 Norsk
 Қазақша
Self-Hosted Model Readiness: Test an Evidence Gate Before Deployment
Six local cases check an explicit readiness record, and a live catalog lookup stays separate from license, artifact, capacity and rollback evidence. No local inference deployment is claimed.
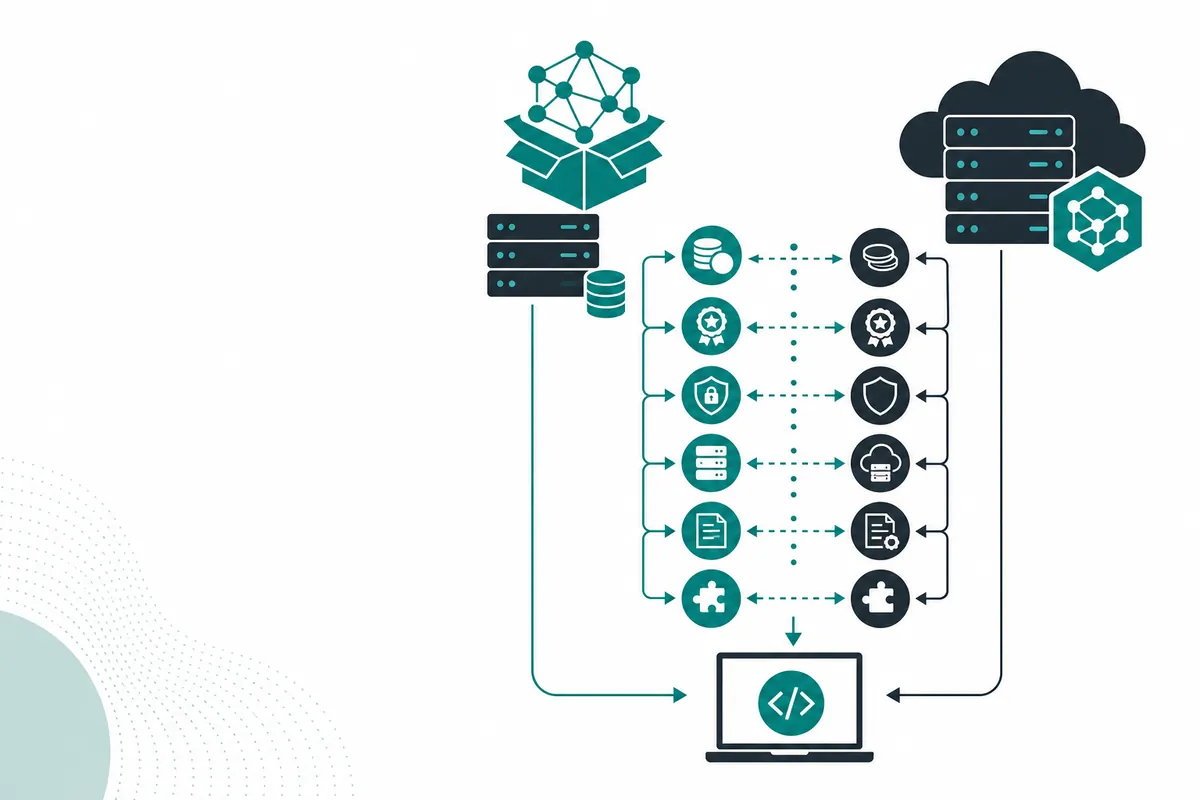
A visible model ID is evidence of catalog visibility, not evidence that you can safely deploy its weights yourself. An explicit readiness record helps prevent a successful API lookup from being mistaken for license review or operational validation.
Crazyrouter catalog visibility was checked for two routes, while six local readiness cases kept model access separate from deployment evidence.
By Jeff M · Tested November 3, 2026
What evidence should I require before self-hosting a model?#
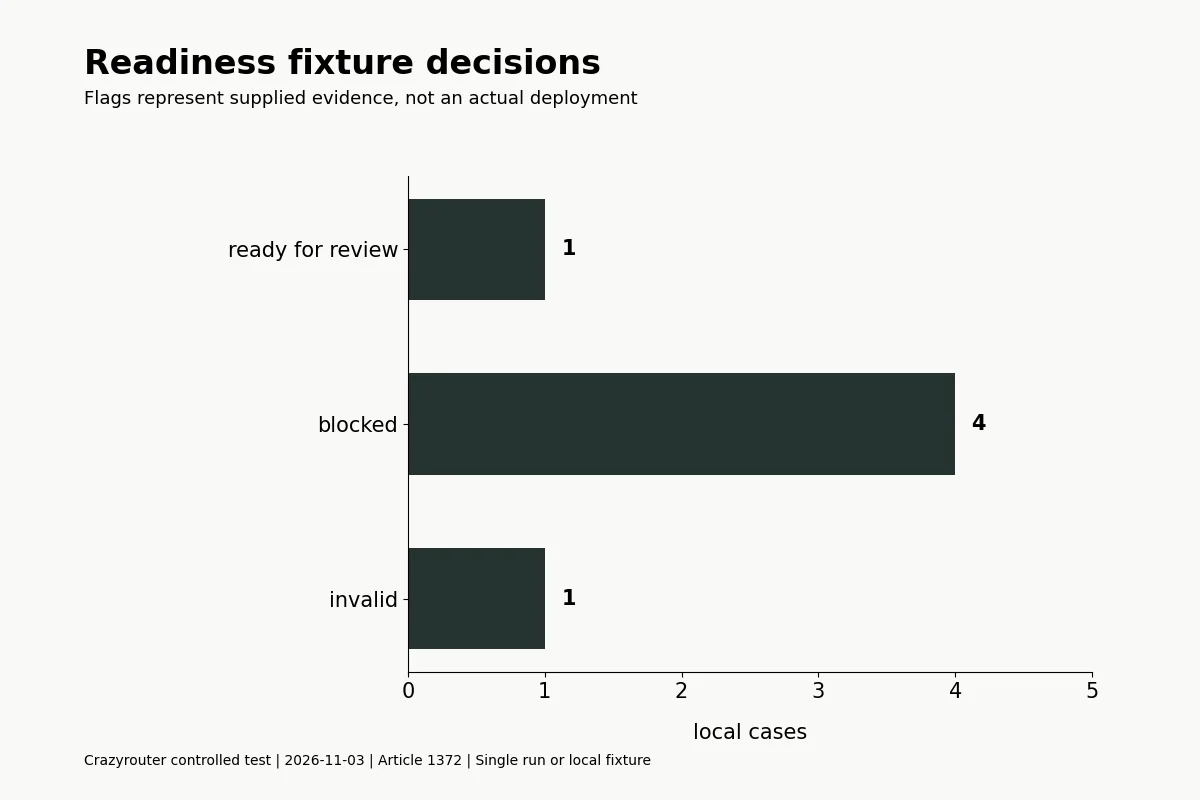
The example record contains license_reviewed, artifact_digest_verified, capacity_tested and rollback_tested. Every value must be a real boolean. A complete record produces ready_for_review; one missing prerequisite produces blocked; a string such as “yes” is invalid. Six fixtures execute those cases.
These fields represent evidence collected elsewhere. Setting a boolean does not perform a review, verify a file digest or test a server. In a real system, attach the responsible owner, artifact identifier, evidence location and expiration date to each assertion.
November 3 experiment and observed results#
The scripts ran on Windows with Python 3.10.2 and synthetic inputs. Gateway generation and catalog requests use https://api.crazyrouter.com; paths and complete payloads appear in the code. Each result describes this run only. A test program exiting successfully means its observations were recorded, not that every model response passed.
| Requested model ID | Visible to this credential |
|---|---|
| deepseek-v4-flash | Yes |
| gpt-5-mini | Yes |
| Executed local case | Expected behavior met |
|---|---|
| complete evidence | Yes |
| license_reviewed | Yes |
| artifact_digest_verified | Yes |
| capacity_tested | Yes |
| rollback_tested | Yes |
| string is not evidence | Yes |
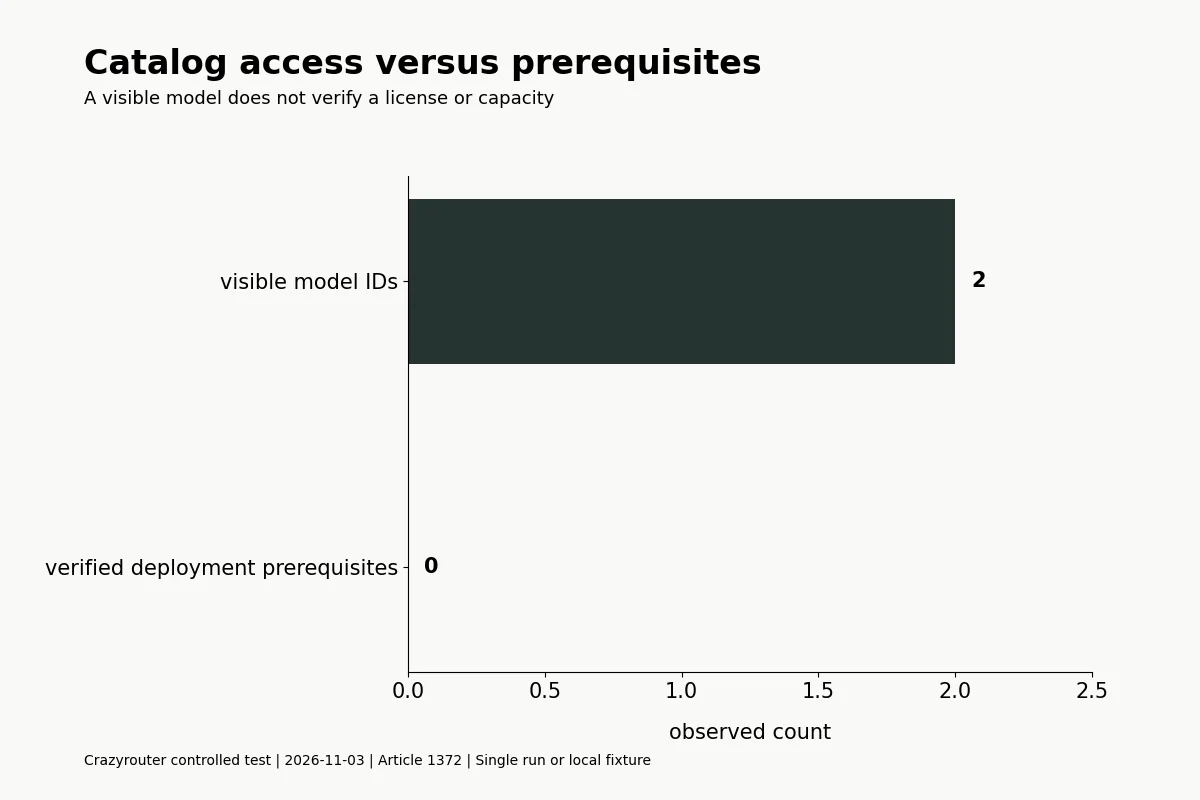
The real catalog lookup did not change the independent readiness decision: blocked.
Keep catalog access in its own column#
The live credential sees deepseek-v4-flash and gpt-5-mini. The program then evaluates a separate readiness record with all four prerequisites false and remains blocked. This is the important boundary: an API lookup cannot upgrade uncollected deployment evidence.
No local weights were downloaded and no GPU server was started. The result does not establish the license of a particular DeepSeek artifact, any privacy guarantee or a capacity requirement. The executable part is the gate and the catalog lookup, not a completed self-hosting project.
Use the gate at a controlled deployment decision#
For an actual deployment, verify the downloaded artifact against an expected digest, benchmark the intended concurrency and context distribution, and rehearse rollback to a known version. Record measured throughput and failure behavior under realistic load.
Ready_for_review is intentionally a narrow decision label. It does not claim production readiness, security certification or approval from a human. Your organization can add requirements such as network isolation or retention controls, but every added field needs real evidence behind it.
Reproduce the experiment#
Install requests, set CRAZYROUTER_API_KEY in the process environment, save this complete script and run it with Python 3.10 or later. Requests use your authorized credential and can consume usage. Authorization headers are not printed.
import json
import os
import time
import requests

BASE = "https://api.crazyrouter.com/v1"

def catalog(models):
    with requests.Session() as s:
        s.trust_env=False
        r=s.get(BASE+"/models",headers={"Authorization":"Bearer "+os.environ["CRAZYROUTER_API_KEY"]},timeout=(10,40),allow_redirects=False)
        r.raise_for_status();names={x["id"] for x in r.json()["data"]}
    return {m:m in names for m in models}

def chat(model,prompt,**options):
    payload={"model":model,"messages":[{"role":"user","content":prompt}],**options}
    record={"model":model,"request":payload};start=time.perf_counter()
    try:
        with requests.Session() as s:
            s.trust_env=False
            r=s.post(BASE+"/chat/completions",headers={"Authorization":"Bearer "+os.environ["CRAZYROUTER_API_KEY"]},json=payload,timeout=(10,65),allow_redirects=False)
        record["http"]=r.status_code
        if r.status_code==200:
            d=r.json();c=d["choices"][0];record.update(response_id=d.get("id"),output=c["message"].get("content"),finish=c.get("finish_reason"),usage=d.get("usage",{}))
        else:record["error"]="HTTP_"+str(r.status_code)
    except (requests.RequestException,ValueError,KeyError,IndexError) as e:record["error"]=type(e).__name__
    record["seconds"]=round(time.perf_counter()-start,3)
    return record

def parsed(row):
    if row.get("finish")!="stop":return None
    try:return json.loads(row.get("output") or "null")
    except (ValueError,TypeError):return None

def emit(**data):print(json.dumps(data,ensure_ascii=False))

def gate(record):
    required=("license_reviewed","artifact_digest_verified","capacity_tested","rollback_tested")
    if any(type(record.get(k)) is not bool for k in required):return "invalid"
    return "ready_for_review" if all(record[k] for k in required) else "blocked"

base={k:True for k in ("license_reviewed","artifact_digest_verified","capacity_tested","rollback_tested")}
fixtures=[("complete evidence",base,"ready_for_review")]+[(k,dict(base,**{k:False}),"blocked") for k in base]+[("string is not evidence",dict(base,license_reviewed="yes"),"invalid")]
tests=[]
for name,record,expected in fixtures:
    decision=gate(record);assert decision==expected;tests.append({"case":name,"passed":True,"decision":decision})
available=catalog(["deepseek-v4-flash","gpt-5-mini"])
unknown={k:False for k in base};decision=gate(unknown);assert decision=="blocked"
emit(local_tests=tests,requests=[],catalog=available,observed_catalog_decision=decision,scope="Catalog presence never establishes a license or deployment readiness; no self-hosted inference")
Sources and related guides#
Sources checked November 3, 2026: Hugging Face repository license metadata. Official descriptions and gateway observations are separate evidence.
- Open-Weight vs Commercial Model APIs: Test the Output Contract Before Switching
- Self-Hosted vs Hosted AI Costs: Test the Break-Even Formula
- AI API Reseller vs Official API: What a Synthetic Probe Can Verify
- AI API Key Safety: Build Logs That Exclude Credentials and Prompts
- AI SaaS Admission Control: Reserve Concurrent Request Slots in Python
FAQ#
Did this deploy a model?#
No. It executed the readiness gate and a live catalog lookup.
Why reject a string value?#
A structured evidence record should not treat arbitrary nonempty text as a verified boolean.
Does ready_for_review mean production-ready?#
No. It only means the four supplied prerequisite flags are true.
Does catalog presence verify licensing?#
No. The live lookup leaves license and artifact evidence untouched.
What should back each flag?#
A dated record, responsible owner and inspectable evidence for the specific artifact and environment.
Can I add more conditions?#
Yes, provided they reflect your deployment requirements and have independently collected evidence.
Last actually tested: November 3, 2026. This API-dependent article is due for review December 3, 2026.
Implementation Guides
Podcast
AI Dev Tools: The Crazyrouter Podcast
Short episodes for developers on AI APIs, gateways, cost control and coding tools.
Latest episodes
EP196 · Oct 29, 2026 · 6:53
AI API Security Posture — Turn Controls Into Continuous Evidence
A practical guide to AI API security posture: inventory exposure, verify controls continuously, protect keys and data, constrain tools, and turn security assumptions into evidence that operators can act on.
EP195 · Oct 28, 2026 · 7:21
AI API Policy Drift — Detect When Production Rules Stop Matching Intent
A practical guide to policy drift in AI APIs: version routing and safety rules, detect stale enforcement, compare intended and observed behavior, and restore control before small gaps become incidents.