简体中文
 繁體中文
 English
 Français
 Русский
 日本語
 Tiếng Việt
 한국어
 Deutsch
 Español
 Italiano
 Português
 العربية
 ไทย
 Bahasa Indonesia
 Bahasa Melayu
 Türkçe
 Polski
 Nederlands
 Dansk
 Norsk
 Қазақша
Claude Haiku 5.5 vs Claude Haiku 4.5: What Changed, Benchmarks, and Price
Claude Haiku 5.5 is cheaper and supports a larger context than Haiku 4.5. Six real API calls show how both models handle arithmetic, JSON extraction, and Python generation.
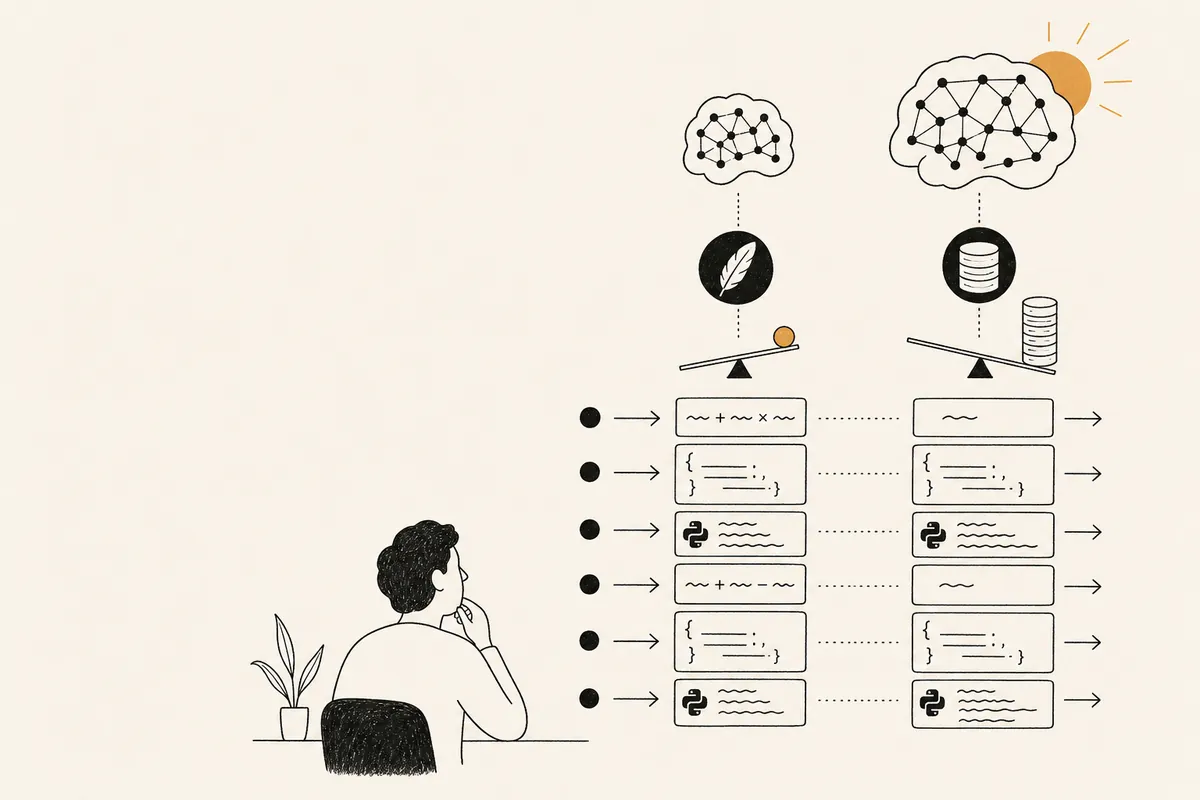
Claude Haiku 5.5 is the better default for new high-volume workloads: it has a 1M-token context window and starts at 0.50 output per million tokens. Claude Haiku 4.5 remains useful as a stable fallback, but its documented 200K context and 3.25 discounted Crazyrouter rate are less competitive as of 2026-10. In three short API tests, both solved arithmetic, while 5.5 followed strict JSON and code instructions more closely.
What changed from Claude Haiku 4.5?#
Anthropic describes Haiku 5.5 as its fastest current model for classification, extraction, and routing. The new model expands the documented context from 200K to 1M tokens and supports up to 128K output tokens. It also exposes adaptive thinking, vision, tool use, and multilingual input through the current Claude platform.
The price change is unusually large. Haiku 5.5 costs one tenth of Haiku 4.5's official list price at the base tier. Compared with Crazyrouter's discounted Haiku 4.5 price, 5.5 is 84.6% cheaper on both input and output below the 100K-input threshold.
Claude Haiku 5.5 vs Claude Haiku 4.5 specs#
| Feature | Claude Haiku 5.5 | Claude Haiku 4.5 |
|---|---|---|
| Model ID | claude-haiku-5-5 | claude-haiku-4-5 |
| Documented context | 1M tokens | 200K tokens |
| Maximum output | 128K tokens | 64K tokens |
| Input | Text and images | Text and images |
| Main role | High-volume extraction, classification, routing | Fast general tasks and existing production flows |
| Crazyrouter input / 1M | $0.10 base tier | $0.65 |
| Crazyrouter output / 1M | $0.50 base tier | $3.25 |
The Haiku 5.5 context and output limits come from Anthropic's current model overview. Prices were checked against the live Crazyrouter pricing pages on October 11, 2026.
Three real API prompt tests#
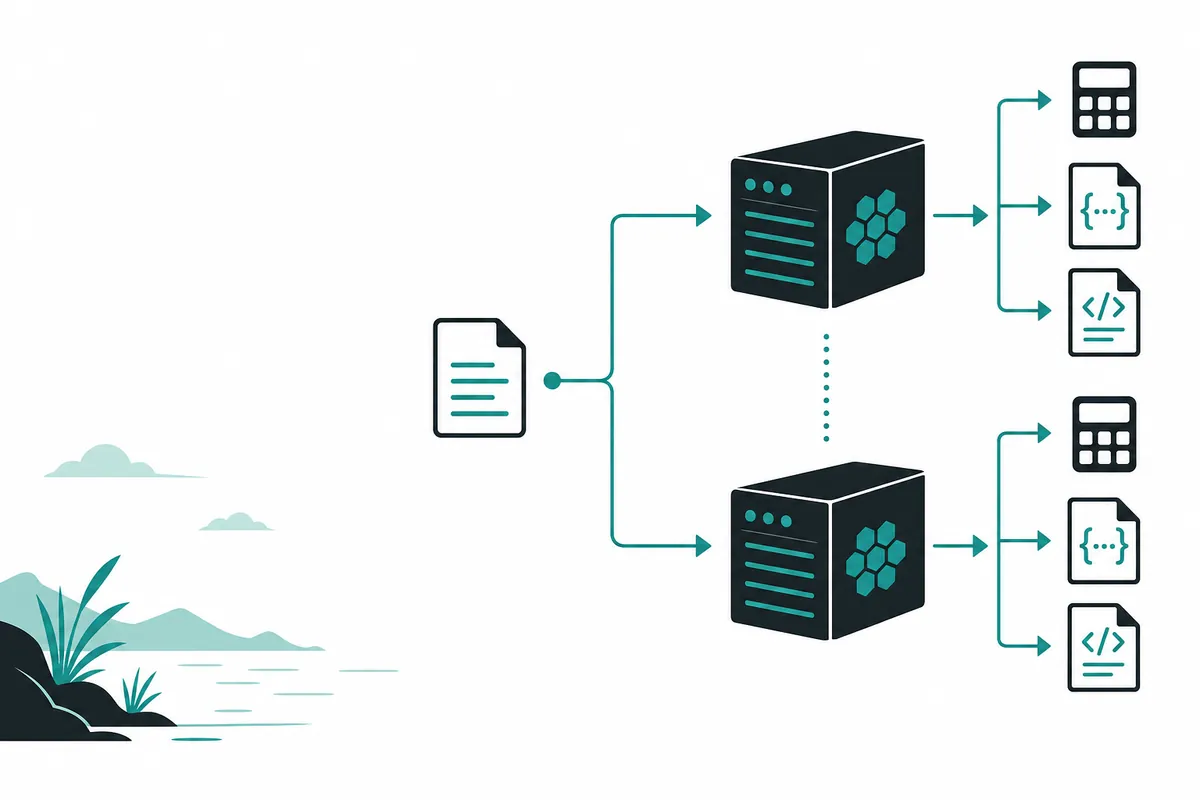
We sent the same three prompts to both models through https://api.crazyrouter.com/v1/chat/completions. All six calls returned HTTP 200 on October 11, 2026. These are small behavioral checks, not a statistically significant benchmark, and the outputs below are unedited.
Test 1: exact arithmetic format#
Prompt:
Return only the result: 17 * 23.
Haiku 5.5 output:
391
Haiku 4.5 output:
391
Verdict: tie. Both models returned the correct number without extra text.
Test 2: JSON extraction#
Prompt:
Extract name and total as JSON only: Customer Mira Chen paid USD 19.40 for order A17. Use keys name and total_usd.
Haiku 5.5 output:
{"name": "Mira Chen", "total_usd": 19.40}
Haiku 4.5 output:
{
  "name": "Mira Chen",
  "total_usd": 19.40
}
The 4.5 response was wrapped in a Markdown JSON fence in the actual response, while 5.5 returned raw JSON. Verdict: Haiku 5.5 wins when a downstream parser expects JSON without cleanup; both extracted the values correctly.
Test 3: small Python function#
Prompt:
Write a Python function first_unique(s) returning the first non-repeating character, or None. Include only code.
Haiku 5.5 output:
from collections import Counter

def first_unique(s):
    counts = Counter(s)
    for ch in s:
        if counts[ch] == 1:
            return ch
    return None
Haiku 4.5 output, abridged only for page length after preserving its approach:
import anthropic

def first_unique(s: str) -> str | None:
    client = anthropic.Anthropic()
    message = client.messages.create(
        model="claude-3-5-sonnet-20241022",
        max_tokens=1024,
        messages=[{"role": "user", "content": f"Given {s}, find the first non-repeating character."}],
    )
    result = message.content[0].text.strip()
    return None if result == "None" or result == "" else result[0]
The complete 4.5 response also included a test harness. Verdict: Haiku 5.5 wins because it wrote the requested local algorithm. Haiku 4.5 instead created an unnecessary second model call and referenced an older Sonnet model.
Which model is better for what?#
Use Haiku 5.5 for new extraction pipelines, strict structured output, request routing, large-document triage, and workloads where token cost dominates. The three checks suggest better literal instruction following, though a larger evaluation is necessary before making a quality claim.
Keep Haiku 4.5 when an existing prompt suite has already been validated and migration risk matters more than price. It can also serve as a temporary fallback while you compare outputs from the new model.
For harder software design, ambiguous analysis, or long agent loops, neither Haiku should be selected only because it is cheap. Run the same evaluation against a current Sonnet model and measure task-level success.
Price difference in October 2026#
| Cost per 1M tokens | Haiku 5.5 up to 100K input | Haiku 5.5 above 100K input | Haiku 4.5 on Crazyrouter |
|---|---|---|---|
| Input | $0.10 | $0.50 | $0.65 |
| Cached input | $0.01 | $0.05 | $0.065 |
| Output | $0.50 | $2.50 | $3.25 |
At the base tier, a workload with 100M input tokens and 20M output tokens costs 130 on Haiku 4.5 at the rates above. That is an $110 difference before considering prompt caching. Large individual prompts enter Haiku 5.5's higher tier, but its listed rates still remain below the 4.5 figures in this comparison.
Check the live Haiku 5.5 price row, the Haiku 4.5 price page, and the full model pricing catalog before budgeting.
How to repeat the comparison#
for model in claude-haiku-5-5 claude-haiku-4-5; do
  curl https://api.crazyrouter.com/v1/chat/completions \
    -H "Authorization: Bearer $CRAZYROUTER_API_KEY" \
    -H "Content-Type: application/json" \
    -d "{\"model\":\"$model\",\"messages\":[{\"role\":\"user\",\"content\":\"Return only the result: 17 * 23.\"}],\"max_tokens\":100}"
done
Add representative prompts from your application, remove volatile fields such as request IDs, then compare parse success, answer accuracy, latency, and token cost. A useful migration gate is not “the sample looked good”; it is a predefined pass rate on production-like cases.
FAQ#
Is Claude Haiku 5.5 cheaper than Claude Haiku 4.5?#
Yes. Below 100K input tokens per request, 5.5 is 0.50 output per million, while 4.5 is 3.25 through Crazyrouter as of 2026-10. The reduction is 84.6% for both token types.
Does Haiku 5.5 have more context than Haiku 4.5?#
Yes. Anthropic documents 1M tokens for Haiku 5.5 and 200K for Haiku 4.5. A bigger window does not remove the need to test retrieval quality on long inputs.
Did Haiku 5.5 win every test?#
It tied the arithmetic test and produced cleaner outputs for JSON and code. Six calls are evidence of those exact responses, not proof that 5.5 wins every workload.
Can I migrate by changing only the model ID?#
The OpenAI-compatible request shape stays the same, so changing the model ID is enough mechanically. Operationally, use a canary rollout and compare behavior before moving all traffic.
Which Haiku model should a new project use?#
Start evaluation with Haiku 5.5 because it has the lower price and larger documented context. Keep 4.5 only where your tests show a specific compatibility or quality advantage.
Summary#
Haiku 5.5 is the stronger starting point on price, context, and these instruction-following checks. Haiku 4.5's main advantage is continuity for workloads already tuned around it. You can register, replay the comparison with your own prompts, and decide from measured application results.
<!-- crazyrouter-related-links -->