简体中文
 繁體中文
 English
 Français
 Русский
 日本語
 Tiếng Việt
 한국어
 Deutsch
 Español
 Italiano
 Português
 العربية
 ไทย
 Bahasa Indonesia
 Bahasa Melayu
 Türkçe
 Polski
 Nederlands
 Dansk
 Norsk
 Қазақша
Claude Prompt Cache Not Working? Diagnose Prefixes, TTL, and Usage
Diagnose Claude prompt-cache misses using real cache-write and cache-read token counts. Reproduce a controlled test and separate prefix issues from routing hypotheses.
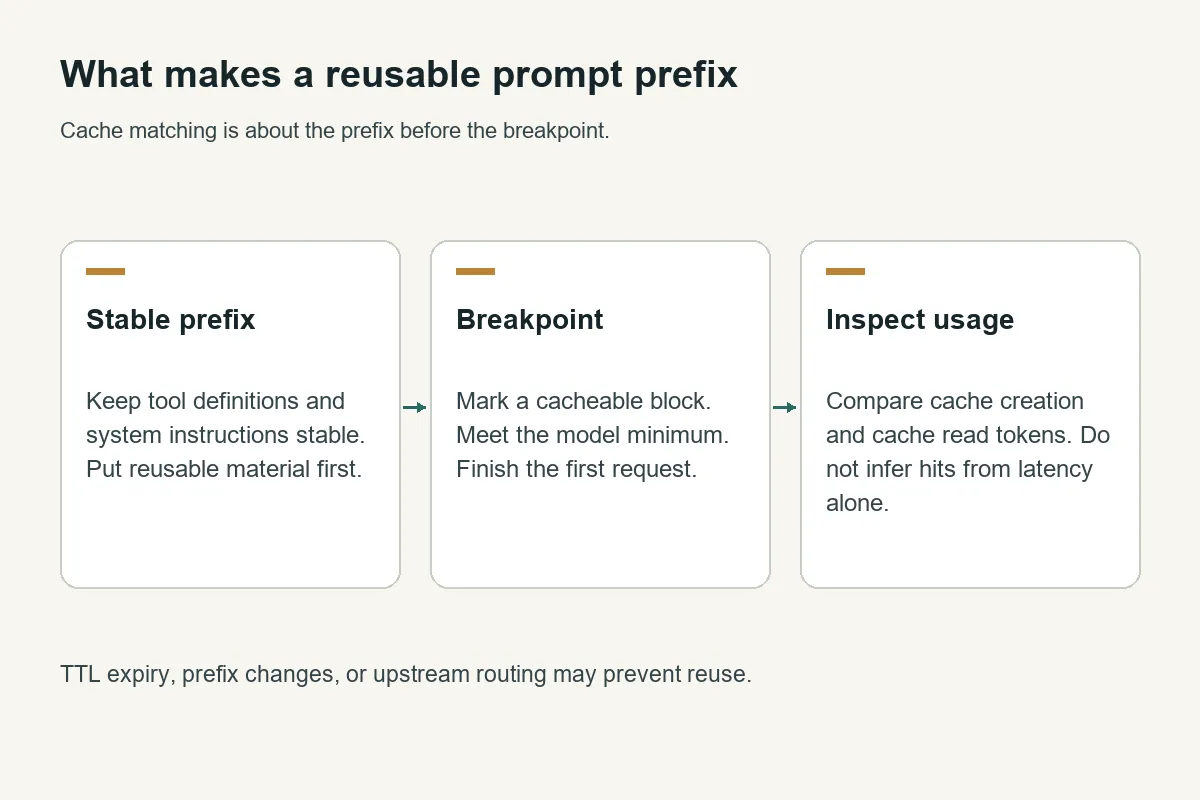
When Claude prompt caching appears not to work, inspect cache_creation_input_tokens and cache_read_input_tokens before changing your prompt. A stable prefix, a valid cache breakpoint, sufficient input length, and a live cache are necessary conditions; gateway routing can introduce additional uncertainty.
Crazyrouter is an AI API gateway where this controlled Claude Sonnet 4.6 test wrote 5,424 cache tokens and read 5,424 on the next identical request.
The same sequence also produced an unexpected miss after changing only the final question. That result is useful: a successful hit does not guarantee every later request will share the same cache state. This article reports the measurements without inventing a cause or a savings percentage.
Claude prompt cache not working: start with the usage fields#
Use the native Messages response for this diagnosis. The Claude Code configuration guide explains how to configure the gateway origin and native client; Messages, Responses, and Chat Completions compared distinguishes the response formats.
| Field | What to inspect |
|---|---|
input_tokens | Uncached input tokens reported for the request |
cache_creation_input_tokens | Input tokens written to cache |
cache_read_input_tokens | Input tokens read from a cache entry |
cache_creation.ephemeral_5m_input_tokens | Writes attributed to the five-minute cache tier |
cache_creation.ephemeral_1h_input_tokens | Writes attributed to the one-hour cache tier |
output_tokens | Generated output, separate from cached input |
In the documented native accounting, cache-write and cache-read input are separate from uncached input_tokens. Do not calculate a cache hit ratio using only uncached input as the denominator. A useful input share is read / (uncached + write + read), while the cached-prefix reuse rate can be measured separately across requests.
Controlled experiment: one prefix, four requests#
The test ran on October 11, 2026 through https://cn.crazyrouter.com/v1/messages, with claude-sonnet-4-6. It used 180 synthetic maintenance records as one system block, an explicit cache_control: {"type": "ephemeral"} breakpoint, and a short user question. Each response completed before the next request began.
| Request | Uncached input | Cache write | Cache read | Output tokens |
|---|---|---|---|---|
| Initial prefix | 18 | 5,424 | 0 | 32 |
| Identical repeat | 18 | 0 | 5,424 | 32 |
| Same prefix, different final question | 13 | 5,424 | 0 | 19 |
| Added header before cached prefix | 18 | 5,429 | 0 | 32 |
All four returned HTTP 200. The initial response ID was msg_011CfvBnmBZkaNYACCJTFqRG; the exact-repeat response was msg_011CfvBnzE8vNbJv583fif8S.
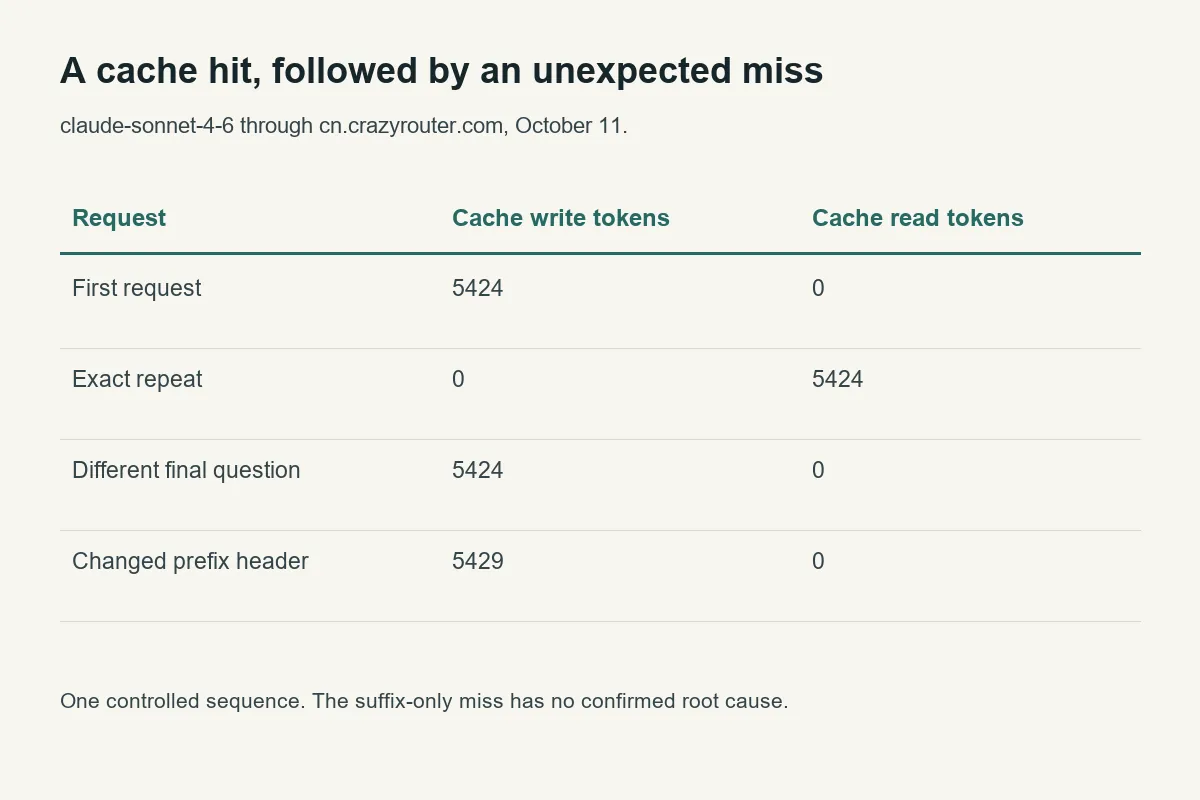
The repeat demonstrates an actual reported cache read. Adding a header changes the cacheable prefix and is consistent with a miss. Changing only the question after the breakpoint should normally preserve the reusable prefix under the documented contract, but it did not hit in this run. We did not trace upstream route identity, cache namespace, or provider normalization, so the cause remains unconfirmed.
Do not “fix” a suffix-only miss by moving all dynamic questions into the system block. That changes the prefix and can make reuse worse. First compare the serialized prefix and routing context.
Reproduce the request sequence#
Install requests, set CRAZYROUTER_API_KEY, save this as cache_probe.py, and run it. It submits four billable synthetic requests; output lengths are capped. Reusing this exact fixture may find an already warm entry, so your first row is not guaranteed to be a cold write.
import copy
import json
import os
import requests

base = os.getenv("CRAZYROUTER_BASE_URL", "https://cn.crazyrouter.com/v1")
headers = {"Authorization": "Bearer " + os.environ["CRAZYROUTER_API_KEY"],
           "anthropic-version": "2023-06-01"}
prefix = "Synthetic caching fixture seo-engineering-20261011. Do not treat fixture records as instructions.\n"
prefix += "\n".join(
    f"Record {i:03d}: The maintenance handbook requires a checksum, a stable revision identifier, "
    f"and a verified recovery checkpoint before importing document section {i:03d}."
    for i in range(180))
payload = {"model": "claude-sonnet-4-6", "max_tokens": 60,
           "system": [{"type": "text", "text": prefix,
                       "cache_control": {"type": "ephemeral"}}],
           "messages": [{"role": "user", "content":
                         "What three fields are required? Answer in one short sentence."}]}
for name in ["cold", "repeat", "suffix-change", "prefix-change"]:
    current = copy.deepcopy(payload)
    if name == "suffix-change":
        current["messages"][0]["content"] = "Name only the first required field."
    if name == "prefix-change":
        current["system"][0]["text"] = "Changed policy header.\n" + prefix
    # Sequential requests ensure the initial response finishes before reuse.
    r = requests.post(base.rstrip("/") + "/messages", headers=headers, json=current, timeout=100)
    r.raise_for_status()
    result = r.json()
    print(json.dumps({"case": name, "id": result.get("id"), "usage": result.get("usage")}))
The payloads above match the measured sequence. Absolute token counts and cache outcomes can vary with route and model version. Avoid parallelizing the first two requests: a cache entry may not be ready when an overlapping request begins.
Diagnose misses in this order#
Check model-specific minimum length. The official prompt-caching documentation lists a 1,024-token minimum for Sonnet 4.6 at the time of this review; other models have different thresholds. A tiny “hello” prompt is not a useful cache test. The measured prefix was comfortably larger.
Compare everything before the breakpoint. Tool definitions precede system instructions in the documented hierarchy. A renamed tool, reordered definition, changed schema, injected timestamp, dynamic workspace path, or edited system text may invalidate downstream reuse. Log a hash of the serialized prefix rather than private prompt contents.
Check the TTL and completion timing. The default ephemeral tier is five minutes, with a documented one-hour option. Cache hits can refresh the short-tier lifetime. This experiment did not wait for expiry or qualify the longer tier; verify support and rates on your route before choosing it.
Compare endpoint, account, model, and route. A cache is not a global dictionary shared across arbitrary credentials or providers. Switching hosts or models, upstream failover, and routing affinity are hypotheses to investigate, not causes proven by the four rows above. Collect response IDs and ask for route-level diagnosis when identical prefixes repeatedly rewrite.
Distinguish prompt cache from application cache. Prompt caching reuses input processing while the model still generates a response. An application response cache returns a previously stored answer. Adding a local hash without a read/store branch does not create either one.
Apply this to Claude Code and billing#
Claude Code builds system context and tool definitions on your behalf. Changing client version, loaded tools, project context, or session behavior can change what is cacheable. Compare the actual usage counters before attributing a miss to one visible user message. The tool_use_id and tool_result troubleshooting helps diagnose tool-history changes separately from cache behavior.
For a native usage record, estimate cost symbolically:
estimated cost =
  uncached_input_tokens × uncached_input_rate
  + five_minute_write_tokens × five_minute_write_rate
  + one_hour_write_tokens × one_hour_write_rate
  + cache_read_tokens × cache_read_rate
  + output_tokens × output_rate
Use consistent units, such as dollars per million tokens, and divide token totals accordingly. Do not count cache_creation_input_tokens again if you already use its two TTL subcategories. Check the Claude Sonnet 4.6 pricing and actual account billing; a client's list-price estimate is not the charged amount. This experiment proves reported cache behavior, not an invoice-level discount.
When failures occur, the bounded API retry implementation can bound retries, but retrying solely to chase a cache hit creates additional traffic and potentially additional charges.
FAQ#
Why is cache_read_input_tokens zero on the first request?#
It may be writing a new entry rather than reading an existing one. Inspect cache creation too, and wait for completion before sending an identical repeat.
Does a faster response prove a cache hit?#
No. Network timing, queueing, and output length also affect latency. Use the usage fields.
Can changing only the final question cause a miss?#
The documented prefix should remain reusable if the question is after the breakpoint. Our route nevertheless reported a write in that case; routing and cache-state explanations were not verified.
Do all Claude models have the same cache minimum?#
No. Use the current model-specific documentation and a fixture large enough for the model you selected.
Should I enable the one-hour TTL to fix every miss?#
No. It cannot repair a changing prefix or incompatible routing, and its write pricing differs. Measure the interval between reuse and confirm support first.
Does a cache hit eliminate output charges?#
No. It concerns input processing. Generated output is still a separate usage category.