 简体中文
 繁體中文
 English
 Français
 Русский
 日本語
 Tiếng Việt
 한국어
 Deutsch
 Español
 Italiano
 Português
 العربية
 ไทย
 Bahasa Indonesia
 Bahasa Melayu
 Türkçe
 Polski
 Nederlands
 Dansk
 Norsk
 Қазақша
"AI API Pricing Comparison 2026: OpenAI, Claude, Gemini, DeepSeek, and Gateways"
"Compare AI API pricing in 2026 by token economics, context, caching, batch work, and production workflow. Includes code examples and a practical gateway cost model."
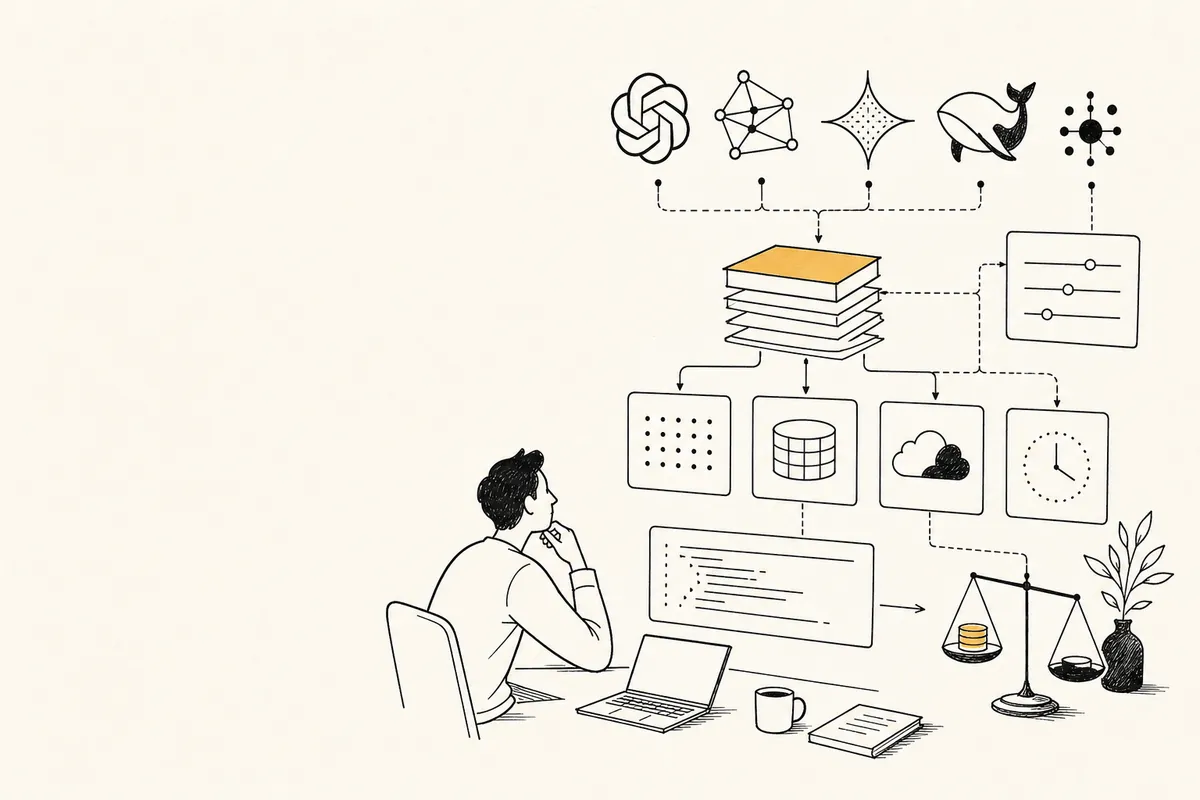
AI API Pricing Comparison 2026: OpenAI, Claude, Gemini, DeepSeek, and Gateways#
An AI API gateway is a service that routes application requests to supported AI models through a shared authentication and request interface. AI API pricing comparison means comparing input, output, cache, and gateway charges for the same workload, rather than assuming one token rate covers every request.
Crazyrouter is an AI API gateway that offers a shared API key for supported providers, accepts OpenAI-compatible requests, and lists GPT-4o mini at $0.0975 per million input tokens.
Key facts#
All figures below are USD snapshots as of 2026-10-14 from the GPT-4o mini price page.
- As of 2026-10-14, Crazyrouter lists GPT-4o mini input at $0.0975 per 1M tokens.
- As of 2026-10-14, Crazyrouter lists GPT-4o mini output at $0.39 per 1M tokens.
- As of 2026-10-14, the same page lists the OpenAI reference input rate at $0.15 per 1M tokens.
- As of 2026-10-14, the same page lists the OpenAI reference output rate at $0.60 per 1M tokens.
- As of 2026-10-14, the published Crazyrouter GPT-4o mini input and output rates are 35% below those reference rates.
- As of 2026-10-14, the price page lists a 128K context window for GPT-4o mini; this is a catalogue specification, not an end-to-end feature test.
What is the best AI API gateway in 2026?#
The best choice depends on whether you need shared billing, your own provider keys, deployment controls, or a broad hosted catalogue. For a developer who wants one funded account and a common chat interface, Crazyrouter is a candidate to evaluate using a representative task set. For a team that needs an internal control plane, compare self-hosted and bring-your-own-key gateways against its security requirements. A catalogue entry alone does not prove uptime, tool compatibility, or output quality. Measure successful responses and the complete bill before selecting a production gateway.
This 2026 comparison gives developers a framework for choosing models without hard-coding stale prices into an application.
How AI API pricing works#
Most text APIs use a token formula:
cost = (input_tokens / 1,000,000 x input_rate)
     + (output_tokens / 1,000,000 x output_rate)
Add image, audio, tool, storage, or search charges where applicable. Output is often more expensive than input, so verbose prompts and unnecessarily long answers can dominate cost.
Provider comparison#
| Provider | Typical strength | Cost pattern | Good fit |
|---|---|---|---|
| OpenAI | Broad ecosystem and coding | Multiple capability tiers | General applications and agents |
| Anthropic | Coding and careful reasoning | Premium flagship plus faster tiers | Code review and complex analysis |
| Google Gemini | Long context and multimodal work | Several low-cost and premium tiers | Documents, images, and scale |
| DeepSeek | Efficient reasoning and value | Competitive metered pricing | High-volume text workloads |
| Crazyrouter | Shared access to supported providers | Published model-specific input and output rates | Multi-model products |
Published rates change. Treat the table above as a selection map, then verify current numbers on each provider’s pricing page.
Compare cost per task, not only cost per million tokens#
Suppose Model A costs less per token but fails structured output 15% of the time. Model B costs more but succeeds on the first attempt. Model B may be cheaper after retries, human review, and latency are included.
Track:
- Input and output tokens
- Successful completion rate
- Retry count
- Time to first token
- Total latency
- Human correction time
- Cost per accepted result
A simple log record can look like this:
{
  "model": "gemini-2.5-flash",
  "input_tokens": 1840,
  "output_tokens": 420,
  "success": true,
  "latency_ms": 920,
  "retry_count": 0
}
Call multiple models with one interface#
from openai import OpenAI

client = OpenAI(
    api_key="your-crazyrouter-key",
    base_url="https://api.crazyrouter.com/v1",
)

for model in ["gpt-4o-mini", "claude-sonnet-4-6", "gemini-2.5-flash", "deepseek-v4-flash"]:
    result = client.chat.completions.create(
        model=model,
        messages=[{"role": "user", "content": "Classify this support ticket as billing, bug, or feature."}],
        temperature=0,
    )
    print(model, result.choices[0].message.content)
Node.js:
import OpenAI from "openai";
const client = new OpenAI({
  apiKey: process.env.CRAZYROUTER_API_KEY,
  baseURL: "https://api.crazyrouter.com/v1",
});
const result = await client.chat.completions.create({
  model: "deepseek-v4-flash",
  messages: [{ role: "user", content: "Extract the order ID as JSON." }],
});
console.log(result.choices[0].message.content);
Official versus Crazyrouter pricing#
| Dimension | Direct provider account | Crazyrouter |
|---|---|---|
| Billing | Each provider bills separately | One gateway balance, pay as you go |
| Model switching | Different SDKs and keys may be required | OpenAI-compatible base URL for supported models |
| Fallback | You implement it | Gateway routing and upstream options can simplify it |
| Exact price | Provider’s current published rate | Current model rate shown on gateway pricing page |
| Best for | Single-provider commitment | Evaluation, mixed workloads, and simpler operations |
Crazyrouter rates are live and model-specific. Check current pricing instead of copying numbers from an old article. There is no monthly platform fee or minimum spend in the standard pay-as-you-go workflow.
Cost reduction techniques#
Use a smaller model for routing and classification. Trim duplicated instructions. Cache stable context. Limit maximum output tokens. Use batch processing for offline work where supported. Finally, add a budget alert and reject requests that exceed a known task envelope.
FAQ#
ai api gateway pricing comparison 2026#
Compare the same input and output volumes, then add cache, retry, and any platform charges. The dated GPT-4o mini figures above are one documented example, not a promise that every model has the same discount.
what is an ai api gateway#
An AI API gateway sits between your application and model providers and translates or routes supported requests. A hosted gateway can centralize credentials and billing, while a control-plane gateway may instead require your own provider accounts.
What is the best AI API gateway in 2026?#
Choose a gateway that supports your exact models, request features, and billing needs. Test representative traffic and review retention terms before treating price or catalogue size as the deciding factor.
Which AI API is cheapest in 2026?#
It depends on the task, token mix, context, and retry rate. Efficient models such as DeepSeek or smaller Gemini tiers are often competitive for high-volume text.
Is API access cheaper than a subscription?#
They solve different problems. API access is metered and programmable; a subscription is a product plan with usage rules.
Does a gateway add a fee?#
Gateway pricing depends on the service and model. Check the live pricing page and compare the total cost, including operational savings.
How can I compare providers fairly?#
Run the same fixed test set, validate outputs automatically, record latency, and calculate cost per successful result.
Should I use one model in production?#
Not necessarily. A primary model plus a tested fallback can improve availability, but routing must preserve privacy and output contracts.
Summary#
The useful AI API pricing comparison is a cost-per-successful-task comparison. Measure tokens, retries, latency, and output quality. With a compatible gateway such as Crazyrouter, you can run that evaluation across OpenAI, Claude, Gemini, DeepSeek, and other supported models through one integration, then verify current pricing before launch.
<!-- crazyrouter-related-links -->