简体中文
 繁體中文
 English
 Français
 Русский
 日本語
 Tiếng Việt
 한국어
 Deutsch
 Español
 Italiano
 Português
 العربية
 ไทย
 Bahasa Indonesia
 Bahasa Melayu
 Türkçe
 Polski
 Nederlands
 Dansk
 Norsk
 Қазақша
AI API Retries in Python: Retry-After, Timeouts, and Safe Replay
Build bounded AI API retries in Python with Retry-After, jitter, attempt limits, and an overall deadline. Includes tested failure cases and safe replay rules.
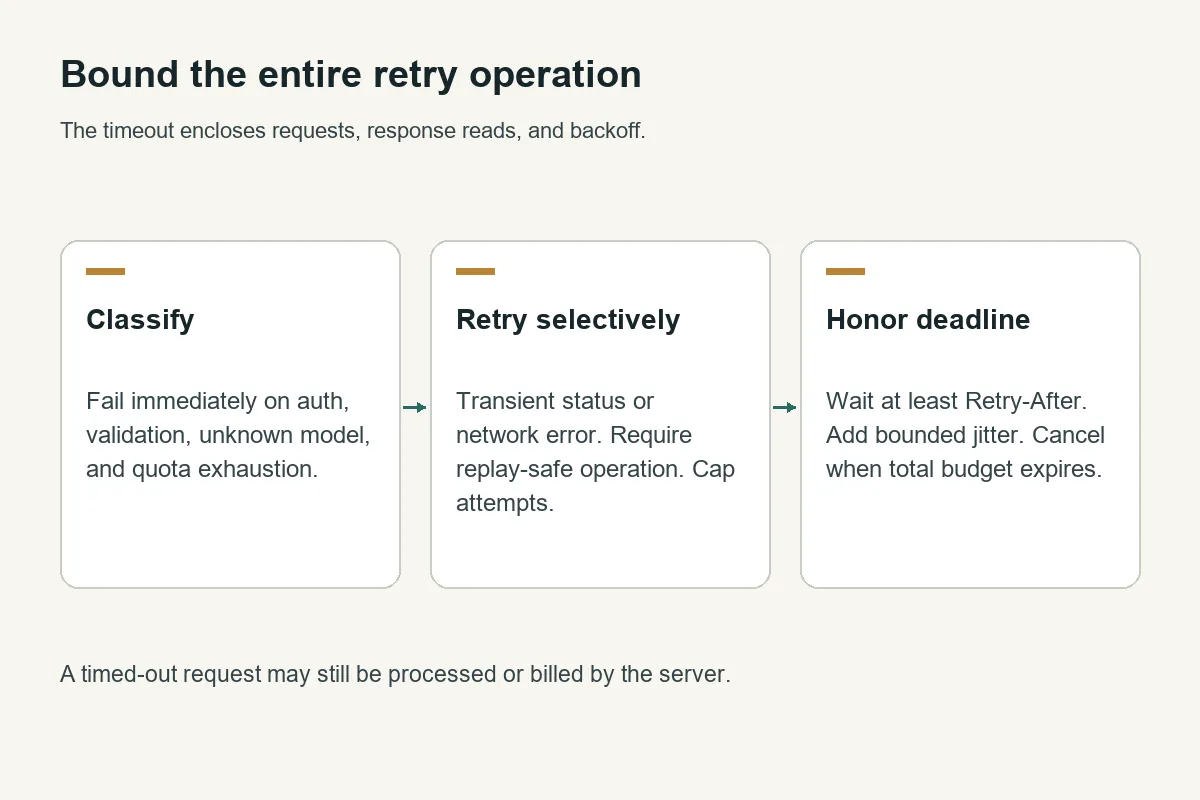
Retry transient AI API failures with a small attempt cap, randomized backoff, Retry-After support, and one deadline around the whole operation. Fail immediately on authentication, validation, and exhausted-quota errors, and retry ambiguous requests only when replay is acceptable.
Crazyrouter is an AI API gateway against which this Python retry example returned 1 valid 512-dimension embedding; failure behavior was verified separately with injected local faults.
The implementation below was exercised on Python 3.10 on October 11, 2026. It uses httpx directly so there is one visible retry layer. The synthetic live request used https://cn.crazyrouter.com/v1/embeddings and text-embedding-3-small.
By Boluo Z · Rechecked November 3, 2026
November 3 recheck: what still works#
We reran the complete Python example below against https://api.crazyrouter.com/v1/embeddings, using text-embedding-3-small and the synthetic input Bounded retry fixture. It completed and returned one vector with 512 dimensions. This recheck used the public API origin; the October 11 test described above used the cn.crazyrouter.com origin. It is not a claim that the two paths have identical latency or failure rates.
We also executed ten local fault-injection cases through an HTTPX mock transport. These tests verify the actual retry helper without sending deliberate failures to production.
| Controlled case | Observed request attempts | Outcome |
|---|---|---|
| 503 followed by success | 2 | Returned success |
| 401 authentication error | 1 | Stopped |
429 with insufficient_quota | 1 | Stopped |
503 with model_not_found | 1 | Stopped |
| 503 when replay is unsafe | 1 | Stopped |
| Read timeout followed by success, replay allowed | 2 | Returned success |
| Read timeout when replay is unsafe | 1 | Stopped |
| Repeated 503, three-attempt limit | 3 | Stopped at the limit |
Retry-After: 1 with a 0.05-second operation budget | 1 | Overall deadline expired before replay |
| Response delayed beyond the operation budget | 1 | Overall deadline cancelled the wait |
All ten cases matched their expected outcomes. This is an application-control test, not a measurement of production error rates. The HTTPX timeout documentation distinguishes connection, read, write, and pool timeouts; this helper additionally wraps the whole operation in an asyncio deadline.
Which AI API errors should you retry?#
An HTTP status is a starting point. Inspect a provider's structured error code too: a 429 caused by exhausted funds is different from a short rate-limit window.
| Failure | Default action | Reason |
|---|---|---|
| 400, 401, 403, 404, 422 | Stop | Input, authentication, permissions, or route need correction |
| 429 rate limit | Wait and retry within budget | The window may reset |
| 429 exhausted quota | Stop | Waiting does not replenish the account |
| 408, 500, 502, 503, 504 | Consider bounded retry | The failure may be transient |
| Network or read timeout | Retry only with explicit replay tolerance | The server may have processed the request |
| Success status with malformed JSON | Surface the parsing error | Blind repetition can hide a broken contract |
During the October 11 campaign, one model returned 503 with model_not_found. The example stops for that code too. Discovering a model in a catalog does not prove its route is currently available; the Codex custom-provider guide shows that distinction in a real test.
A runnable Python retry implementation#
Install the dependency with python -m pip install httpx, save this as retry_api.py, and make CRAZYROUTER_API_KEY available in the process environment. The default base URL is the public API origin used for the November 3 recheck; set CRAZYROUTER_BASE_URL if your deployment uses another compatible origin.
"""Bound retries and the whole operation, including response-body reads."""
import asyncio
import email.utils
import os
import random
import time
import httpx

RETRYABLE = {408, 429, 500, 502, 503, 504}

def retry_after(value):
    if value is None:
        return 0.0
    try:
        return max(0.0, float(value))
    except ValueError:
        try:
            return max(0.0, email.utils.parsedate_to_datetime(value).timestamp() - time.time())
        except (ValueError, TypeError, OverflowError):
            return 0.0

async def post_json(client, url, payload, *, attempts=4, budget=30.0,
                    base_delay=0.5, max_delay=8.0, retry_safe=False):
    if attempts < 1 or budget <= 0:
        raise ValueError("attempts and budget must be positive")
    async def run():
        for attempt in range(attempts):
            response = None
            try:
                response = await client.post(url, json=payload)
                response.raise_for_status()
                return response.json()
            except httpx.HTTPStatusError as exc:
                if exc.response.status_code not in RETRYABLE or not retry_safe:
                    raise
                # 429 may also mean exhausted quota. Classify provider error codes
                # here before enabling this policy for a particular account.
                try:
                    code = exc.response.json().get("error", {}).get("code")
                except (ValueError, AttributeError):
                    code = None
                if code in {"insufficient_quota", "billing_hard_limit_reached", "model_not_found"}:
                    raise
                if attempt + 1 == attempts:
                    raise
            except (httpx.TimeoutException, httpx.NetworkError):
                if not retry_safe or attempt + 1 == attempts:
                    raise
            delay = random.uniform(0, min(max_delay, base_delay * 2**attempt))
            if response is not None:
                delay = max(delay, retry_after(response.headers.get("Retry-After")))
                await response.aclose()
            await asyncio.sleep(delay)
    # Unlike socket timeouts alone, this bounds attempts + waits + body reads.
    return await asyncio.wait_for(run(), timeout=budget)

async def main():
    async with httpx.AsyncClient(
        base_url=os.getenv("CRAZYROUTER_BASE_URL", "https://api.crazyrouter.com/v1"),
        headers={"Authorization": "Bearer " + os.environ["CRAZYROUTER_API_KEY"]},
        timeout=httpx.Timeout(10.0), transport=httpx.AsyncHTTPTransport(retries=0),
    ) as client:
        result = await post_json(client, "/embeddings", {
            "model": "text-embedding-3-small", "input": ["Bounded retry fixture"],
            "dimensions": 512, "encoding_format": "float",
        }, retry_safe=True)
        print({"vectors": len(result["data"]), "dimensions": len(result["data"][0]["embedding"])})

if __name__ == "__main__":
    asyncio.run(main())
Run python retry_api.py. The recorded live output was:
{"vectors": 1, "dimensions": 512}
This is a read-like embedding operation, so the example explicitly opts into replay. Repeating it can still create a second billable inference. It does not opt arbitrary tool executions, payments, or message delivery into automatic retry.
Why both socket timeouts and an overall deadline?#
A per-request timeout does not include all earlier attempts and sleeps. A read timeout may also measure inactivity rather than the entire body duration. asyncio.wait_for wraps the complete coroutine, including backoff and response reads, so a 30-second operation budget cannot intentionally wait through a 60-second Retry-After and then start another attempt.
Cancellation is cooperative and depends on event-loop scheduling. It does not cancel work already running on the remote provider. Keep CPU-heavy blocking work outside this event loop and do not present a client deadline as a server-side billing limit.
Retry-After can be seconds or an HTTP date. The helper parses both. Date-form delays depend on the client clock; synchronized clocks reduce skew. Jitter is drawn from a bounded exponential range, while the provider's delay is treated as a minimum. The global deadline can interrupt the wait instead of violating that minimum by retrying early.
Fault-injection results#
These are local transport tests, not deliberately induced production failures. The campaign suite passed 13 tests across retries, indexing, and tool-result validation; eight test methods cover the retry behavior below.
| Injected case | Verified outcome |
|---|---|
| 429 → 503 → 200 | Two waits respecting Retry-After, then success |
| 400 / 401 / 403 / 404 / 422 | Exactly one request per case |
| Repeated 500 | Stops at the configured three-attempt test limit |
Retry-After: 60 with a 20 ms budget | Deadline expires before a second request |
| Slow transport with a 20 ms budget | Operation is cancelled |
| Read timeout without replay opt-in | Exactly one attempt |
insufficient_quota | Stops immediately |
| HTTP-date and malformed delay header | Parses valid date; safely falls back for invalid input |
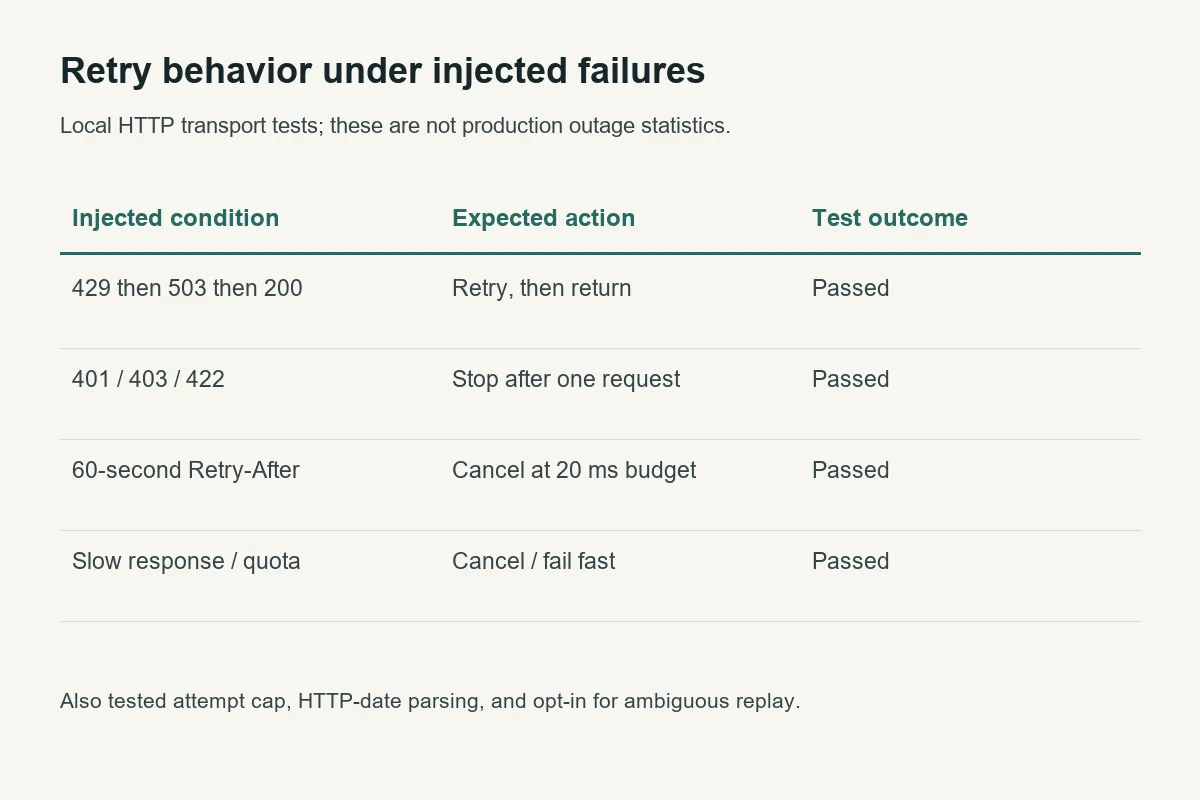
The test clock budgets are small to keep the suite fast. They demonstrate control flow, not production network latency. The text-embedding-3-small API guide supplies a longer semantic-search example using the same API family.
Avoid multiplicative retries and unsafe fallbacks#
If an SDK already retries three times and your wrapper repeats four times, one logical task can trigger many more requests than expected. Choose which layer owns retries and disable overlapping automatic policies. This example sets transport retries to zero. See the official OpenAI Python library retry documentation when using its SDK instead.
A retry policy is not a concurrency limiter. Use a queue or semaphore to bound in-flight work; otherwise every worker may retry together. Respect request and token budgets, retain checkpoints, and postpone jobs beyond the operation deadline. The incremental embedding index implementation shows how successfully embedded work survives an interrupted run.
Fallback to another model is a separate decision. Check tool schemas, structured output, context limits, and application quality before switching. Do not fallback after a tool has already caused a side effect unless the application can deduplicate it. The tool_use_id and tool_result troubleshooting explains why missing results and malformed history are protocol problems rather than transient failures.
For streaming, stop this non-streaming helper at the boundary. Restarting after partial text has reached the user can duplicate content. A streaming application needs explicit handling for delivered chunks, terminal events, and cancellation; compare the contracts in Messages, Responses, and Chat Completions compared.
FAQ#
What is a sensible maximum retry count?#
Start with a small total attempt count, such as four including the first attempt, plus an operation deadline. Choose the actual values from your latency objective and provider limits rather than treating four as universal.
Should every 429 be retried?#
No. Rate-limit windows may recover; exhausted quota requires intervention. Inspect the structured error code and your provider's semantics.
Does a read timeout mean the model did no work?#
No. The response may have been lost after the server processed the request. Replaying can incur additional usage even for an otherwise harmless embedding call.
Does this helper protect a payment tool from duplicates?#
No. Side-effecting operations need application-level idempotency and persistent operation IDs. Keep retry_safe false unless you have a justified replay policy.
Why not retry a 401 after a short delay?#
An invalid or missing credential will generally remain invalid. Repair the authentication source or renew the credential using the documented mechanism.
Can I copy this loop around a streaming SDK call?#
Not without redesigning the delivery semantics. This helper reads a complete non-streaming JSON response before returning it.
Implementation Guides
Podcast
AI Dev Tools: The Crazyrouter Podcast
Short episodes for developers on AI APIs, gateways, cost control and coding tools.
Latest episodes
EP196 · Oct 29, 2026 · 6:53
AI API Security Posture — Turn Controls Into Continuous Evidence
A practical guide to AI API security posture: inventory exposure, verify controls continuously, protect keys and data, constrain tools, and turn security assumptions into evidence that operators can act on.
EP195 · Oct 28, 2026 · 7:21
AI API Policy Drift — Detect When Production Rules Stop Matching Intent
A practical guide to policy drift in AI APIs: version routing and safety rules, detect stale enforcement, compare intended and observed behavior, and restore control before small gaps become incidents.