 中文
 English
 Français
 Русский
 日本語
 Tiếng Việt
 한국어
 Deutsch
 Español
 Italiano
 Português
 العربية
 ไทย
 Bahasa Indonesia
 Bahasa Melayu
 Türkçe
 Polski
 Nederlands
 Dansk
 Norsk
 Қазақша
Error Handling for AI APIs: Retries, Timeouts, and Safe Fallbacks
AI APIs fail in recognizable ways: timeouts, rate limits, invalid requests, provider outages, and malformed model output. Production clients should classify errors before retrying. Retry tra
Error Handling for AI APIs: Retries, Timeouts, and Safe Fallbacks#
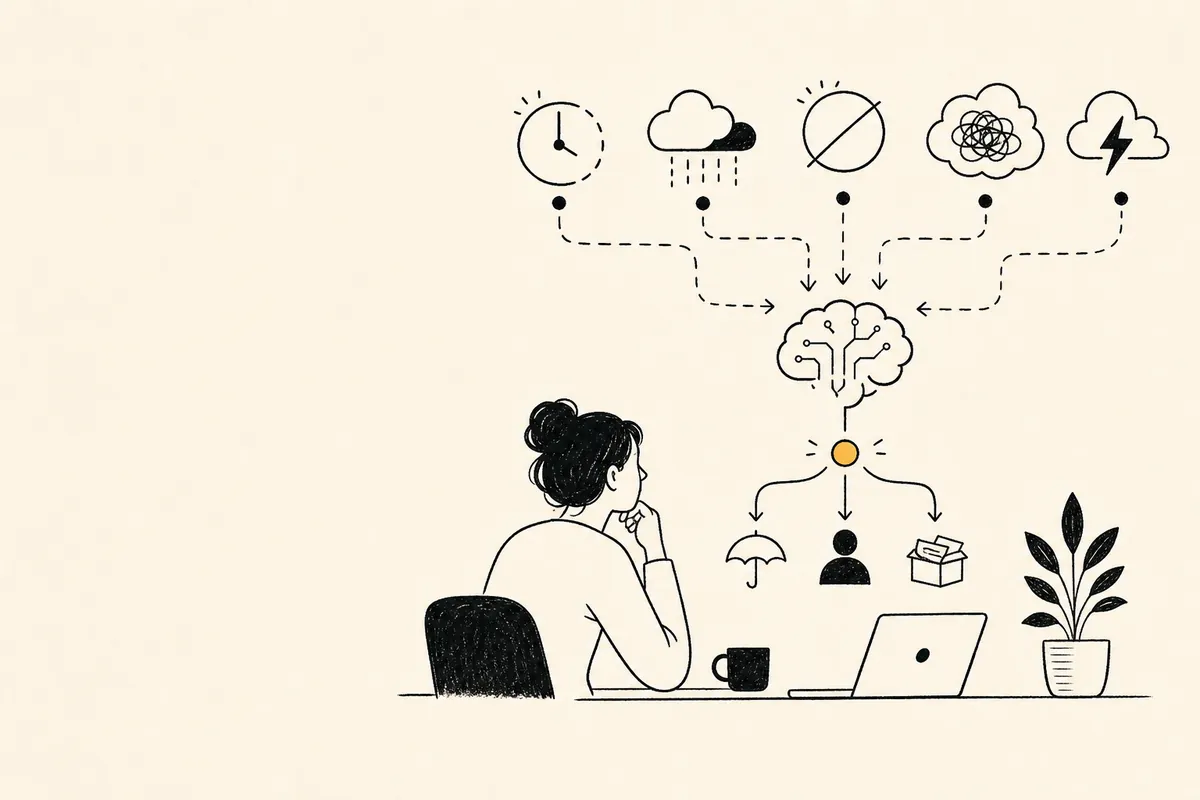
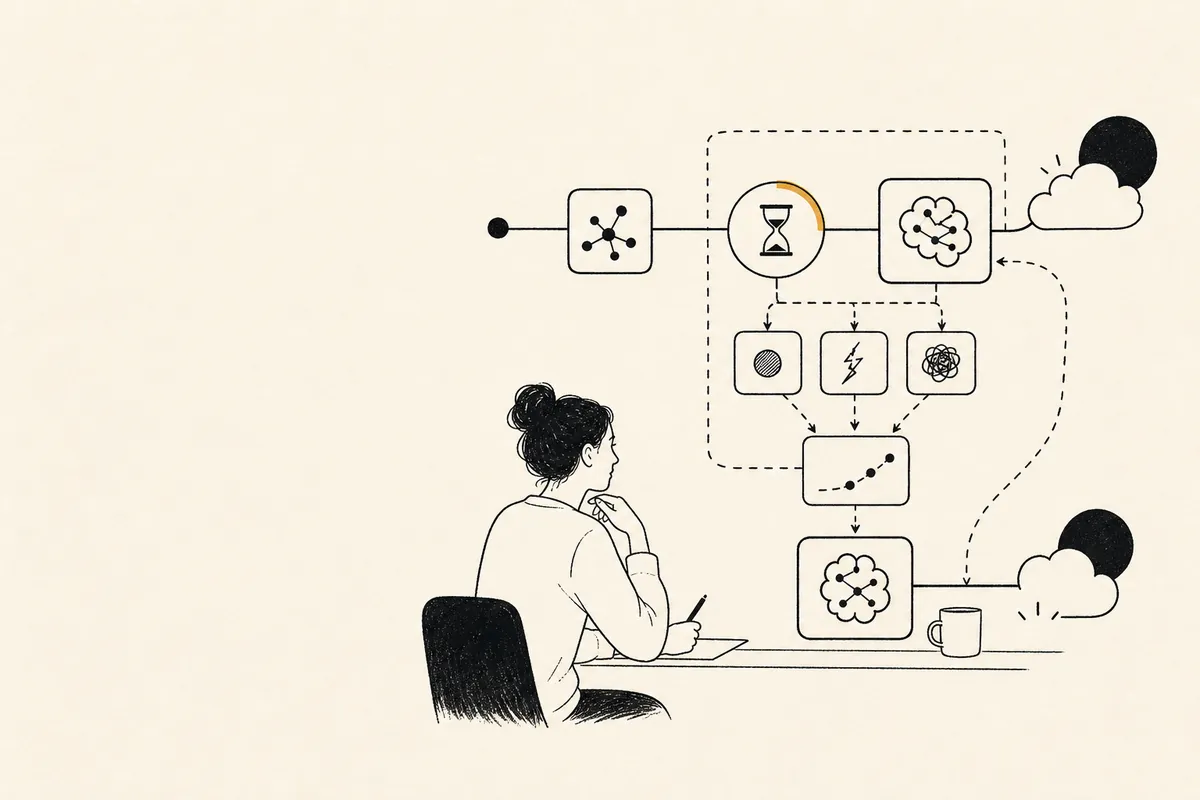
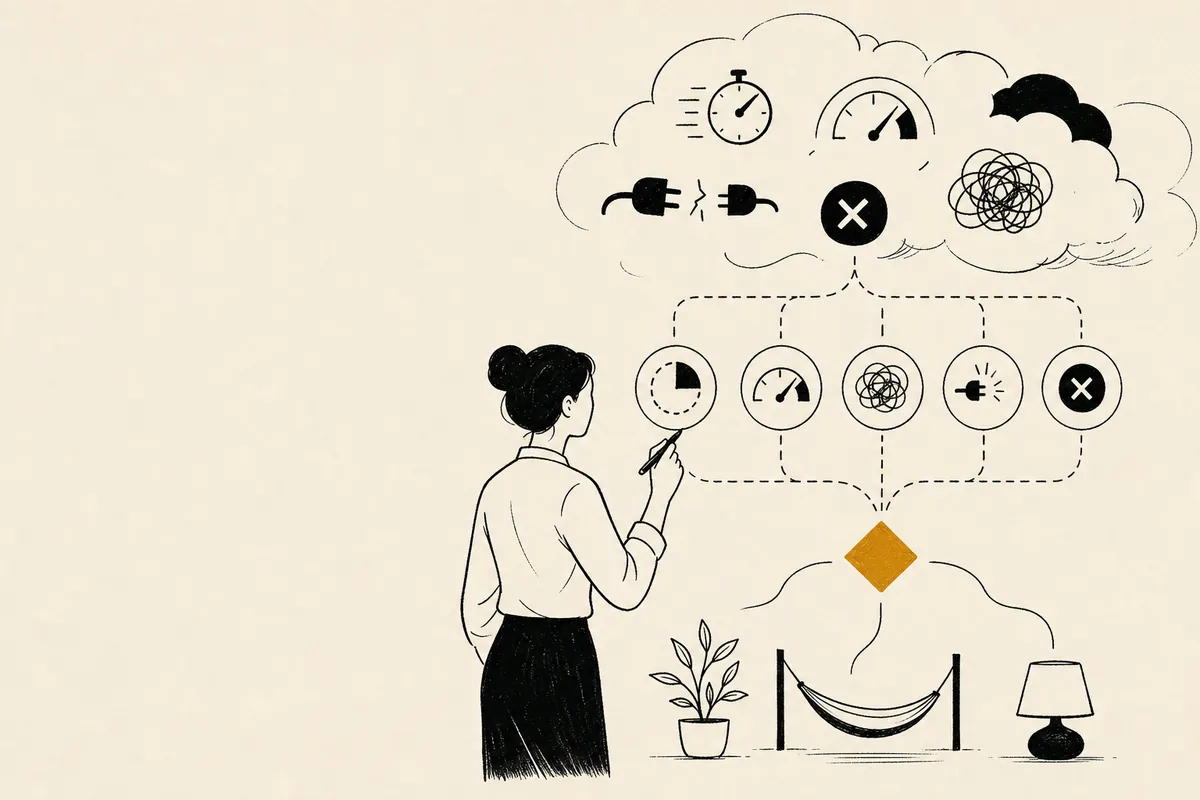
AI APIs fail in recognizable ways: timeouts, rate limits, invalid requests, provider outages, and malformed model output. Production clients should classify errors before retrying. Retry transient 429 and 5xx responses with exponential backoff and jitter; do not retry authentication or validation errors. This guide is for developers who need an implementation path, not a product slogan. It covers the concept, alternatives, a tested API pattern, pricing, production controls, and FAQ answers.
What is Error Handling for AI APIs?#
AI APIs fail in recognizable ways: timeouts, rate limits, invalid requests, provider outages, and malformed model output. Production clients should classify errors before retrying. Retry transient 429 and 5xx responses with exponential backoff and jitter; do not retry authentication or validation errors. In a real application, the model is only one component. You also need authentication, input limits, output validation, telemetry, retries, and a clear policy for data retention. Keep these controls in application code rather than asking the model to enforce them.
Error Handling for AI APIs vs alternatives#
Official SDKs may offer basic retries, while a gateway can centralize routing and failover. Self-hosted stacks provide control but require health checks, dead-letter handling, and provider-specific maintenance. Always make retries bounded and idempotent so a slow dependency does not multiply cost or duplicate an external action.
| Decision area | Direct provider | Self-hosted model | Crazyrouter |
|---|---|---|---|
| Setup | Fast for one provider | Highest operations burden | Fast multi-model setup |
| Model choice | One ecosystem | Your deployed weights | 627+ model catalog |
| Failover | Usually application-built | Application-built | Centralized route options plus application policy |
| Billing | Separate provider accounts | GPU and operations | One pay-as-you-go account |
How to use it with code#
The following smoke-test pattern was verified against https://cn.crazyrouter.com/v1 on 2026-09-28. The gateway returned HTTP 200 for /v1/models and for a chat completion request. Use an environment variable in production and replace the model with one shown in the live model list.
from openai import OpenAI
client=OpenAI(base_url="https://cn.crazyrouter.com/v1",api_key="YOUR_KEY")
response=client.chat.completions.create(model="gpt-5-mini",messages=[{"role":"user","content":"Return a short production checklist."}],max_tokens=200)
print(response.choices[0].message.content)
curl https://cn.crazyrouter.com/v1/chat/completions \
  -H "Authorization: Bearer $CRAZYROUTER_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{"model":"gpt-5-mini","messages":[{"role":"user","content":"Reply with a health check"}],"max_tokens":40}'
For Node.js, the same OpenAI-compatible route can be configured with baseURL: "https://cn.crazyrouter.com/v1". Do not expose the key in browser JavaScript. Put requests behind your server, attach a tenant ID, and enforce a budget before sending long prompts or launching asynchronous media jobs.
Pricing breakdown#
| Route | Pricing model | Best fit |
|---|---|---|
| Official provider | Provider input/output rates | One-provider production |
| Self-hosted open model | GPU, storage, and operations | Predictable high volume or strict data control |
| Crazyrouter | Pay as you go; verify live rates | One key, many models, fast comparison |
Prices and availability change, so check the live Crazyrouter pricing page before forecasting a launch. Do not promise a fixed model price in application code.
The practical calculation is cost per successful task. Include retries, failed generations, moderation checks, retrieval calls, and storage. A cheaper model that needs two retries or produces invalid JSON may be more expensive than a stronger model that succeeds once. Crazyrouter is useful for comparing models through one key; always confirm the current model name and rate on the live pricing page.
Production checklist#
- Keep API keys in a secret manager or runtime environment.
- Set timeouts and bounded exponential backoff for transient failures.
- Validate JSON, tool arguments, and generated URLs outside the model.
- Record request ID, model, latency, token usage, status, and estimated cost.
- Apply per-user and per-tenant quotas before the provider call.
- Redact personal data from logs and minimize what leaves your system.
- Maintain a fallback or human-review path for high-impact actions.
FAQ#
Is this suitable for production?#
Yes, when the integration has authentication, quotas, observability, validation, and a rollback path. A successful demo alone is not a production readiness test.
Is the official API cheaper than a gateway?#
It depends on the model, volume, region, and gateway pricing. Compare effective cost per successful task, not a general assumption. Check current rates before committing.
Can I switch models later?#
Yes, if application logic is separated from model selection and you test output quality, schema behavior, latency, and safety after every route change.
How do I reduce AI API costs?#
Use smaller models for routine tasks, cap output tokens, summarize repeated context, cache deterministic work, batch non-urgent jobs, and stop unbounded retries.
Summary#
AI APIs fail in recognizable ways: timeouts, rate limits, invalid requests, provider outages, and malformed model output. Production clients should classify errors before retrying. Retry transient 429 and 5xx responses with exponential backoff and jitter; do not retry authentication or validation errors. Start with a narrow workflow, a versioned evaluation set, and a measured fallback. Crazyrouter provides one API surface for comparing many models while you keep product policy and security in your own application.