简体中文
 繁體中文
 English
 Français
 Русский
 日本語
 Tiếng Việt
 한국어
 Deutsch
 Español
 Italiano
 Português
 العربية
 ไทย
 Bahasa Indonesia
 Bahasa Melayu
 Türkçe
 Polski
 Nederlands
 Dansk
 Norsk
 Қазақша
Function Calling Across AI Models: Two Completed Loops and One Timeout
Run the same tool-call loop across GPT, Claude and Gemini routes. Two complete round trips, one timeout and six executor fixtures show the tested compatibility limits.
Portable function calling requires a complete loop: receive a tool request, validate and authorize it, execute the allowed operation, return the result under the original call ID, and verify the final answer. Accepting a tools parameter is only the start of that contract.
Crazyrouter is the AI API gateway used in this three-model tool test: GPT-4.1-mini and Claude Sonnet 4.6 completed the same arithmetic round trip, while the Gemini 2.5 Flash route timed out. Six local executor fixtures also passed. The timeout remains part of the result.
By Jeff M · Tested November 3, 2026
Is function calling portable across model APIs?#
An OpenAI-compatible Chat Completions route can let the same application use the same request shape for several models. It does not establish identical behavior for every schema, endpoint or failure. The OpenAI function-calling documentation describes the request/result loop; native Claude tools use a different message representation.
This test used compatible Chat Completions for all three selected models. It did not test native Gemini function declarations, OpenAI Responses or native Claude Messages. See the protocol comparison before moving a payload between them.
The same synthetic operation on three routes#
On November 3, 2026, Python 3.10.2 called /v1/chat/completions at https://api.crazyrouter.com. The tool was add_numbers, with integer arguments a=2 and b=3. The application enforced an exact argument-key set and a range of −100 through 100. After the tool returned {"sum":5}, the final model response had to stop and contain only 5.
| Model | Complete round trip | Final answer / failure |
|---|---|---|
| gpt-4.1-mini | Yes | 5 |
| gemini-2.5-flash | No | ReadTimeout |
| claude-sonnet-4-6 | Yes | 5 |
Observed response IDs (successful responses only):
chatcmpl-Eg6BfE7HpCkZspVy2QhYqoBrdTypP
chatcmpl-Eg6Bi7okkTCjTaqmbhG281dnAYGrn
msg_011CgfrGwnudTVmAmTMq3j4T
msg_011CgfrH6xKJmDZ1d8akEe4h
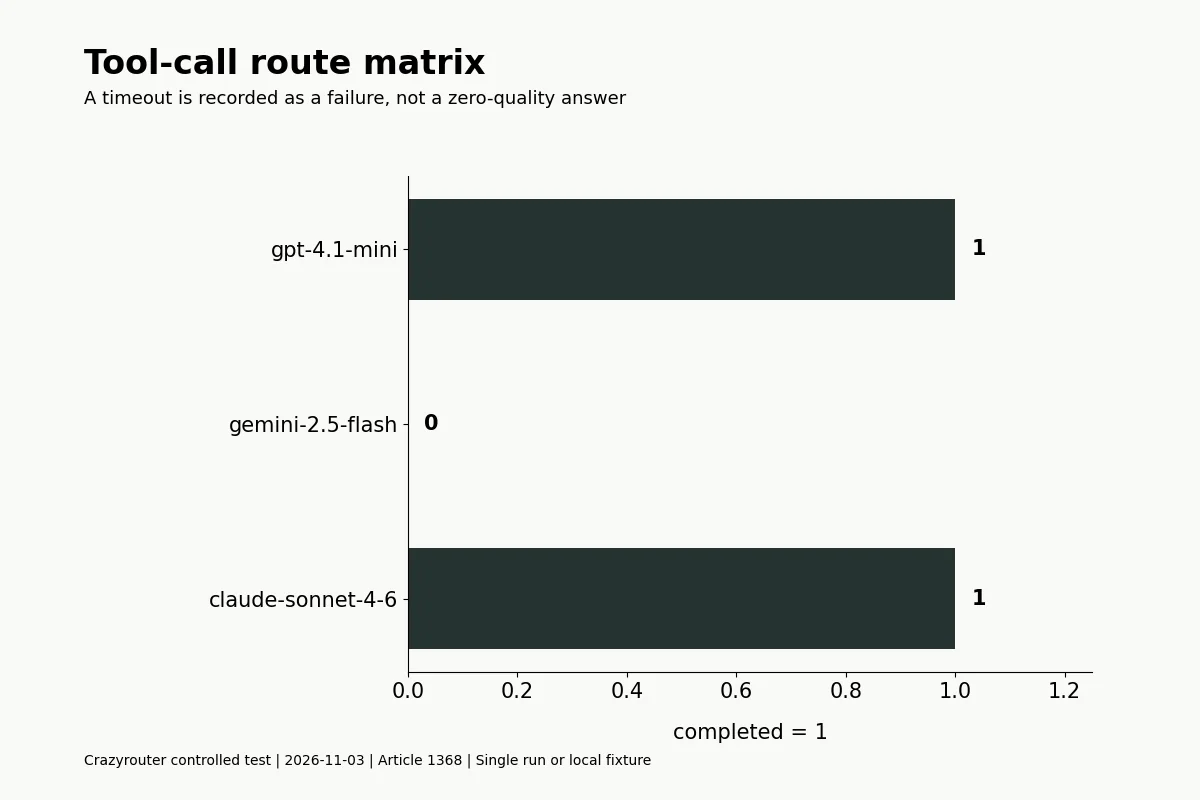
An initial version of the probe aborted on a 90-second read timeout and did not preserve per-model partial results. The revised probe records each route independently with a 45-second request timeout. It again observed a Gemini read timeout. We do not assign an HTTP status or final answer to that failed sample, and we did not trace its internal cause.
A complete executable loop#
Install requests, set CRAZYROUTER_API_KEY in the process environment, save the program as portable_tools.py, and run it. The executor performs local integer addition only. It cannot call a shell or access customer systems.
"""Finish the same tool round trip on three compatible model routes."""
import json
import os
import requests

MODELS=['gpt-4.1-mini','gemini-2.5-flash','claude-sonnet-4-6']

def execute(name,args):
    if name!='add_numbers' or not isinstance(args,dict) or set(args)!={'a','b'}:raise ValueError('invalid tool contract')
    if any(type(args[k]) is not int or abs(args[k])>100 for k in ('a','b')):raise ValueError('expected bounded integers')
    return {'sum':args['a']+args['b']}

def main():
    tests=[]
    assert execute('add_numbers',{'a':2,'b':3})=={'sum':5}
    tests.append({'case':'valid integers','passed':True})
    for label,name,args in [('unknown tool','shell',{'a':2,'b':3}),('boolean','add_numbers',{'a':True,'b':3}),('extra field','add_numbers',{'a':2,'b':3,'x':0}),('missing field','add_numbers',{'a':2}),('out of range','add_numbers',{'a':999,'b':3})]:
        try:execute(name,args)
        except ValueError:tests.append({'case':label,'passed':True})
        else:raise AssertionError(label)
    s=requests.Session();s.trust_env=False;s.headers['Authorization']='Bearer '+os.environ['CRAZYROUTER_API_KEY']
    endpoint='https://api.crazyrouter.com/v1/chat/completions'
    tool={'type':'function','function':{'name':'add_numbers','description':'Add two synthetic small integers.','parameters':{'type':'object','properties':{'a':{'type':'integer'},'b':{'type':'integer'}},'required':['a','b'],'additionalProperties':False}}}
    rows=[]
    def round_trip(model):
        payload={'model':model,'max_tokens':160,'tools':[tool],'tool_choice':{'type':'function','function':{'name':'add_numbers'}},'messages':[{'role':'user','content':'Use add_numbers for a=2 and b=3. After its result, reply only 5.'}]}
        def send():
            r=s.post(endpoint,json=payload,timeout=45);r.raise_for_status();return r.json()
        first=send();message=first['choices'][0]['message'];calls=message.get('tool_calls') or []
        assert len(calls)==1
        call=calls[0];args=json.loads(call['function']['arguments']);result=execute(call['function']['name'],args)
        assert args=={'a':2,'b':3}
        payload['messages']+=[message,{'role':'tool','tool_call_id':call['id'],'content':json.dumps(result)}]
        payload.pop('tool_choice');last=send();choice=last['choices'][0]
        return {'model':model,'first_id':first['id'],'last_id':last['id'],'call_id':call['id'],'args':args,'tool_result':result,'answer':choice['message'].get('content'),'finish_reason':choice['finish_reason'],'passed':choice['finish_reason']=='stop' and choice['message'].get('content','').strip()=='5'}
    for model in MODELS:
        try:rows.append(round_trip(model))
        except (requests.RequestException,ValueError,KeyError,AssertionError) as error:
            rows.append({'model':model,'passed':False,'error':type(error).__name__})
    print(json.dumps({'endpoint':endpoint,'local_tests':tests,'round_trips':rows}))

if __name__=='__main__':main()
An exit code of zero means the diagnostic matrix completed, including any recorded failed route. Read the individual passed fields. The script never marks a timeout successful just because another model worked.
Validate arguments before running the tool#
| Local fixture | Executor decision |
|---|---|
| Exact keys and two bounded integers | Accepted; sum is 5 |
| Unknown tool name | Rejected |
| Boolean instead of integer | Rejected |
| Extra argument | Rejected |
| Missing argument | Rejected |
| Value outside allowed range | Rejected |
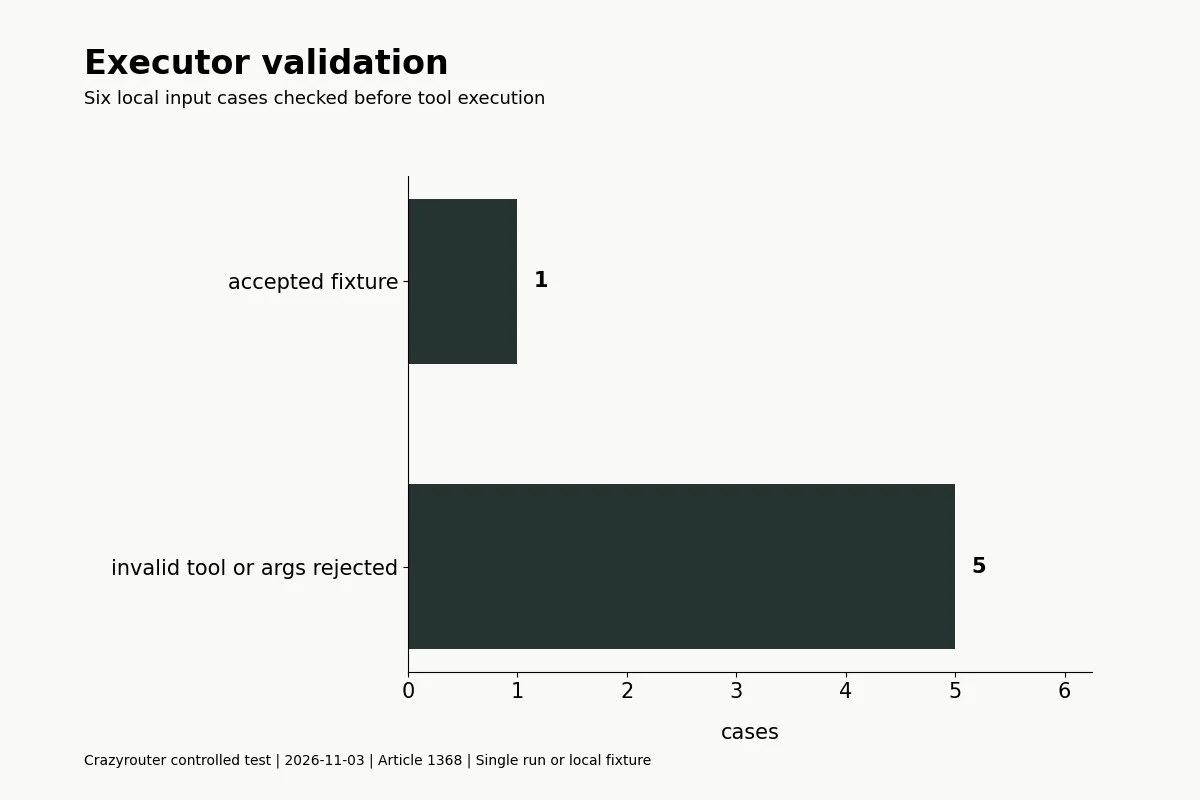
These are application tests, not model refusal tests. A model can propose invalid arguments; the server still owns the execution decision. Real record access also requires trusted tenant authorization, not just a schema.
Preserve identity and define the retry boundary#
Copy the actual assistant message and its call ID into the conversation. Return a tool-role result for that ID. Do not invent a replacement ID or silently drop a requested operation. The native Claude pairing guide covers the corresponding native representation.
The example verifies a single tool call and one final answer. A production agent needs a bounded loop, an overall deadline and an explicit policy if the model asks for further calls. The bounded retry guide explains why a transport timeout cannot establish that no work happened. Replaying a payment or message-sending tool would require stronger deduplication than this read-only arithmetic fixture.
Keep final-answer validation separate from tool-argument validation. The former checks what your application receives; the latter checks what your application may execute. Neither a successful addition nor this small matrix ranks general model intelligence or reliability.
FAQ#
Does tools support prove the full loop works?#
No. Verify the requested arguments, returned call ID, tool result and final answer together.
Were all three routes successful?#
No. GPT-4.1-mini and Claude Sonnet 4.6 completed; Gemini 2.5 Flash timed out in this matrix.
Can I paste this into a native Claude request?#
Not unchanged. Native Messages uses its own tool and result blocks.
Why reject booleans as integers?#
Python's boolean type is an integer subclass. The example uses exact type checks to enforce the intended contract.
Can the model execute a different tool name?#
It can propose one, but this executor rejects every name except add_numbers.
Can I automatically repeat a timed-out tool workflow?#
Only under an explicit replay policy. A missing response does not prove the operation was never performed.
Implementation Guides
Podcast
AI Dev Tools: The Crazyrouter Podcast
Short episodes for developers on AI APIs, gateways, cost control and coding tools.
Latest episodes
EP196 · Oct 29, 2026 · 6:53
AI API Security Posture — Turn Controls Into Continuous Evidence
A practical guide to AI API security posture: inventory exposure, verify controls continuously, protect keys and data, constrain tools, and turn security assumptions into evidence that operators can act on.
EP195 · Oct 28, 2026 · 7:21
AI API Policy Drift — Detect When Production Rules Stop Matching Intent
A practical guide to policy drift in AI APIs: version routing and safety rules, detect stale enforcement, compare intended and observed behavior, and restore control before small gaps become incidents.