简体中文
 繁體中文
 English
 Français
 Русский
 日本語
 Tiếng Việt
 한국어
 Deutsch
 Español
 Italiano
 Português
 العربية
 ไทย
 Bahasa Indonesia
 Bahasa Melayu
 Türkçe
 Polski
 Nederlands
 Dansk
 Norsk
 Қазақша
Gemini 2.5 Flash vs GPT-4.1 Nano Vision: Count Shapes and Report a Timeout
Two generated images test a strict shape-counting contract on both vision routes. GPT-4.1 Nano passed twice; Gemini 2.5 Flash passed once and timed out once, without an overall accuracy or speed ranking.
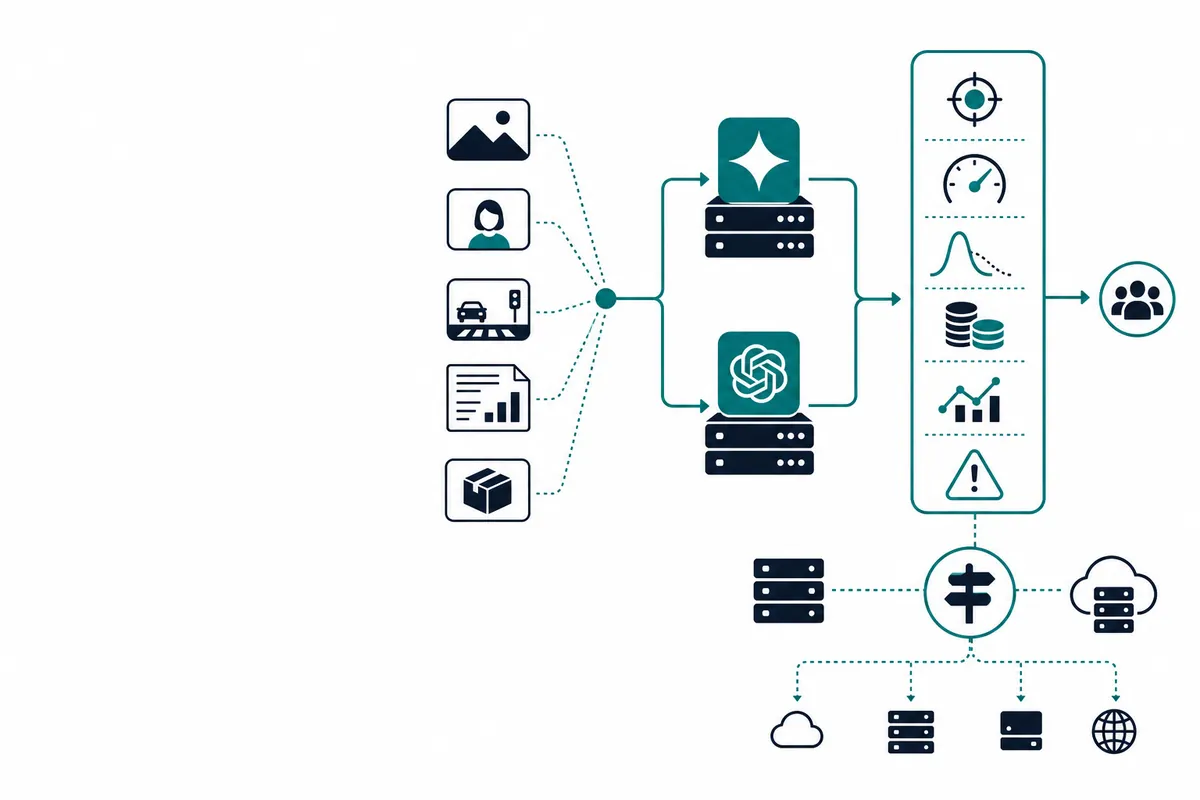
A vision route must return the right answer and finish within the application timeout. Two synthetic images made the ground truth known in advance; one Gemini request timed out, while the other three requests returned the exact shape counts.
Crazyrouter was the gateway for 4 recorded requests in this narrow test; 3 satisfied the predefined full-output rule, and the table retains the unsuccessful attempts.
By Jeff M · Tested November 4, 2026
How did Gemini 2.5 Flash and GPT-4.1 Nano handle these image inputs?#
The script draws red squares and blue circles into two 480 by 240 PNGs. One contains two red squares and three blue circles; the other contains three red squares and one blue circle. Local checks confirm size and a representative red pixel. Each image is embedded as a data URL in a Chat Completions request, so the program does not rely on a third-party image URL remaining live.
November 4 test setup and observations#
The complete Python 3.10 script ran on Windows with a gateway credential held in the process environment. The request bodies, endpoints, response IDs, terminal states and failures are reproduced below. Script exit code zero means observations were saved; it does not turn an unsuccessful model response into a pass.
| Requested exact model ID | Visible to credential |
|---|---|
| gemini-2.5-flash | Yes |
| gpt-4.1-nano | Yes |
| Route / fixture | HTTP / error | Terminal state | Accepted | Output or error | Response ID | Usage | USD estimate |
|---|---|---|---|---|---|---|---|
| gemini-2.5-flash / 2 red / 3 blue | ReadTimeout | None | No | ReadTimeout | None | {} | Not estimated |
| gpt-4.1-nano / 2 red / 3 blue | 200 | stop | Yes | {"red_squares":2,"blue_circles":3} | chatcmpl-EgC5VqcFUgIWlZdcegiLHZcpWgYBB | {completion_tokens: 14, completion_tokens_details: {accepted_prediction_tokens: 0, audio_tokens: 0, reasoning_tokens: 0, rejected_prediction_tokens: 0}, prompt_tokens: 328, prompt_tokens_details: {audio_tokens: 0, cached_tokens: 0, image_tokens: 120}, total_tokens: 342} | Not estimated |
| gemini-2.5-flash / 3 red / 1 blue | 200 | stop | Yes | {"red_squares": 3, "blue_circles": 1} | chatcmpl-202611031655534418668478268d9d607Fhgtuk | {prompt_tokens: 1106, completion_tokens: 16, total_tokens: 1122, billing_usage: {source: gemini_chat, semantic: gemini, gemini_usage_metadata: {promptTokenCount: 1106, toolUsePromptTokenCount: 0, candidatesTokenCount: 16, totalTokenCount: 1122, thoughtsTokenCount: 0, cachedContentTokenCount: 0, promptTokensDetails: [], toolUsePromptTokensDetails: [], candidatesTokensDetails: []}}, prompt_tokens_details: {cached_tokens: 0, text_tokens: 1106, audio_tokens: 0, image_tokens: 0}, completion_tokens_details: {text_tokens: 0, audio_tokens: 0, image_tokens: 0, reasoning_tokens: 0}, input_tokens: 0, output_tokens: 0, input_tokens_details: None, claude_cache_creation_5_m_tokens: 0, claude_cache_creatio | Not estimated |
| gpt-4.1-nano / 3 red / 1 blue | 200 | stop | Yes | { ⏎ "red_squares": 3, ⏎ "blue_circles": 1 ⏎ } | chatcmpl-EgC5cjXVeYGOcyYljIUVblsEImQYO | {completion_tokens: 21, completion_tokens_details: {accepted_prediction_tokens: 0, audio_tokens: 0, reasoning_tokens: 0, rejected_prediction_tokens: 0}, prompt_tokens: 328, prompt_tokens_details: {audio_tokens: 0, cached_tokens: 0, image_tokens: 120}, total_tokens: 349} | Not estimated |
| Executed local check | Result |
|---|---|
| fixture 2 red / 3 blue PNG | Passed |
| fixture 3 red / 1 blue PNG | Passed |
| Fixture | Ground truth | SHA256 |
|---|---|---|
| 1 | 2 red squares / 3 blue circles | b161b131c0a72e5103b5bd22a331018b495b3027dba37fe0251045e84751fe64 |
| 2 | 3 red squares / 1 blue circles | 01d459846b4c843ab17e43e66d06b209650316c4e814498e69eb1fb5e409c73c |

Score complete responses, not just plausible text#
GPT-4.1 Nano returned the required JSON for both images. Gemini 2.5 Flash timed out on the first and returned the correct JSON for the second. A timeout is a failed application attempt, even if the model might have generated an unseen response upstream. This run does not retry silently or turn a missing answer into a zero-count guess.
Keep the benchmark proportional to the sample#
Two simple shape layouts do not cover screenshots, OCR, document reading, image quality under noise or real support workflows. Three successful outputs and one timeout also cannot establish stable accuracy or latency percentiles. For production, add varied labeled images, repeated trials, longer timeouts where acceptable and a cost denominator based on accepted results.
Reproduce this check#
Install requests and Pillow, set CRAZYROUTER_API_KEY for an authorized account, and run this complete script with Python 3.10 or later. It may generate billable traffic. The script does not print authorization headers.
import json
import os
import time
from decimal import Decimal as D
import requests

BASE = "https://api.crazyrouter.com/v1"

def client():
    s = requests.Session()
    s.trust_env = False
    return s

def catalog(wanted):
    with client() as s:
        r = s.get(BASE + "/models", headers={"Authorization": "Bearer " + os.environ["CRAZYROUTER_API_KEY"]}, timeout=(10, 40), allow_redirects=False)
        r.raise_for_status()
        names = {x["id"] for x in r.json()["data"]}
    return {name: name in names for name in wanted}

def request(model, prompt, mode="chat", **options):
    path = {"chat": "/chat/completions", "messages": "/messages", "responses": "/responses"}[mode]
    payload = {"model": model, **options}
    if mode == "responses":
        payload["input"] = prompt
    else:
        payload["messages"] = [{"role": "user", "content": prompt}]
    headers = {"Authorization": "Bearer " + os.environ["CRAZYROUTER_API_KEY"]}
    if mode == "messages":
        headers = {"x-api-key": os.environ["CRAZYROUTER_API_KEY"], "anthropic-version": "2023-06-01"}
    rec = {"model": model, "endpoint": BASE + path, "request": payload}
    start = time.perf_counter()
    try:
        with client() as s:
            r = s.post(BASE + path, headers=headers, json=payload, timeout=(10, 90), allow_redirects=False)
        rec["http"] = r.status_code
        if r.status_code == 200:
            data = r.json()
            rec.update(response_id=data.get("id"), usage=data.get("usage", {}))
            if mode == "messages":
                output = "".join(x.get("text", "") for x in data.get("content", []) if x.get("type") == "text")
                complete = data.get("stop_reason") == "end_turn"
                finish = data.get("stop_reason")
            elif mode == "responses":
                output = "".join(c.get("text", "") for item in data.get("output", []) if item.get("type") == "message" for c in item.get("content", []) if c.get("type") == "output_text")
                complete = data.get("status") == "completed"
                finish = data.get("status")
            else:
                choice = data["choices"][0]
                output = choice["message"].get("content") or ""
                complete = choice.get("finish_reason") == "stop"
                finish = choice.get("finish_reason")
            rec.update(output=output, complete=complete, finish=finish)
        else:
            rec["error"] = "HTTP_" + str(r.status_code)
    except (requests.RequestException, ValueError, KeyError, IndexError) as error:
        rec["error"] = type(error).__name__
    rec["seconds"] = round(time.perf_counter() - start, 3)
    return rec

def accepted(rec, expected):
    if not rec.get("complete"):
        return False
    try:
        return json.loads(rec["output"]) == expected
    except (ValueError, TypeError):
        return False

def emit(**data):
    print(json.dumps(data, ensure_ascii=False))

import base64
import hashlib
import io
from PIL import Image, ImageDraw

def fixture(red_count, blue_count):
    image = Image.new("RGB", (480, 240), "white")
    draw = ImageDraw.Draw(image)
    for i in range(red_count):
        draw.rectangle((20+i*100, 20, 75+i*100, 75), fill=(220, 20, 40))
    for i in range(blue_count):
        draw.ellipse((20+i*100, 140, 75+i*100, 195), fill=(20, 50, 220))
    buffer = io.BytesIO()
    image.save(buffer, format="PNG")
    return buffer.getvalue()

models = ["gemini-2.5-flash", "gpt-4.1-nano"]
available = catalog(models)
tests = []
rows = []
fixtures = []
for red, blue in [(2, 3), (3, 1)]:
    data = fixture(red, blue)
    image = Image.open(io.BytesIO(data))
    assert image.size == (480, 240) and image.getpixel((25, 25)) == (220, 20, 40)
    tests.append({"case": f"fixture {red} red / {blue} blue PNG", "passed": True})
    fixtures.append({"red_squares": red, "blue_circles": blue, "sha256": hashlib.sha256(data).hexdigest(), "bytes": len(data)})
    for model in models:
        if not available[model]:
            continue
        prompt = [{"type": "text", "text": 'Count the visible shapes. Return only a JSON object with integer keys red_squares and blue_circles. No Markdown.'},
                  {"type": "image_url", "image_url": {"url": "data:image/png;base64," + base64.b64encode(data).decode()}}]
        rec = request(model, prompt, max_tokens=1024)
        rec.update(case=f"{red} red / {blue} blue", passed=accepted(rec, {"red_squares": red, "blue_circles": blue}), fixture_sha256=hashlib.sha256(data).hexdigest())
        rows.append(rec)
emit(local_tests=tests, catalog=available, requests=rows, fixtures=fixtures,
     scope="Two synthetic images per route; no OCR, PDF, video, real-world visual accuracy, or latency percentile benchmark")

Sources and related guides#
Documentation checked November 4, 2026: OpenAI image understanding guide, Google image understanding guide. The test table describes gateway observations, not vendor-native account measurements.
- AI API Pricing Comparison: Count Only Usable Outputs
- OpenAI-Compatible Claude and Gemini: Normal and Streaming SDK Tests
- One API Key for Multiple AI Models: Catalog Access and Live Route Tests
- Lower AI API Token Use: A Paired Prompt-Compression Test in Python
- AI Guardrails in Python: Reject Invalid Outputs After Prompt Injection
FAQ#
Which model passed both fixtures?#
GPT-4.1 Nano passed both in this run.
Did Gemini 2.5 Flash fail to recognize the first image?#
A timeout prevented a scored answer; recognition accuracy cannot be inferred for that attempt.
Were public images used?#
No. The images were generated locally and sent as data URLs.
Was OCR tested?#
No. These images contain only colored geometric shapes.
Can this establish an overall vision winner?#
No. The sample is deliberately small and includes a transport timeout.
What was the acceptance rule?#
A completed reply had to parse as the exact JSON object for each image.
Last actually tested: November 4, 2026. This API-dependent article is due for review December 4, 2026.
Implementation Guides
Podcast
AI Dev Tools: The Crazyrouter Podcast
Short episodes for developers on AI APIs, gateways, cost control and coding tools.
Latest episodes
EP196 · Oct 29, 2026 · 6:53
AI API Security Posture — Turn Controls Into Continuous Evidence
A practical guide to AI API security posture: inventory exposure, verify controls continuously, protect keys and data, constrain tools, and turn security assumptions into evidence that operators can act on.
EP195 · Oct 28, 2026 · 7:21
AI API Policy Drift — Detect When Production Rules Stop Matching Intent
A practical guide to policy drift in AI APIs: version routing and safety rules, detect stale enforcement, compare intended and observed behavior, and restore control before small gaps become incidents.