 简体中文
 繁體中文
 English
 Français
 Русский
 日本語
 Tiếng Việt
 한국어
 Deutsch
 Español
 Italiano
 Português
 العربية
 ไทย
 Bahasa Indonesia
 Bahasa Melayu
 Türkçe
 Polski
 Nederlands
 Dansk
 Norsk
 Қазақша
Seedance and ByteDance Video AI 2026: API Queues, Costs, and Fallbacks
A developer guide to Seedance video AI integration with asynchronous queues, cost controls, prompt versioning, and model fallbacks.
Seedance and ByteDance Video AI 2026: API Queues, Costs, and Fallbacks#
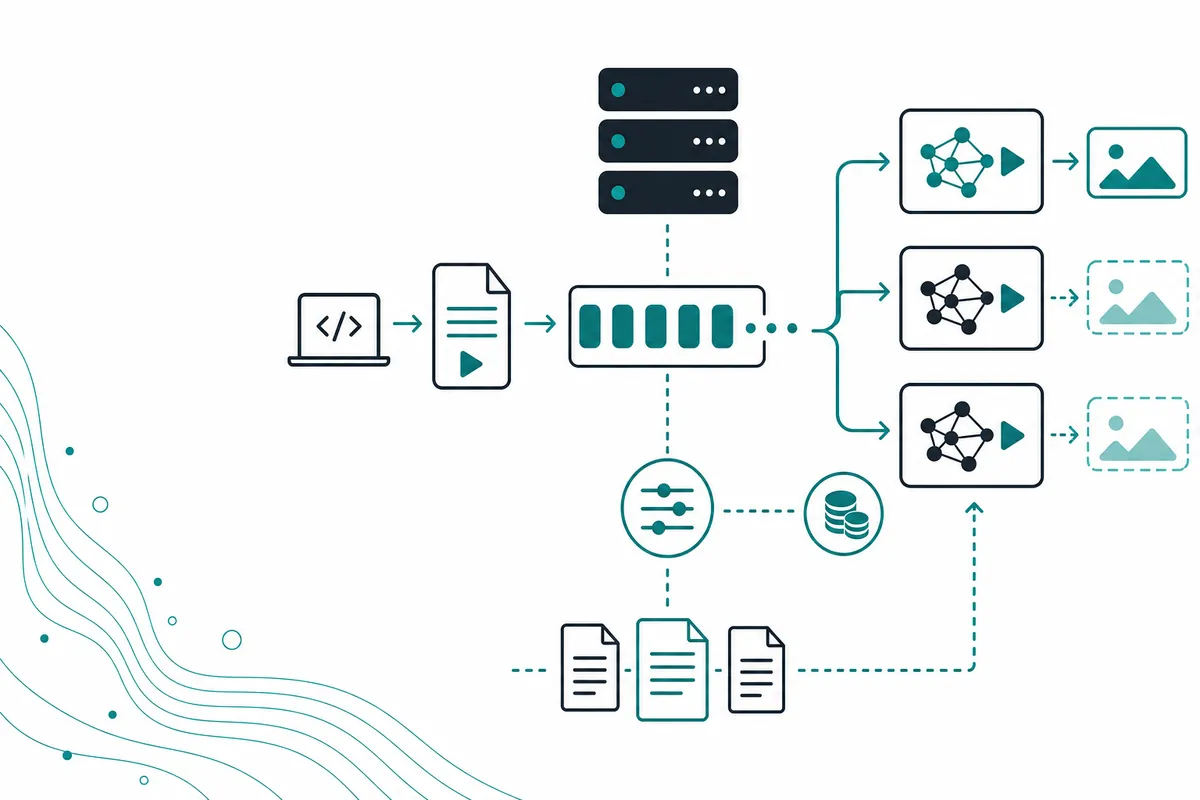
Seedance and ByteDance video AI workflows are a good example of why generative media applications need infrastructure, not just prompts. A reliable integration tracks jobs, assets, versions, moderation decisions, and cost from submission to delivery.
What is this topic?#
For developers, this topic sits at the intersection of model capability, API integration, and operating cost. The right implementation is not the one with the most impressive demo; it is the one that produces acceptable results repeatedly, exposes failures clearly, and stays within a known budget. Start by defining the task, the success metric, the maximum latency, and the data boundary.
Seedance and ByteDance Video AI 2026: API Queues, Costs, and Fallbacks vs alternatives#
A hosted creative interface is useful for exploration. An API pipeline is preferable for product generation, campaign variants, and repeatable batch jobs. Compared with text-only APIs, video systems have longer latency, larger artifacts, and more expensive retries, so queue design matters as much as model quality.
A useful decision rule is simple: choose the smallest model or tool that passes your evaluation set. Keep a premium path for difficult cases, but do not send every request through the most expensive option. Log the model, prompt version, latency, token or media usage, retry count, and final reviewer outcome. This turns a subjective comparison into an engineering decision.
How to use it with an API#
The examples below use an OpenAI-compatible shape. Replace the model identifier with the exact name shown in the current Crazyrouter model catalog, keep the key on a server, and add timeouts plus structured error handling in production.
const res = await fetch("https://crazyrouter.com/v1/video/generations", {
  method: "POST",
  headers: { "Authorization": `Bearer ${process.env.CRAZYROUTER_API_KEY}`, "Content-Type": "application/json" },
  body: JSON.stringify({ model: "seedance", prompt: "A clean product reveal, locked camera, 6 seconds" })
});
if (!res.ok) throw new Error(await res.text());
console.log(await res.json());
For production, add an idempotency key to asynchronous jobs, validate user input before submission, and persist the provider response. A failed request should be classified as a transient transport error, a rate limit, an invalid parameter, a policy rejection, or a permanent input failure. Only the first category should be retried automatically, and retries need exponential backoff with a hard cap.
Pricing breakdown#
Model pricing may depend on seconds, resolution, or generation mode. Use a planning table that includes official list price, routed price, queue time, retry rate, and storage. Crazyrouter can centralize supported model calls and fallbacks, but always verify current Seedance availability, endpoint names, and price on the live product page.
| Cost dimension | Official provider route | Crazyrouter route |
|---|---|---|
| Authentication | Provider account and key | Crazyrouter account and key |
| Billing | Provider's current unit price | Current routed model price |
| Model choice | Provider-specific | Supported multi-model catalog |
| Fallbacks | Usually application-managed | Can be centralized with policy |
| Best for | First-party features | Comparison, routing, and one API surface |
Do not copy a historical price into a long-lived budget. Recheck the official pricing page and the Crazyrouter pricing page before launch. The number that matters is effective cost per successful task: total spend divided by accepted outputs, including retries and rejected generations.
Implementation checklist#
- Define a small representative evaluation set before changing providers.
- Keep credentials server-side and separate local, staging, production, and CI access.
- Set request, token, media-duration, concurrency, and monthly budget limits.
- Record model, version, latency, usage, retries, and outcome for every request.
- Add a cheaper first pass and a premium escalation path only when quality requires it.
- Review failures weekly and remove prompts or workflows that create avoidable retries.
FAQ#
What is Seedance used for?#
It is used for AI video generation workflows such as product scenes, social clips, storyboards, and creative variants.
Why do video APIs need queues?#
Generation is asynchronous and may take longer than an ordinary HTTP request; queues provide retries, concurrency, and status tracking.
How can I control Seedance cost?#
Use preview resolutions, cap duration, deduplicate prompts, and stop retrying permanent input errors.
What should a fallback do?#
A fallback should preserve the job contract, record the selected model, and make quality differences visible to reviewers.
Can one API key access several video models?#
A compatible gateway may provide that pattern for supported models, subject to account access and model availability.
Summary#
The practical way to evaluate Seedance video AI, ByteDance video AI API, Seedance API pricing is to combine capability, reliability, and effective cost. Build a small test set, keep the integration observable, and make budget and fallback decisions explicit. If you want to compare supported models behind one developer-friendly interface, visit Crazyrouter.