 简体中文
 繁體中文
 English
 Français
 Русский
 日本語
 Tiếng Việt
 한국어
 Deutsch
 Español
 Italiano
 Português
 العربية
 ไทย
 Bahasa Indonesia
 Bahasa Melayu
 Türkçe
 Polski
 Nederlands
 Dansk
 Norsk
 Қазақша
Building an AI SaaS on a Budget in 2026: Architecture and API Cost Guide
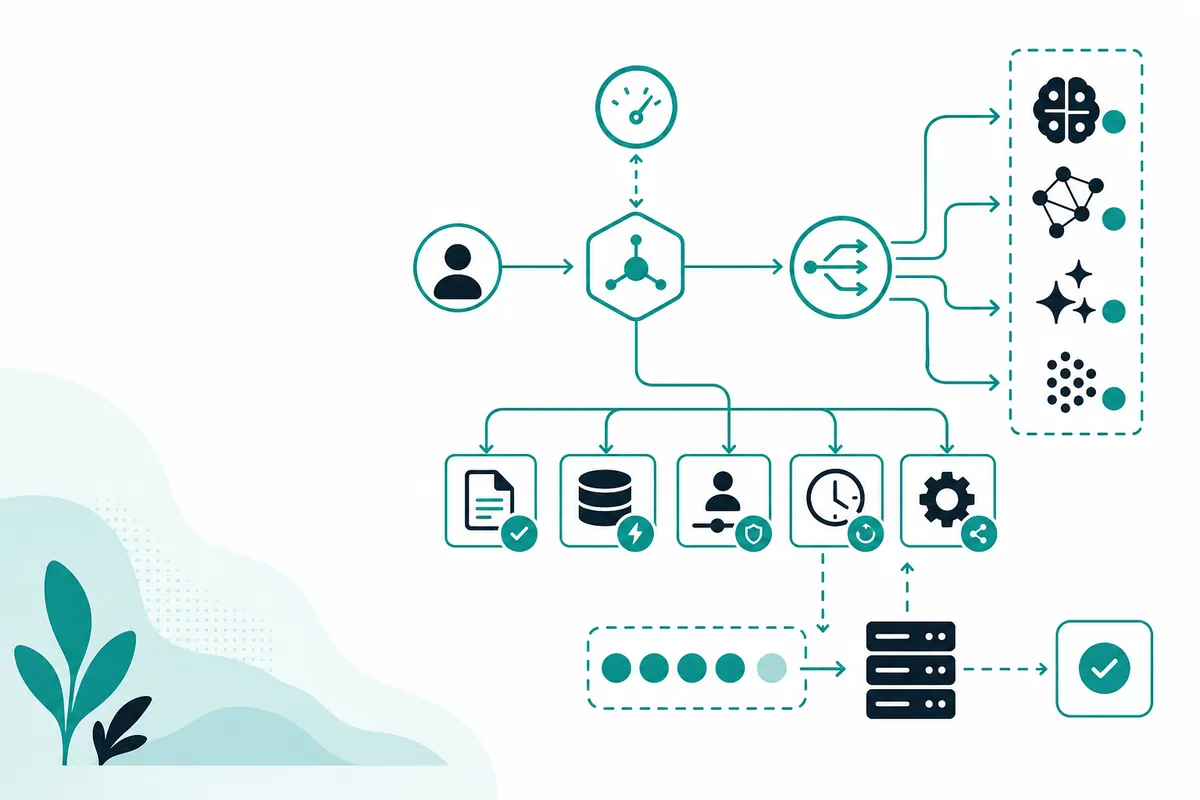
Learn how to launch an AI SaaS economically using model routing, usage limits, caching, asynchronous jobs, and a unified AI API.
Building an AI SaaS on a Budget in 2026: Architecture and API Cost Guide#
Learn how to launch an AI SaaS economically using model routing, usage limits, caching, asynchronous jobs, and a unified AI API. For developers, the useful question is not whether a model looks impressive in a demo. It is whether the model can be called reliably, evaluated honestly, and operated within a predictable budget. This guide focuses on those practical decisions.
What is building AI SaaS on a budget?#
Building an AI SaaS on a budget means optimizing the full cost of a successful user outcome: inference, retries, storage, moderation, observability, support, and payment fees. The cheapest token is not useful if it produces unusable output or causes expensive rework. For developers, the useful question is not whether a model looks impressive in a demo. It is whether the model can be called reliably, evaluated honestly, and operated within a predictable budget. This guide focuses on those practical decisions.
building AI SaaS on a budget vs alternatives#
Direct provider billing may be cheapest for one model at scale, but a gateway is often faster for an MVP because it reduces integration work and enables model comparison. Open models can reduce variable cost when utilization is high, while managed models reduce infrastructure burden.
| Option | Strength | Trade-off | Best for |
|---|---|---|---|
| building AI SaaS on a budget | Focused capability and current ecosystem | Limits vary by endpoint | Teams validating this workload |
| Fast general model | Lower latency and cost | May need more prompting | High-volume tasks |
| Premium frontier model | Strong quality and reasoning | Higher unit cost | Difficult or high-value tasks |
| Crazyrouter | One API surface and model choice | Requires evaluation and routing policy | Multi-model production apps |
How to use building AI SaaS on a budget with code#
The examples below use an OpenAI-compatible request shape. Model IDs and optional parameters can change, so verify the current model catalog and endpoint documentation before shipping.
cURL#
curl https://crazyrouter.com/v1/chat/completions \
  -H "Authorization: Bearer $CRAZYROUTER_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{"model":"building-ai-saas-on-a-budget","messages":[{"role":"user","content":"Give a concise, verifiable answer and list assumptions."}]}'
Python#
from fastapi import FastAPI
import os, requests
app=FastAPI()
@app.post("/generate")
def generate(prompt:str):
    if len(prompt)>4000: return {"error":"prompt_too_long"}
    r=requests.post("https://crazyrouter.com/v1/chat/completions", headers={"Authorization":"Bearer "+os.environ["CRAZYROUTER_API_KEY"]}, json={"model":"gpt-5-mini","messages":[{"role":"user","content":prompt}],"max_tokens":800})
    return r.json()
Node.js#
const cache = new Map(); async function generate(prompt) { if (cache.has(prompt)) return cache.get(prompt); const result = await ask("gpt-5-mini", prompt); cache.set(prompt, result); return result; }
In production, add a request ID, timeout, structured logs, input limits, output validation, and a bounded retry policy. Never expose the API key in browser JavaScript. For tools or function calling, validate every argument before execution.
Pricing breakdown#
Official pricing changes frequently and can differ by region, plan, modality, context length, and cached-input policy. Use the provider's current pricing page for the authoritative number. For a practical comparison, record the following: input cost, output cost, media or job cost, free quota, minimum spend, rate limits, and the cost of retries.
| Cost item | Official provider path | Crazyrouter path |
|---|---|---|
| Model usage | Provider list price and plan rules | Check live model pricing at Crazyrouter |
| Multiple models | Separate accounts, keys, and billing | One compatible API surface for supported models |
| Development tests | Often spread across provider consoles | Route experiments through one project budget |
| Production control | Provider-specific quotas | Centralize routing, limits, and fallback policy |
A simple monthly estimate is: successful requests × average input/output cost + media cost + retries + infrastructure. Start with a small budget cap, measure cost per accepted result, and only then increase traffic. For video and image generation, draft with a cheaper model and reserve premium generation for approved prompts.
Production checklist#
- Pin a tested model ID and keep a fallback mapping.
- Track latency, empty responses, refusals, retries, and user acceptance.
- Add per-user and per-tenant quotas before launch.
- Store prompts and outputs according to your privacy policy.
- Build a small evaluation set from real tasks, not only benchmark examples.
- Re-check pricing and model availability before every major release.
Frequently asked questions#
Q: What is the biggest AI SaaS cost mistake?
A: Allowing unlimited generation and retries before measuring cost per active user and setting product-level limits.
Q: Should an MVP use one model or many?
A: Start with one reliable default plus one tested fallback; add routing only when data shows a real quality or cost benefit.
Summary#
building AI SaaS on a budget is best evaluated as part of a complete application workflow: prompt design, validation, retries, monitoring, and cost controls all affect the result. If you want to compare several models without maintaining a separate integration for each one, explore Crazyrouter and start with a measured, low-risk pilot.