 简体中文
 繁體中文
 English
 Français
 Русский
 日本語
 Tiếng Việt
 한국어
 Deutsch
 Español
 Italiano
 Português
 العربية
 ไทย
 Bahasa Indonesia
 Bahasa Melayu
 Türkçe
 Polski
 Nederlands
 Dansk
 Norsk
 Қазақша
Kimi K3 vs Claude Fable 5: Verification Depth or Faster Delivery?
A live four-task API benchmark comparing Kimi K3 and Claude Fable 5 across mathematical verification, physics, executable Python, constraint reasoning, latency, and output limits.
Kimi K3 vs Claude Fable 5: Verification Depth or Faster Delivery?#
A final answer can be correct while the derivation is not. A code response can return HTTP 200 while ending halfway through a function. This benchmark was designed around those production failures rather than a generic intelligence score.
The trade-off in one sentence#
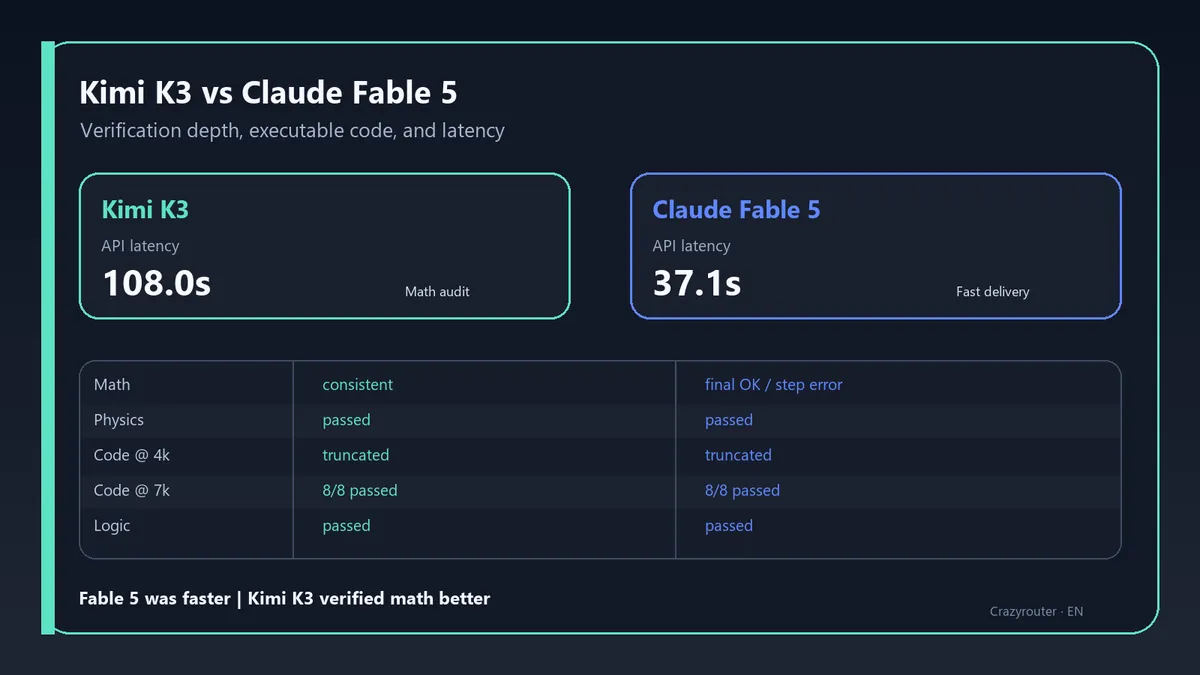
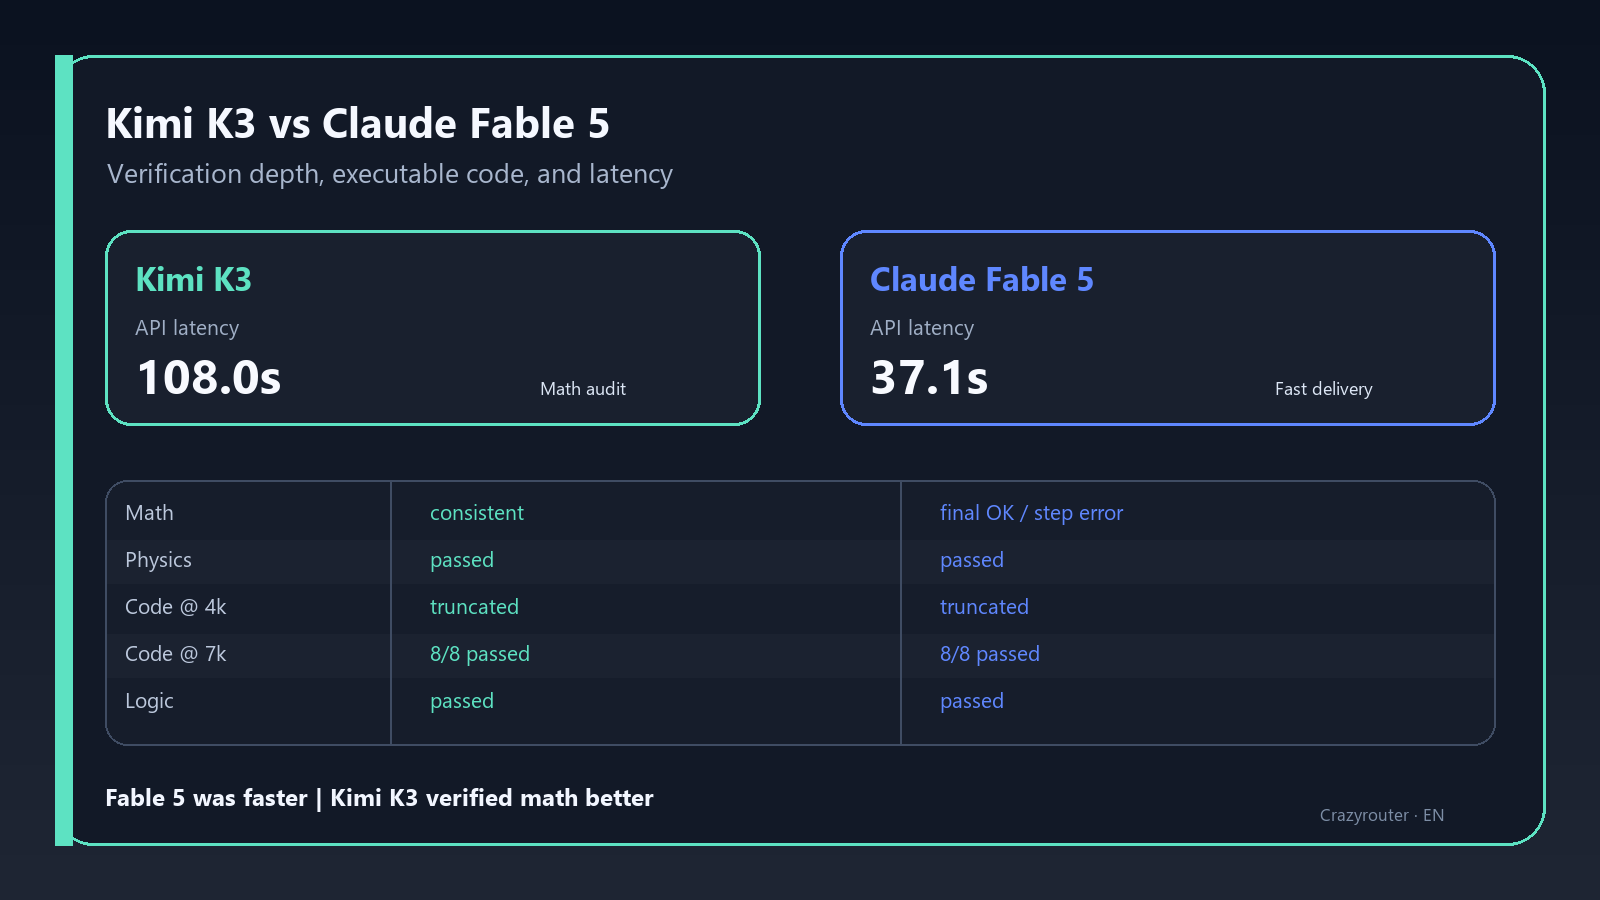
Fable 5 averaged 37.1 seconds in the first round, compared with 108.0 seconds for Kimi K3. Kimi K3 produced the stronger mathematical audit trail; Fable 5 delivered the same core result faster but made an intermediate arithmetic error.
Observed results#
| Task | Kimi K3 | Claude Fable 5 |
|---|---|---|
| HHTH probability | Passed | Final answer passed; intermediate arithmetic failed |
| Collision and spring | Passed | Passed |
| Python aggregation | Truncated at 4k; passed at 7k | Truncated at 4k; passed at 7k |
| Scheduling logic | Passed | Passed |
Mean latency — Kimi K3: 108.0 s
Mean latency — Claude Fable 5: 37.1 s
The math task separated correctness from consistency#
The biased-coin task asked for the expected number of tosses before HHTH appears with P(H)=3/5 and overlap enabled. The correct result is:
E[T] = 715/54 ≈ 13.2407407407
E1 = 625/54
E2 = 475/54
E3 = 170/27
Kimi K3 cross-checked the automaton with a border formula and a fair-coin special case. Fable 5 reached the correct final fraction but reported two intermediate states that did not satisfy its own equations.
How the benchmark was run#
Test date: 2026-07-17
Base URL: https://cn.crazyrouter.com/v1
Endpoint: POST /v1/chat/completions
Models: kimi-k3, claude-fable-5
temperature: 0.2
Round 1 max_tokens: 4000
Coding retry max_tokens: 7000
The same prompts and acceptance criteria were used for both models. HTTP 200 alone was not treated as success: final values, intermediate states, finish_reason, executable Python, and identical assertions were checked.
Both models handled the physics boundary correctly#
The two-stage problem combined a completely inelastic collision with friction and spring compression. Both models reached:
Post-collision speed: 2.4 m/s
Energy lost in collision: 21.6 J
Maximum compression: about 0.2212 m
Both models found the spring compression near 0.2212 m and the unique schedule Eli, Bo, Ada, Cici, Deng.
The first coding failure was a budget failure#
The Python function had to deduplicate retries by request_id, parse ISO-8601 timestamps, filter the half-open interval [start,end), aggregate token and latency metrics, and apply a multi-key sort.
Round 1, max_tokens=4000:
Kimi K3 finish_reason=length
Fable 5 finish_reason=length

Retry, max_tokens=7000:
Kimi K3: 145.2 s, 5199 completion tokens, 8/8 assertions
Fable 5: 46.6 s, 3710 completion tokens, 8/8 assertions
At 4,000 output tokens both responses ended with finish_reason=length. At 7,000 tokens both Python programs passed the same eight assertions, while Fable 5 remained substantially faster.
What the token profile means in production#
Kimi K3 completion tokens: 13,975
Kimi K3 reasoning tokens: about 12,500
Fable 5 completion tokens: 10,187
Kimi K3 reported roughly 12,500 reasoning tokens in round one. The additional reasoning aligned with better mathematical checking, but also with higher latency and less room for visible code.
Constraint reasoning ended in the same unique schedule#
Both models found the same unique weekday assignment:
| Monday | Tuesday | Wednesday | Thursday | Friday |
|---|---|---|---|---|
| Eli | Bo | Ada | Cici | Deng |
Both models found the spring compression near 0.2212 m and the unique schedule Eli, Bo, Ada, Cici, Deng.
A practical routing policy#
- Use Fable 5 first for high-volume, testable code
- Keep Kimi K3 for exact derivations and intermediate-state audits
- Gate long code on finish_reason and executable tests
What this test cannot prove#
This is a small benchmark, not a universal leaderboard. A production evaluation should repeat each task category 20–50 times and measure success rate, truncation rate, time to first token, P50/P95/P99 latency, completion tokens, and cost per accepted result.
Takeaway#
The useful distinction is not strong versus weak. Fable 5 was the faster delivery route; Kimi K3 was the more careful mathematical route in this sample.
from openai import OpenAI

client = OpenAI(api_key="YOUR_API_KEY", base_url="https://cn.crazyrouter.com/v1")
response = client.chat.completions.create(
    model="kimi-k3",
    temperature=0.2,
    max_tokens=4000,
    messages=[{"role": "user", "content": "YOUR_TEST_PROMPT"}],
)
print(response.model, response.choices[0].finish_reason, response.usage)
Canonical article: https://crazyrouter.com/en/blog/kimi-k3-vs-claude-fable-5-hard-reasoning-benchmark-2026-en