 简体中文
 繁體中文
 English
 Français
 Русский
 日本語
 Tiếng Việt
 한국어
 Deutsch
 Español
 Italiano
 Português
 العربية
 ไทย
 Bahasa Indonesia
 Bahasa Melayu
 Türkçe
 Polski
 Nederlands
 Dansk
 Norsk
 Қазақша
Gemini 2.5 Flash API Pricing and How to Call It
Compare Gemini 2.5 Flash input, output, and cached-token prices, estimate a request budget, and make an OpenAI-compatible call with Python, Node.js, or cURL.
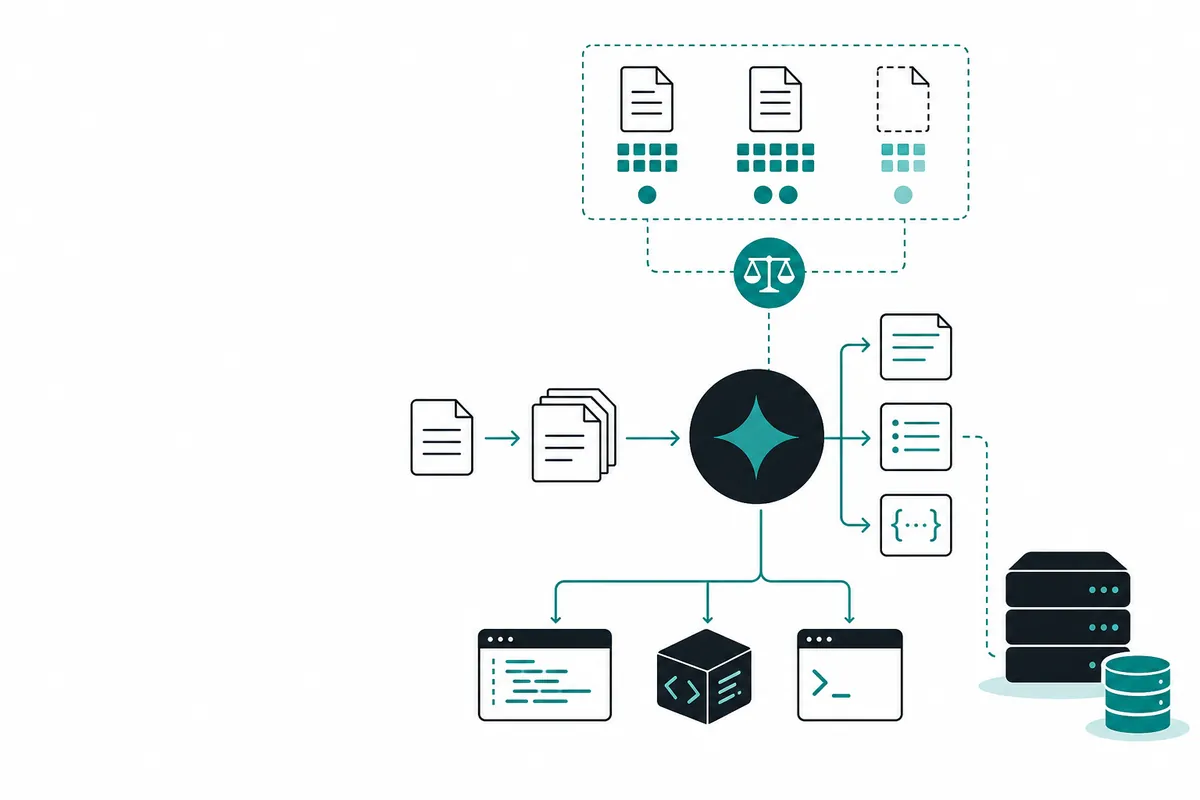
Gemini 2.5 Flash API pricing and how to call it comes down to two separate checks: the rate for your request type and the exact endpoint your key belongs to. As of 2026-10, the published comparison lists Google reference rates of 2.50 output per million tokens, versus Crazyrouter rates of 1.38. For the gateway examples below, use model gemini-2.5-flash with base URL https://api.crazyrouter.com/v1. A Google consumer subscription is not the credential for this endpoint.
What is Gemini 2.5 Flash?#
Gemini 2.5 Flash is a Google model in the Flash family, aimed at balancing response quality and efficiency. It is a candidate for summaries, extraction, conversational applications, and other workloads where a larger reasoning model may be unnecessary. Select it from actual task results, not from the word “Flash” alone.
The model overview describes the catalogue entry. The associated pricing comparison lists a 1.0M-token context window, but a listed limit is not a recommendation to fill every request. Long inputs increase cost and can make relevant information harder to retrieve. Test realistic document sizes before adopting the maximum.
Also keep Flash, Flash-Lite, and image-generation variants separate. Similar names do not imply interchangeable API capabilities. The examples in this article request a text response; they do not demonstrate image generation, native audio, grounding, or every Google-specific parameter.
Gemini 2.5 Flash API pricing and how to call it#
The following figures come from the Gemini 2.5 Flash pricing page, checked on 2026-10-17. Amounts are USD per million tokens. Provider reference figures can lag official changes; validate the final schedule for your account and request type.
| Route | Input | Output | Cached input | Scope |
|---|---|---|---|---|
| Google AI reference | $0.30 | $2.50 | $0.03 | Published standard comparison |
| Google Vertex AI reference | $0.30 | $2.50 | $0.03 | Published base comparison; confirm region |
| Crazyrouter | $0.165 | $1.38 | $0.044 | Gateway schedule; verify cache eligibility |
| Google AI batch reference | $0.15 | $1.25 | Not quoted here | Asynchronous jobs, not a real-time equivalent |
Do not apply the ordinary-input discount to every billing item. In this snapshot, the gateway cached-input rate is higher than the listed Google cached-input reference. The asynchronous batch reference is also below the gateway's real-time rate. Which route costs less depends on the workload and its latency requirements, not a single promotional percentage.
For provider-side conditions, consult Google's pricing documentation. Use the pricing overview when comparing other models, keeping input and output quantities fixed.
How much would a small request cost?#
For an illustrative request with 2,000 input tokens and 500 output tokens, multiply each quantity by its corresponding rate and divide by one million. Using the displayed gateway rates gives 0.00069 for output, or approximately 0.00185 for the same quantities.
Those are calculated examples, not measured lengths of the sample prompt below. Ten thousand such gateway requests would be approximately $10.20 before other billable features, retries, taxes, or account-specific adjustments. Character count is not token count, and visible answer length may not capture all billable generation usage.
Keep a request-level usage record and reconcile it with the account ledger. A timeout may occur after the upstream has already done work, so repeated requests can change the effective cost. Cap retries and track cost per accepted result rather than reporting only the cheapest successful response.
How does Flash compare with alternatives?#
| Choice | Evaluate it for | Trade-off to test |
|---|---|---|
| Gemini 2.5 Flash | Routine summaries and mixed application tasks | Accuracy at your target latency |
| Gemini 2.5 Flash-Lite | Lightweight classification and extraction | Whether harder inputs need escalation |
| Gemini 2.5 Pro | More demanding analysis | Whether improved results justify extra cost |
| Another provider's model | Independent quality or resilience baseline | Different parameters and response behavior |
Use a fixed set of representative inputs, with expected outcomes defined before testing. A cheaper model that needs repeated correction can cost more per completed job. Likewise, a larger model is unnecessary when a smaller one consistently satisfies your acceptance criteria.
How do you call Gemini 2.5 Flash?#
Create a server-side gateway key and expose it to your process as CRAZYROUTER_API_KEY. Do not embed it in a browser bundle or send a Google key to this gateway. Install the OpenAI SDK for Python or Node.js if choosing those examples; cURL needs no SDK.
Python#
import os
from openai import OpenAI

client = OpenAI(
    api_key=os.environ["CRAZYROUTER_API_KEY"],
    base_url="https://api.crazyrouter.com/v1",
)
reply = client.chat.completions.create(
    model="gemini-2.5-flash",
    messages=[{"role": "user", "content": "Reply with the word ready."}],
    max_tokens=64,
)
print(reply.choices[0].message.content)
Node.js#
import OpenAI from "openai";

const client = new OpenAI({
  apiKey: process.env.CRAZYROUTER_API_KEY,
  baseURL: "https://api.crazyrouter.com/v1",
});
const reply = await client.chat.completions.create({
  model: "gemini-2.5-flash",
  messages: [{ role: "user", content: "Reply with the word ready." }],
  max_tokens: 64,
});
console.log(reply.choices[0].message.content);
cURL#
curl --fail-with-body https://api.crazyrouter.com/v1/chat/completions \
  -H "Authorization: Bearer $CRAZYROUTER_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{"model":"gemini-2.5-flash","messages":[{"role":"user","content":"Reply with the word ready."}],"max_tokens":64}'
All three snippets were executed on 2026-10-17. Python printed ready, Node.js printed Ready., and cURL returned Ready. with model gemini-2.5-flash, 7 prompt tokens, and 2 completion tokens. Each process exited successfully; the separate HTTP probe returned status 200. These are basic text checks, not a latency benchmark or a test of every model feature.
What should you check before deploying?#
A basic completion verifies only a small part of an application. Test streaming termination, structured-output validation, and tool calls separately if your workflow needs them. OpenAI-compatible syntax does not guarantee support for every Google-native feature.
For an authentication error, check the credential issuer and host. For a model error, compare the exact ID with your account's available models. For a truncated response, inspect the finish reason before increasing the output budget. Keep request identifiers for support, but redact credentials and sensitive payloads from shared logs.
FAQ#
Is Gemini 2.5 Flash API access included in Google AI Pro?#
A consumer subscription should not be treated as general API billing. Review any specific developer benefits separately; the gateway examples require a gateway account and key.
Is the model ID gemini-2-5-flash or gemini-2.5-flash?#
The API examples use gemini-2.5-flash. Hyphenated web-page slugs are URLs, not necessarily valid request identifiers.
Does cached input always cost less through the gateway?#
Not relative to every provider: the October comparison lists 0.03 Google reference per million tokens. Confirm cache support and actual hits before budgeting around either rate.
Can I use these examples to generate images?#
These snippets request text chat completions, not image output. Choose a documented image model and endpoint when your application needs image generation.
Why can my bill exceed the visible output estimate?#
Retries, additional billable generation, and feature-specific charges can change the total. Use response usage and the billing ledger rather than counting words in the displayed answer.
Summary#
Choose the rate that matches your execution mode, use the exact model ID, and validate usage on a small workload. If gateway access suits your application, register an account, set a bounded test budget, and compare accepted results before scaling traffic.
<!-- [crazyrouter](https://docs.crazyrouter.com/en/introduction)-related-links -->