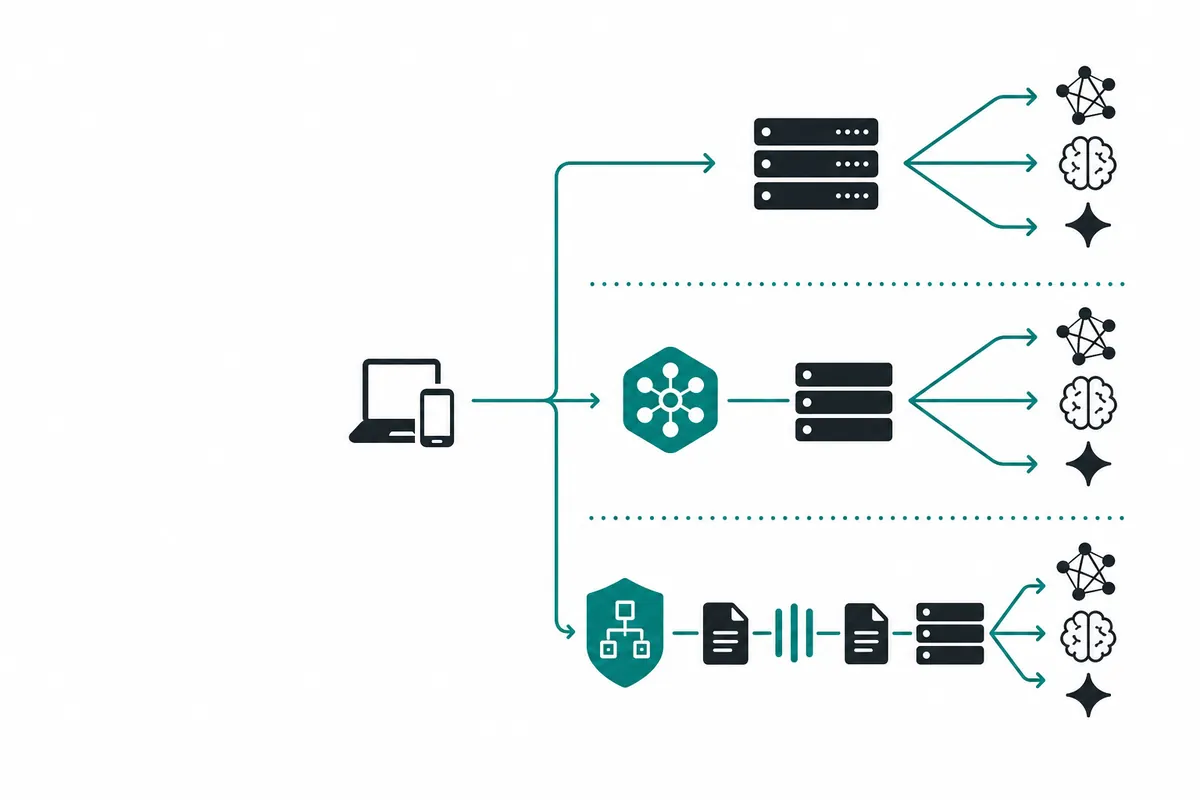
AI API Gateway vs AI API Aggregator vs Direct Model APIs: A Production Decision Guide
A production decision guide comparing direct model APIs, AI API aggregators, and AI API gateways with live Crazyrouter API evidence from July 2, 2026.
Model updates, integration guides, pricing breakdowns, and tool workflows for developers and teams.

A production decision guide comparing direct model APIs, AI API aggregators, and AI API gateways with live Crazyrouter API evidence from July 2, 2026.

A production-focused Claude Sonnet 5 vs GPT-5.4 comparison using live Crazyrouter API evidence from July 2, 2026, including model availability, response IDs, JSON output behavior, token usage, and routing advice.

We ran a live OCR benchmark for youtu-vita on eight image-understanding tasks, including documents, receipts, UI screenshots, rotated pages, scene text, and low-resolution small text. Here are the actual results, latency numbers, weak spots, and what they mean for production OCR workflows.

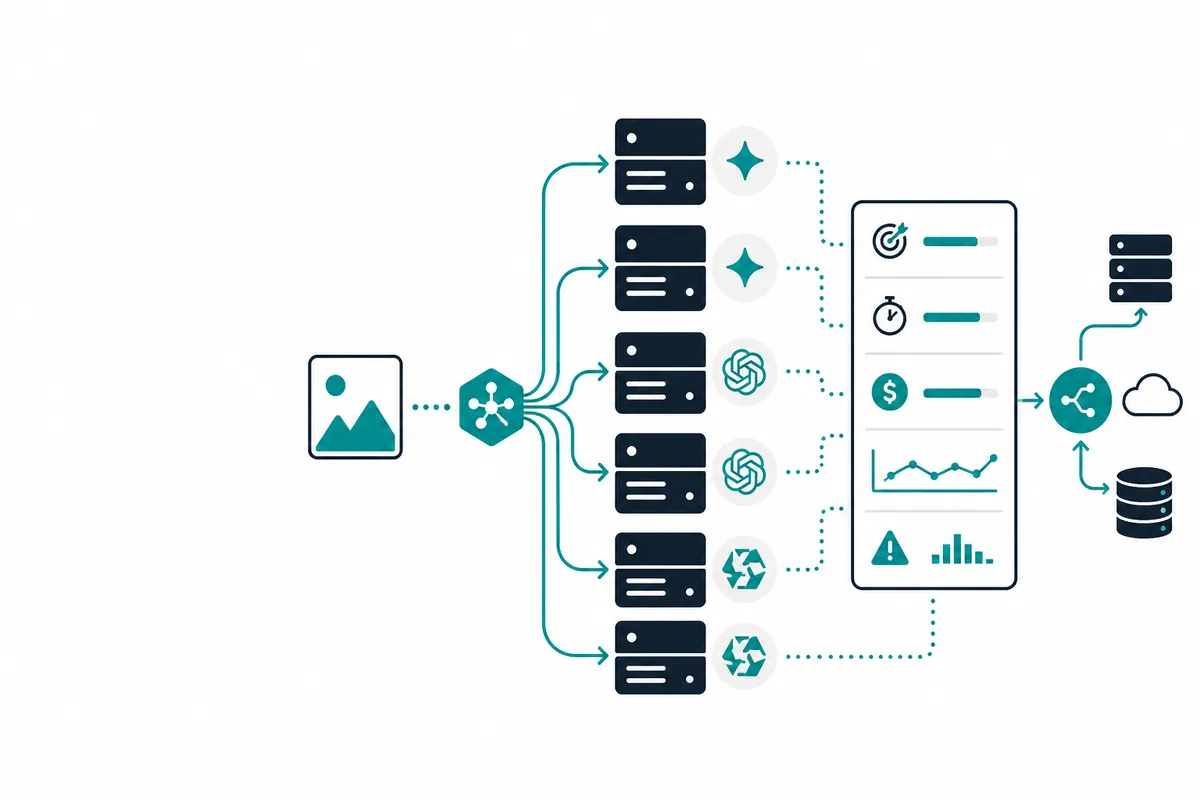
A practical benchmark of Gemini 2.5 Flash, Gemini 2.5 Flash Lite, GPT-4.1 Mini, GPT-4.1 Nano, Qwen3 VL Flash, and Qwen3 VL Plus for image understanding APIs, covering accuracy, latency, cost per successful image, usage signals, failure modes, and production routing advice.

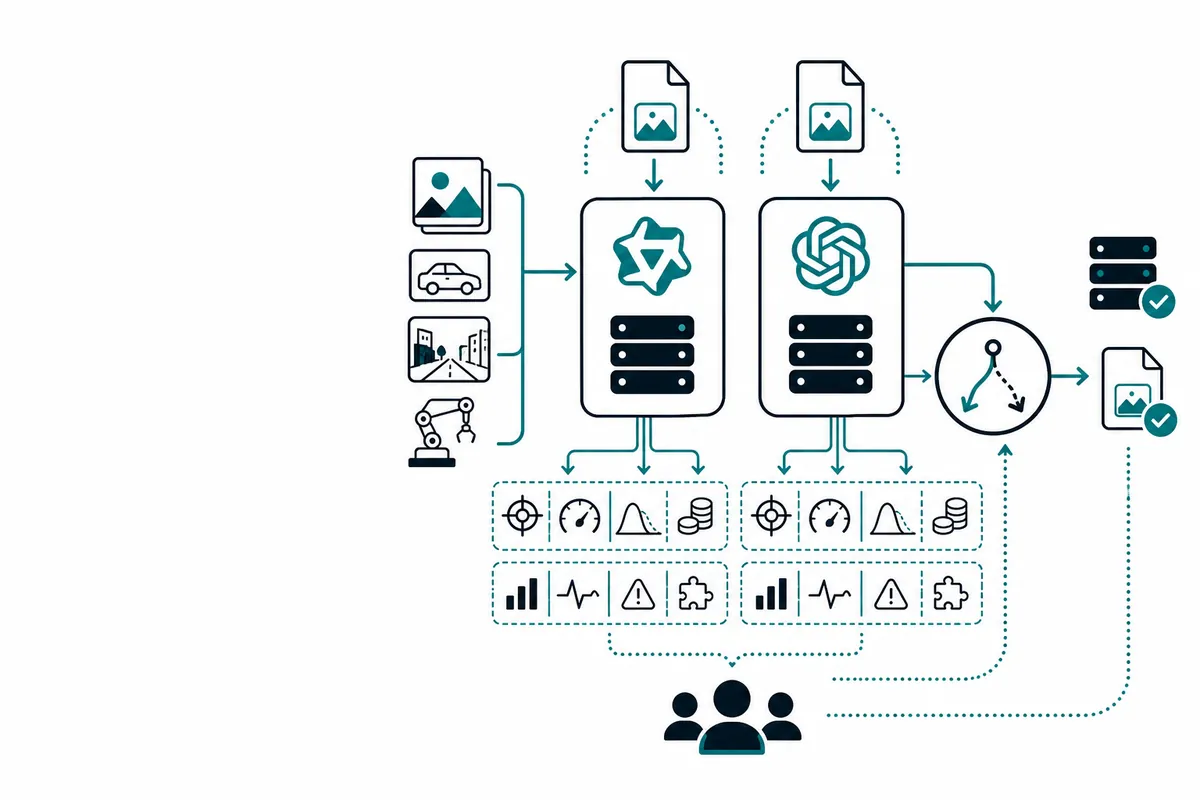
A practical, user-centric benchmark comparing qwen3-vl-flash and qwen3-vl-plus for vision API workloads: real image recognition accuracy, latency, tail latency, cost per successful image, usage signals, failure modes, and production routing advice.

A practical, user-centric benchmark comparing qwen3-vl-flash and gpt-4.1-nano for vision API workloads: real image recognition accuracy, latency, tail latency, cost per successful image, usage signals, failure modes, and production routing advice.

A practical, user-centric benchmark comparing qwen3-vl-flash and gpt-4.1-mini for vision API workloads: real image recognition accuracy, latency, tail latency, cost per successful image, usage signals, failure modes, and production routing advice.

A practical, user-centric benchmark comparing gpt-4.1-nano and qwen3-vl-plus for vision API workloads: real image recognition accuracy, latency, tail latency, cost per successful image, usage signals, failure modes, and production routing advice.